原文
GPT Image 2 · en
Scene:
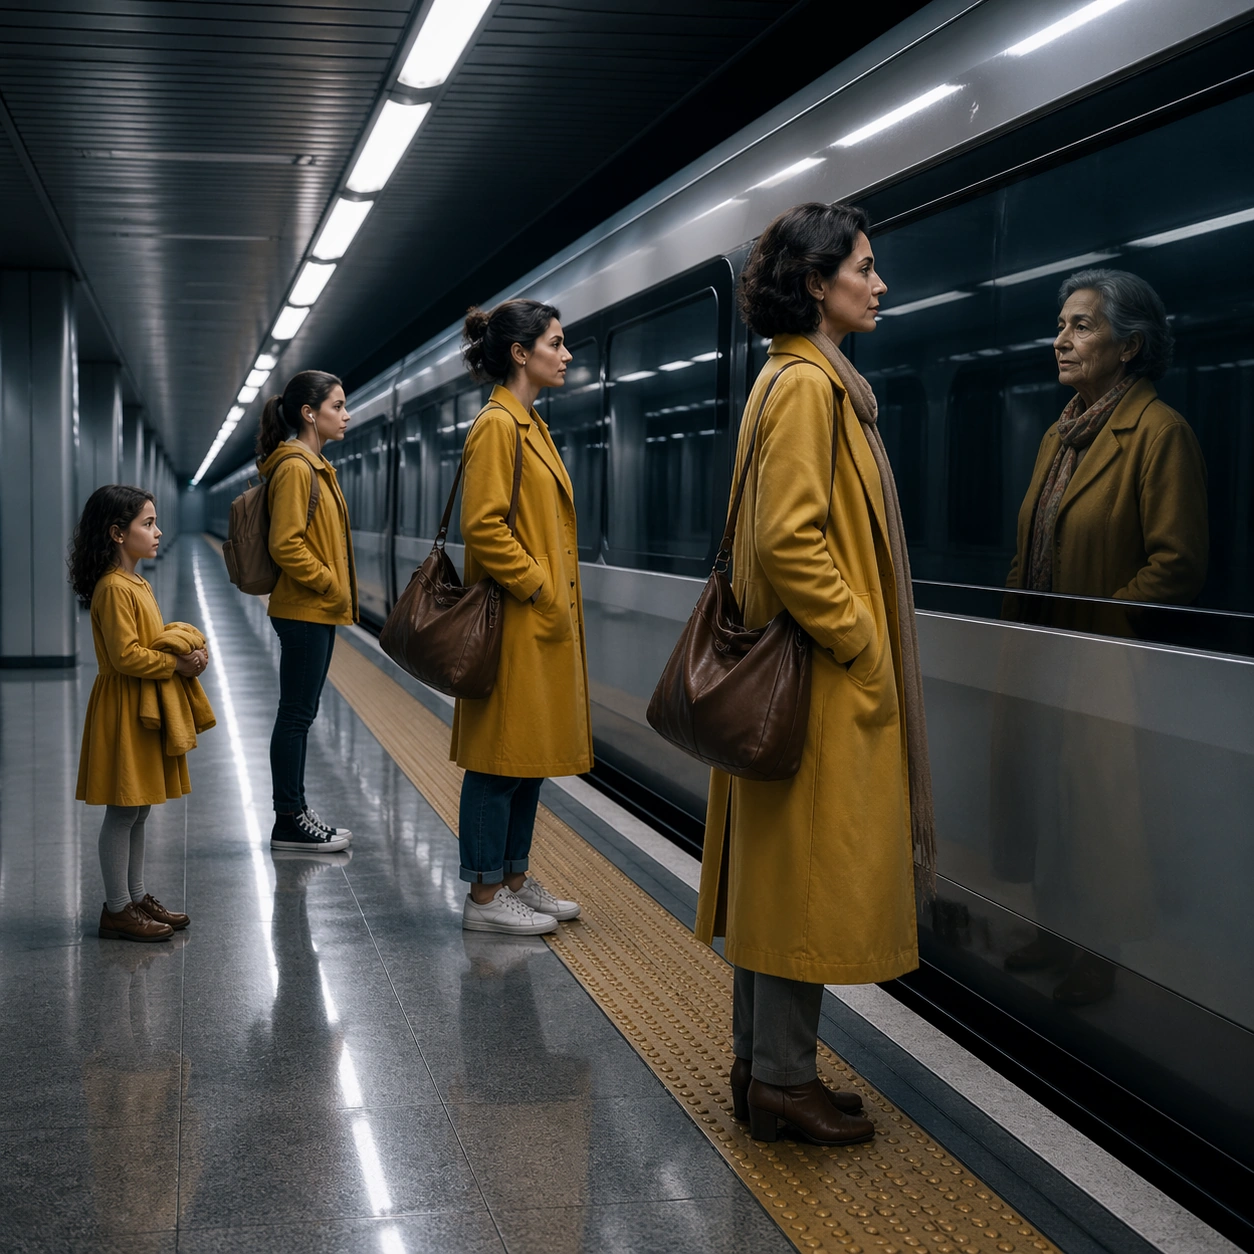
A square underground subway platform rendered as a polished editorial image, viewed along the platform edge with strong perspective lines, glossy floor reflections, cool fluorescent light, and a train window acting as a long horizontal mirror. The space is clean and cinematic, with no readable signage or route information.

Subject:
Show the same woman at five life stages distributed along the platform: small child holding a folded coat, teenager listening quietly, young adult with a travel bag, middle-aged adult looking into the train window, and elderly version reflected inside the dark glass. Preserve identity through the same high cheekbones, dark arched brows, short chin, and mustard yellow coat motif adapted by age. Each version should appear at a different depth point while still reading as one person across time.

Important details:
The subway platform must behave like one continuous architectural space. Reflections in the train window and floor should be plausible, with no duplicate bodies in impossible places. The time-split should be obvious through pose, scale, age, and costume changes, not through text. Keep facial continuity stronger than clothing differences.

Use case:
Mirror Worlds single study 6/8, testing life-stage identity consistency along a reflective subway platform without references.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no crowded commuters, no route numbers, no advertising posters, no inconsistent face, no train-brand marks, no warped platform geometry.
使い方
- パラメータを含む元のプロンプト全体をコピーします。
- 被写体、文字、構図を自分の要件に置き換えます。
- 対応する外部ツールで使用し、利用条件と結果を確認します。
開始前の確認
- 参考画像の要否を確認してください。互換モデルの表示は、そのモデルでの生成実績を意味しません。
- 名前、数値、画像内の文字を確認します。モデルの版で結果は変わります。