原文
GPT Image 2 · en
Scene:
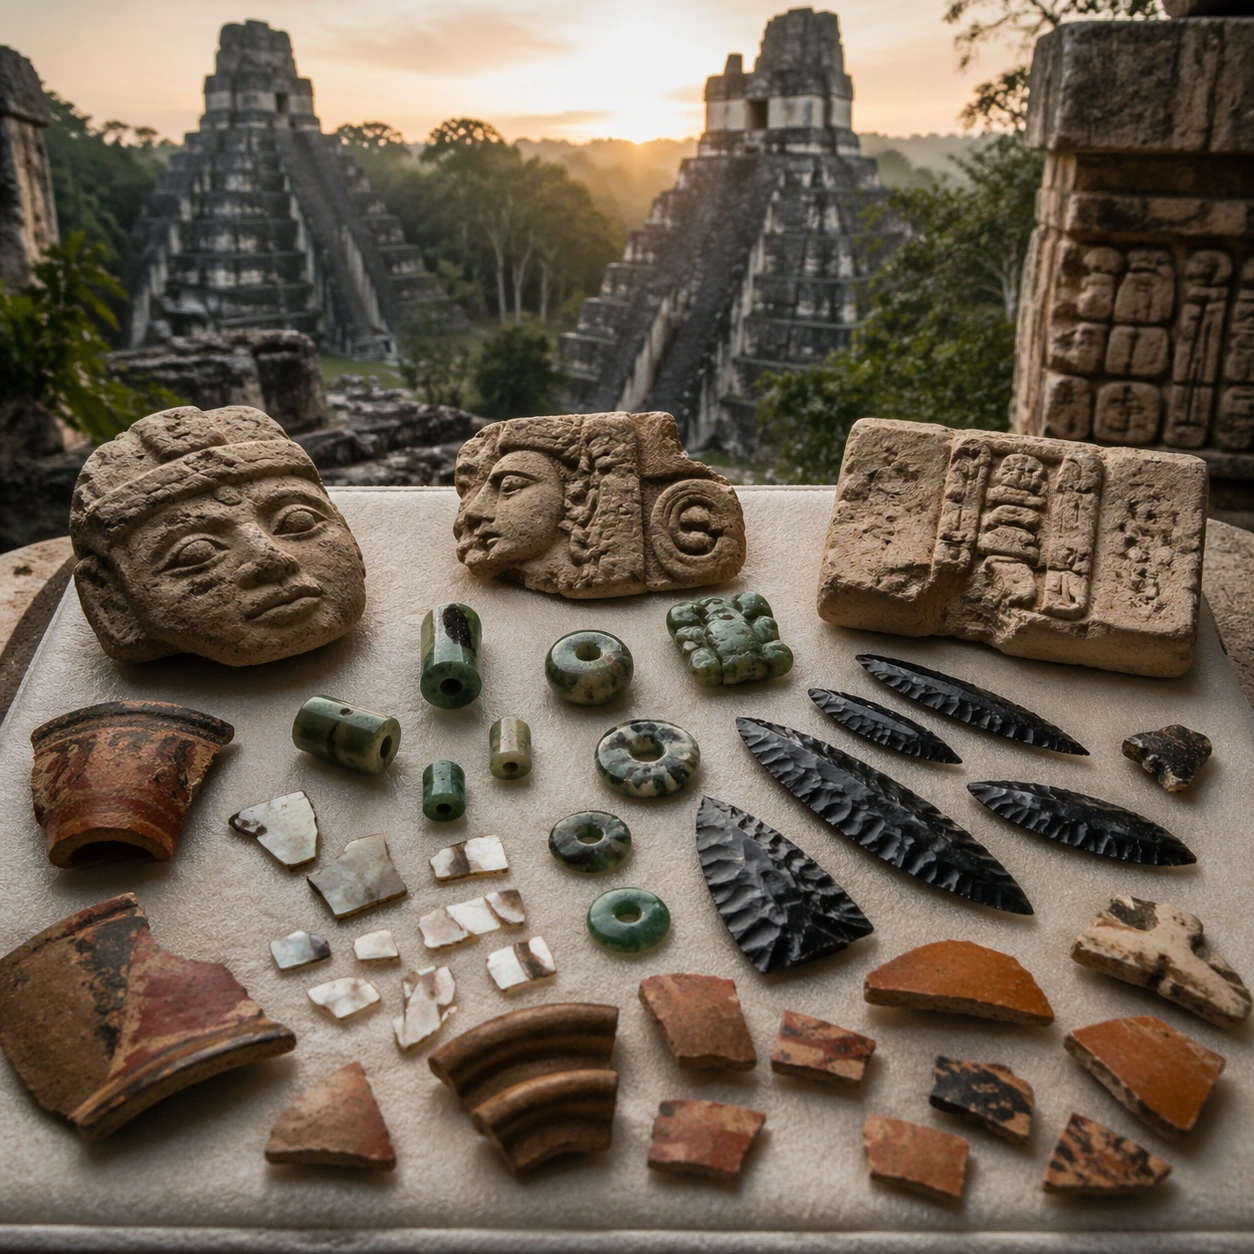
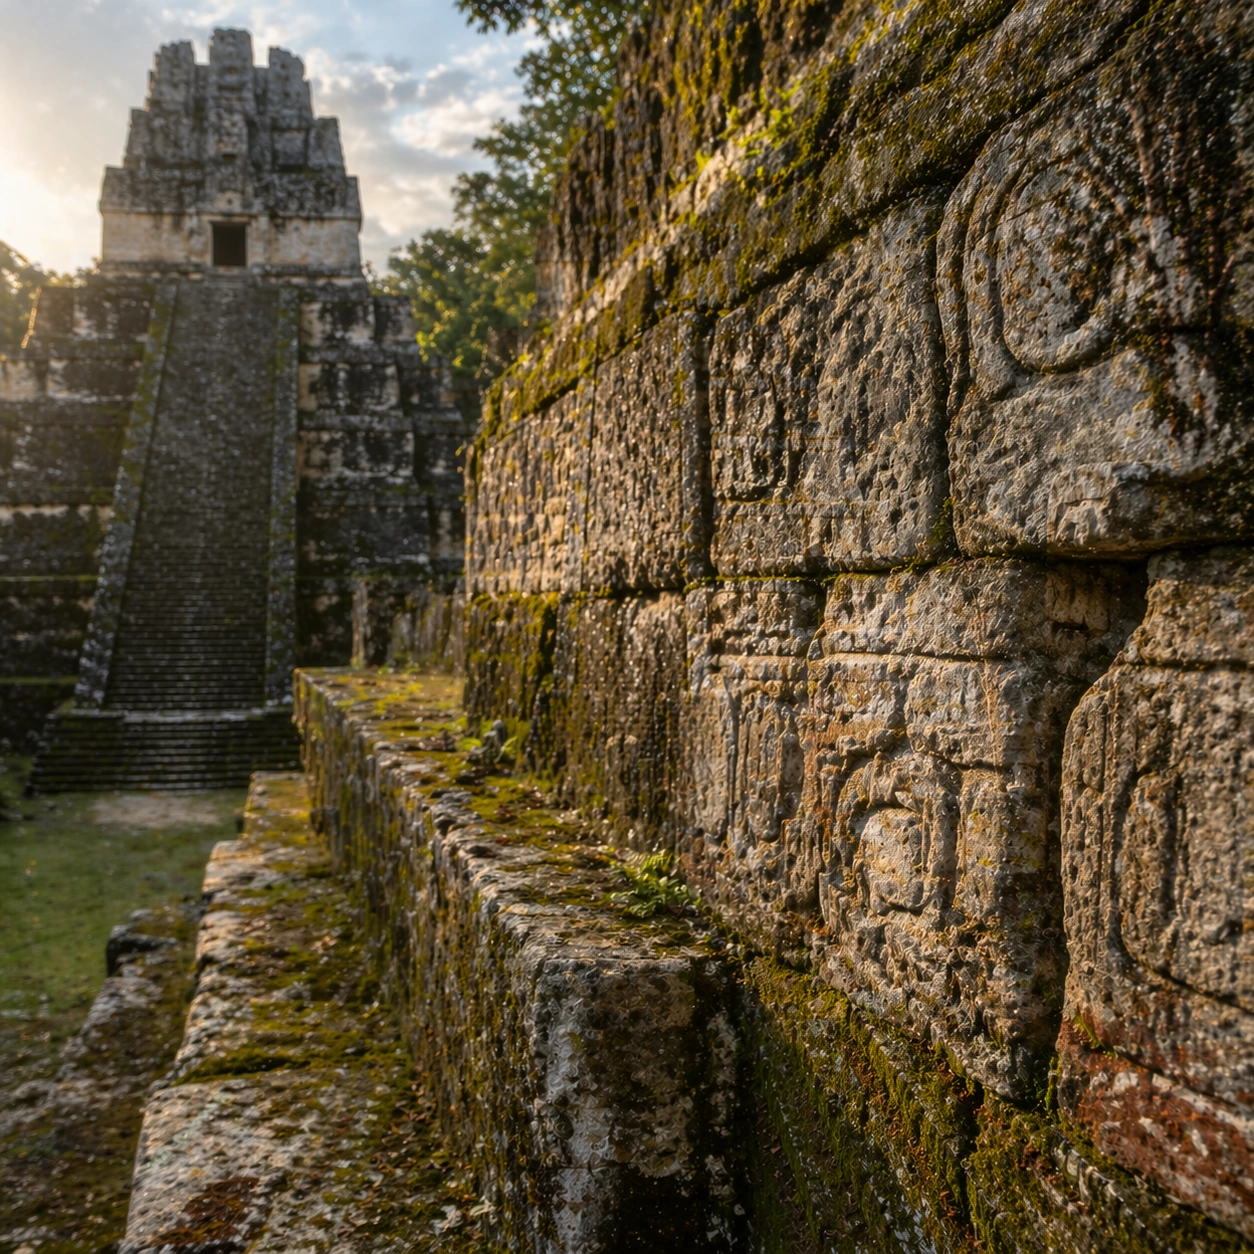
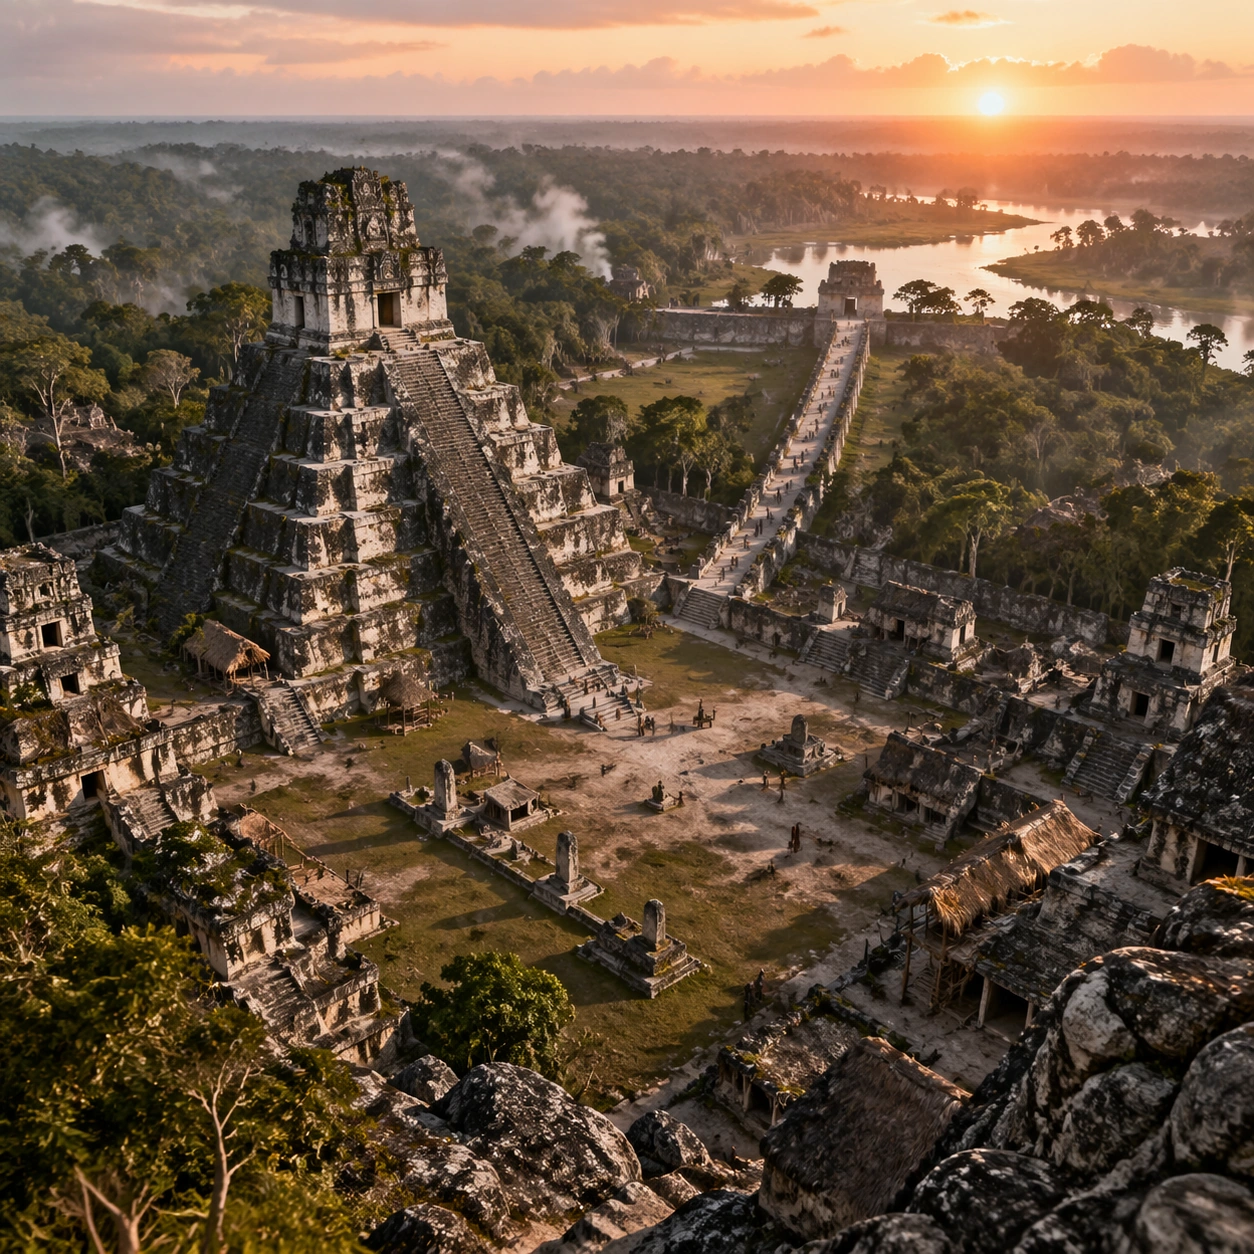
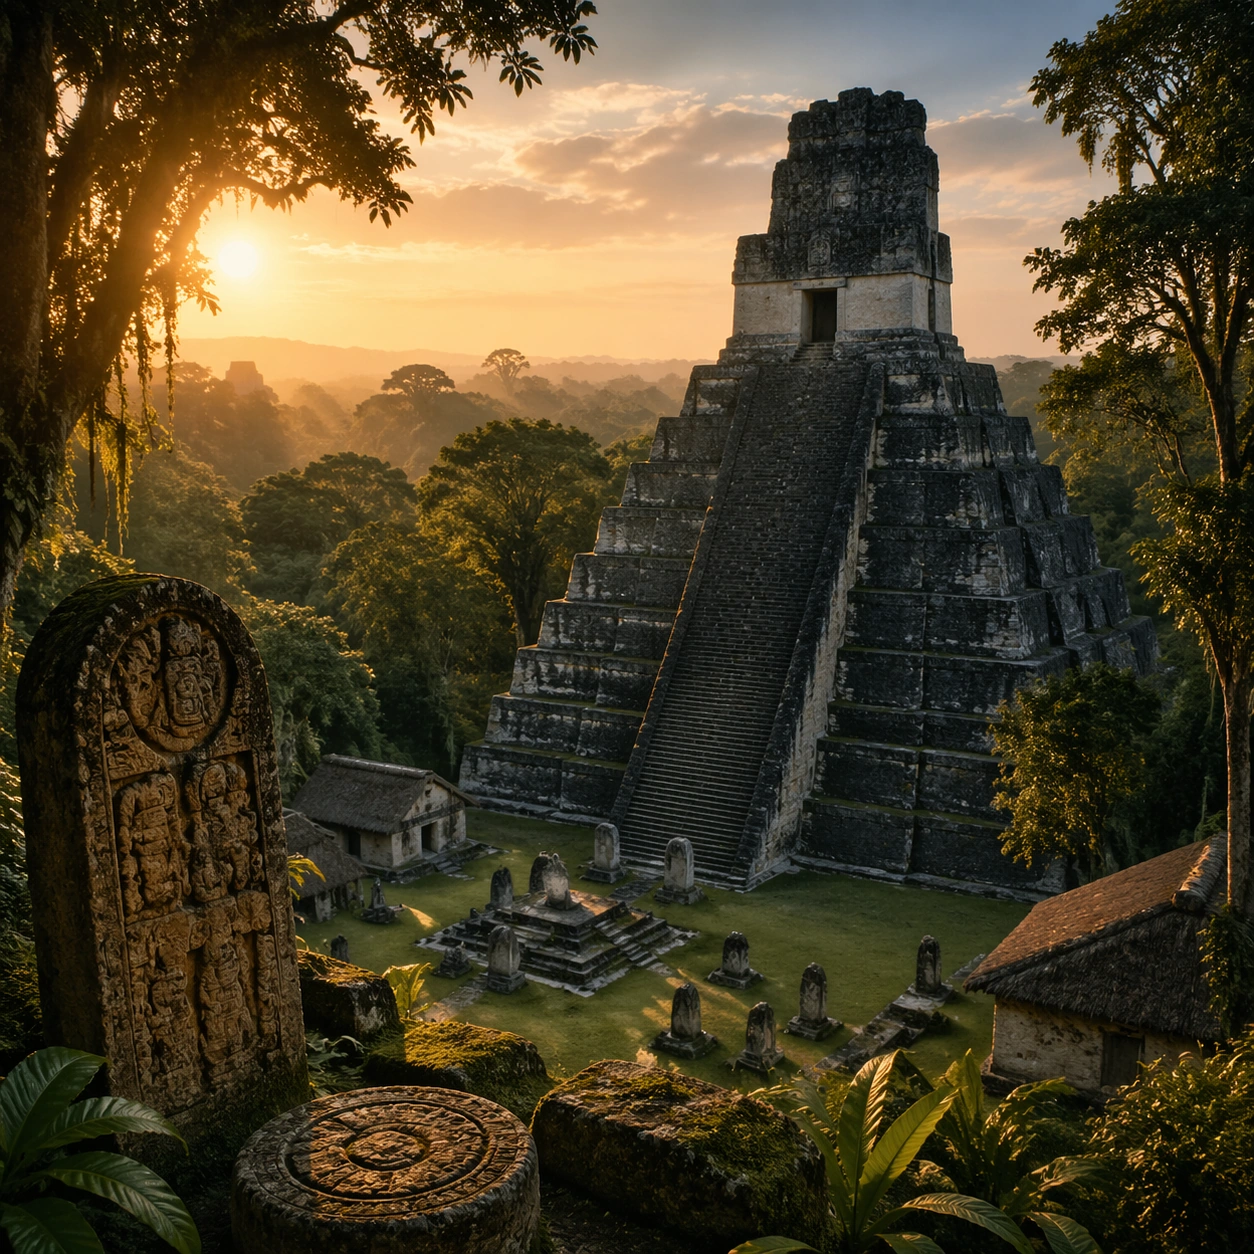
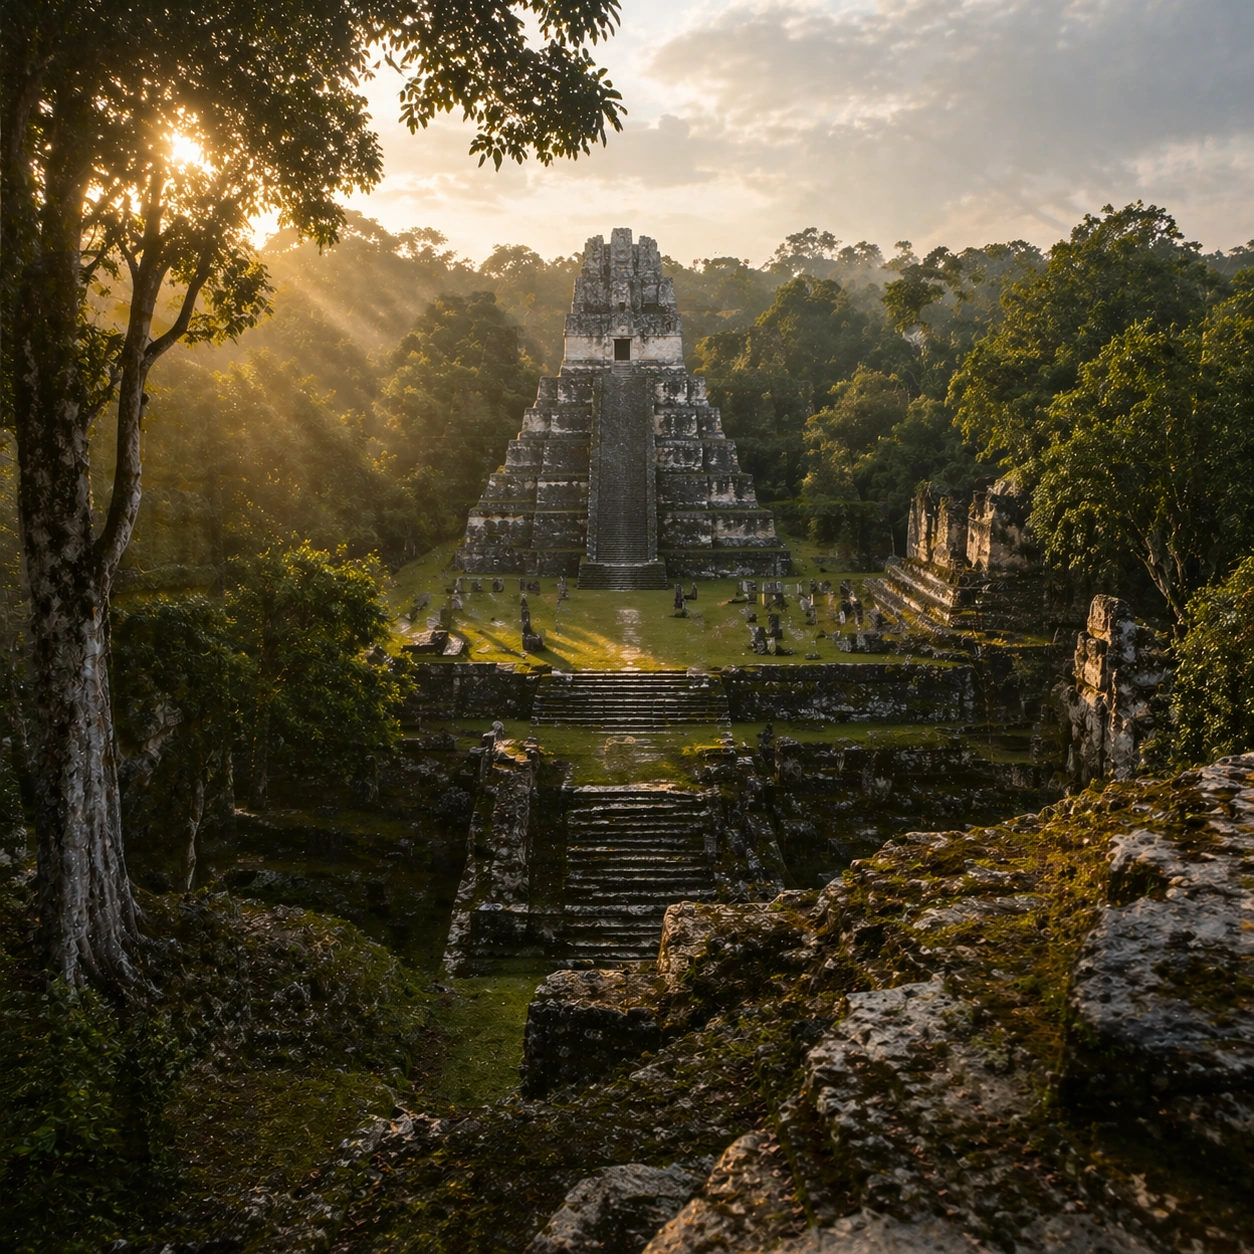
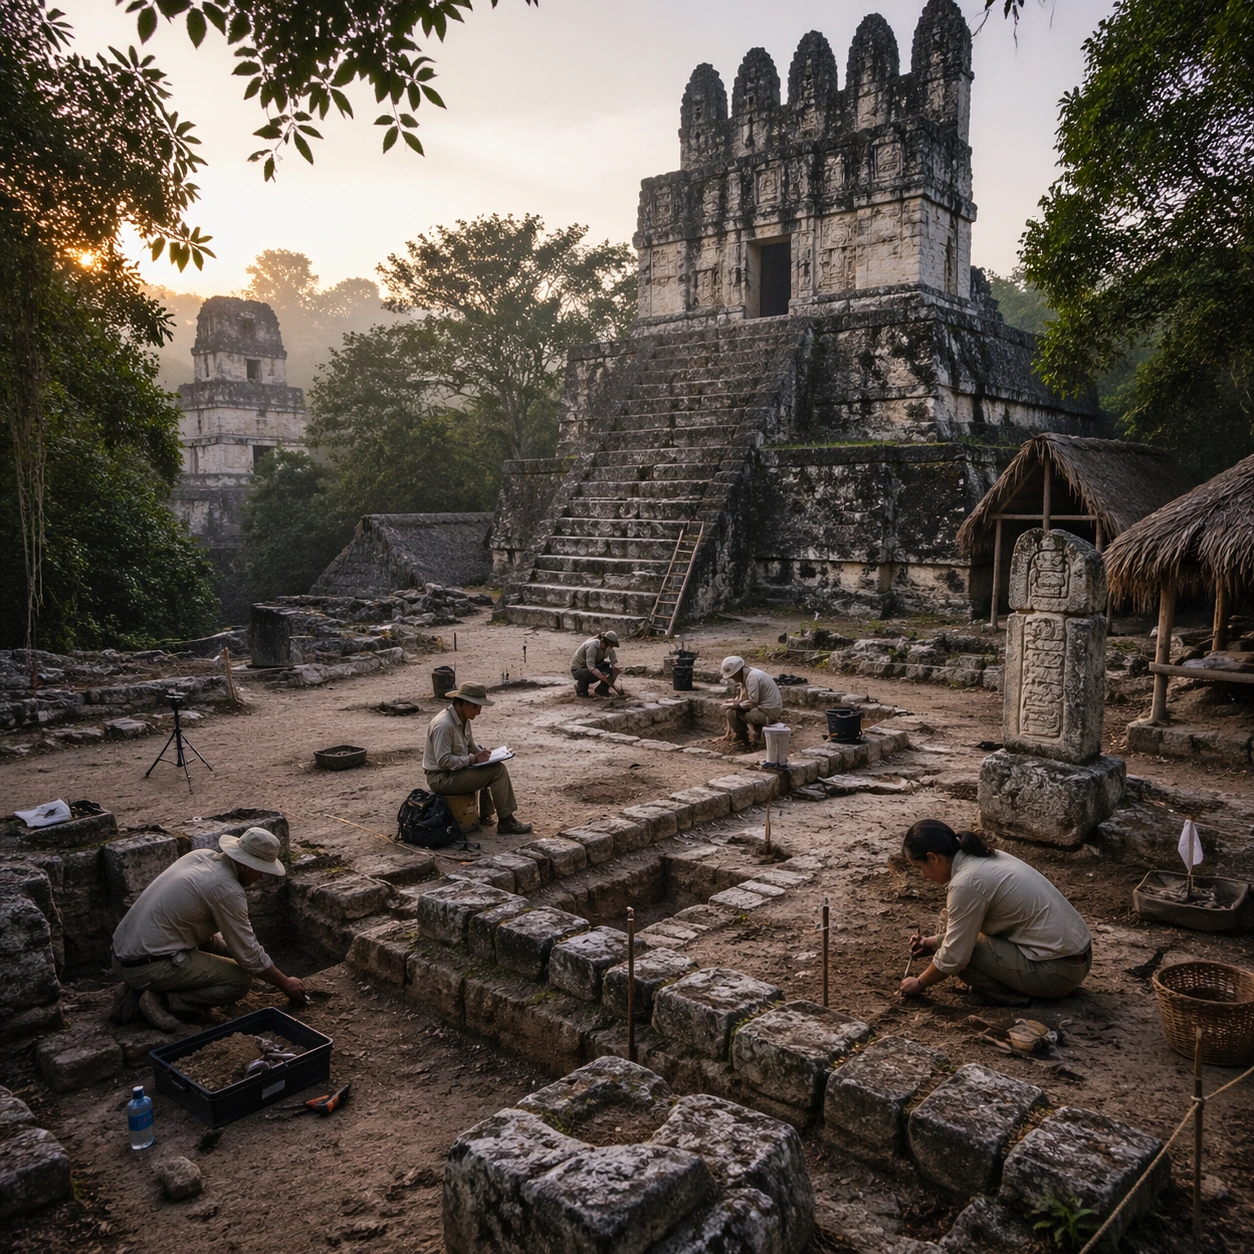
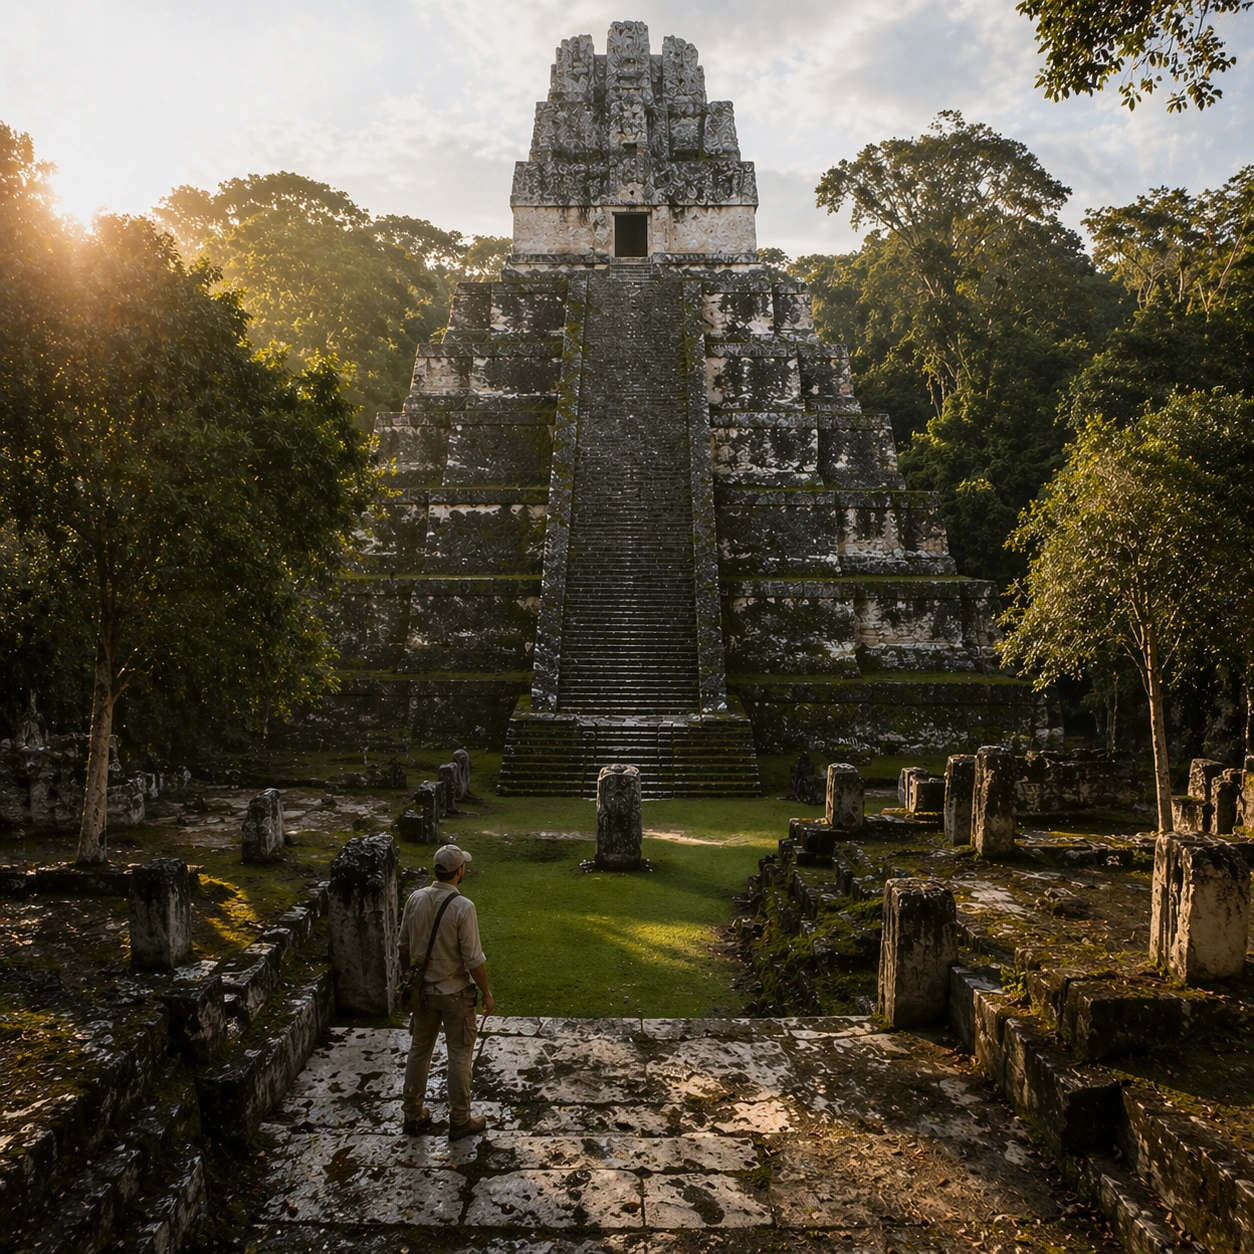
A square follow-up field image from the same site, slightly closer and lower than the reference anchor, with careful documentary framing and the same material palette. The camera should feel physically present inside the archaeological space, using natural light, soft depth separation, and one clear human figure to explain scale without turning the image into lifestyle photography.

Subject:
Show the same site identity established in the reference anchor, now with an archaeologist, conservator, or field researcher moving through the scene in practical neutral clothing. The person should be small relative to the monument and clearly secondary to the architecture, water, or painted wall system. Keep the main forms, structural rhythm, and civilizational markers unchanged.

Important details:
Preserve the exact site identity, base geometry, material behavior, and cultural signatures from the reference model. Only vary vantage, gesture, and scale cues. Keep the architecture unmistakably Maya rather than generic fantasy ruins, with steep stepped geometry, roof-comb silhouettes, believable glyph blocks, and dense tropical vegetation that respects the stone volumes instead of swallowing them completely. Human presence should clarify stair height, wall size, carving depth, or spatial compression while respecting conservation protocol and historical seriousness. Keep any tools understated and generic, with no readable labels. The image must still look like a rigorous archaeological record first and a dramatic scene second.

Use case:
Maya Temple Dawn Discovery series study 2/9.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, preserve exact site identity from the reference image, no modern vehicles, no sci-fi glow, no fantasy monsters, no glass skyscrapers, no fashion editorial styling, no crowd, no cinematic props.
使い方
- パラメータを含む元のプロンプト全体をコピーします。
- 被写体、文字、構図を自分の要件に置き換えます。
- 対応する外部ツールで使用し、利用条件と結果を確認します。
開始前の確認
- 参考画像の要否を確認してください。互換モデルの表示は、そのモデルでの生成実績を意味しません。
- 名前、数値、画像内の文字を確認します。モデルの版で結果は変わります。