원본 문서
GPT Image 2 · en
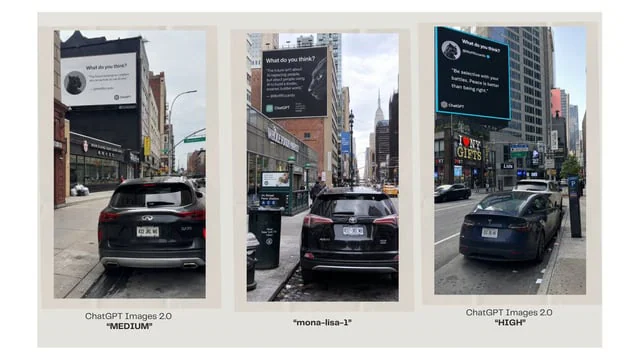
Goal: Create a clean comparison graphic showing three AI-generated urban billboard photos side by side, as if comparing image model outputs.

Canvas: Wide 16:9 presentation slide with a warm off-white background and generous margins. Place three tall vertical photo panels evenly spaced across the canvas, each framed by a pale beige mat/border. Under each panel, add a centered caption.

Layout: Exactly 3 vertical street-photo panels in one row. Panel 1 on the left, Panel 2 in the center, Panel 3 on the right. Each panel shows a realistic New York City street scene with parked cars in the foreground, tall buildings, sidewalks, traffic signs, and a large square billboard mounted high on a building. Use slightly different street angles and lighting in each panel, like three separate model outputs of the same concept.

Panel details: Left panel: a rear view of a black SUV parked on a city street, looking toward storefronts and buildings; a large white billboard above the street reads like a social-media quote card with a small circular animal avatar, the heading “What do you think?”, a short quote, and small ChatGPT branding. Center panel: a black SUV parked on a narrow Manhattan street with the Empire State Building visible in the distance; a large dark billboard with white text, a circular animal avatar, and ChatGPT branding. Right panel: a black sedan parked along a busier avenue with storefront signs such as “I ♥ NY GIFTS”; a large black billboard with a bright cyan border, white quote text, a circular animal avatar, and ChatGPT branding.

Caption text: Use exactly 3 captions beneath the panels. Left caption: “ChatGPT Images 2.0” on the first line and “MEDIUM” in bold quotation marks on the second line. Center caption: “mona-lisa-1” in bold quotation marks. Right caption: “ChatGPT Images 2.0” on the first line and “HIGH” in bold quotation marks on the second line.

Customizable text slots: The comparison labels should read {argument name="left model label" default="ChatGPT Images 2.0"}, {argument name="center model label" default="mona-lisa-1"}, and {argument name="right model label" default="ChatGPT Images 2.0"}. The left quality tag should be {argument name="left quality tag" default="MEDIUM"} and the right quality tag should be {argument name="right quality tag" default="HIGH"}.

Visual style: Photorealistic smartphone street photography inside each panel, but arranged as a polished social-media comparison slide. Keep the overall slide minimal, with no decorative graphics beyond the three framed images and their captions. The billboard text inside the photos may be small and partially imperfect, but it should clearly resemble AI quote-card advertising with ChatGPT logos.
사용 방법
- 매개변수를 포함한 전체 원본 프롬프트를 복사하세요.
- 주제, 문구, 구도를 자신의 요구에 맞게 바꾸세요.
- 호환되는 외부 도구에서 사용하고 이용 조건과 결과를 확인하세요.
시작 전 확인
- 참조 이미지가 필요한지 확인하세요. 호환 표시는 해당 모델로 이 예시를 생성했다는 뜻이 아닙니다.
- 이름, 수치, 이미지 속 문구를 확인하세요. 모델 버전에 따라 결과가 다를 수 있습니다.