原始文档
GPT Image 2 · en
Scene:
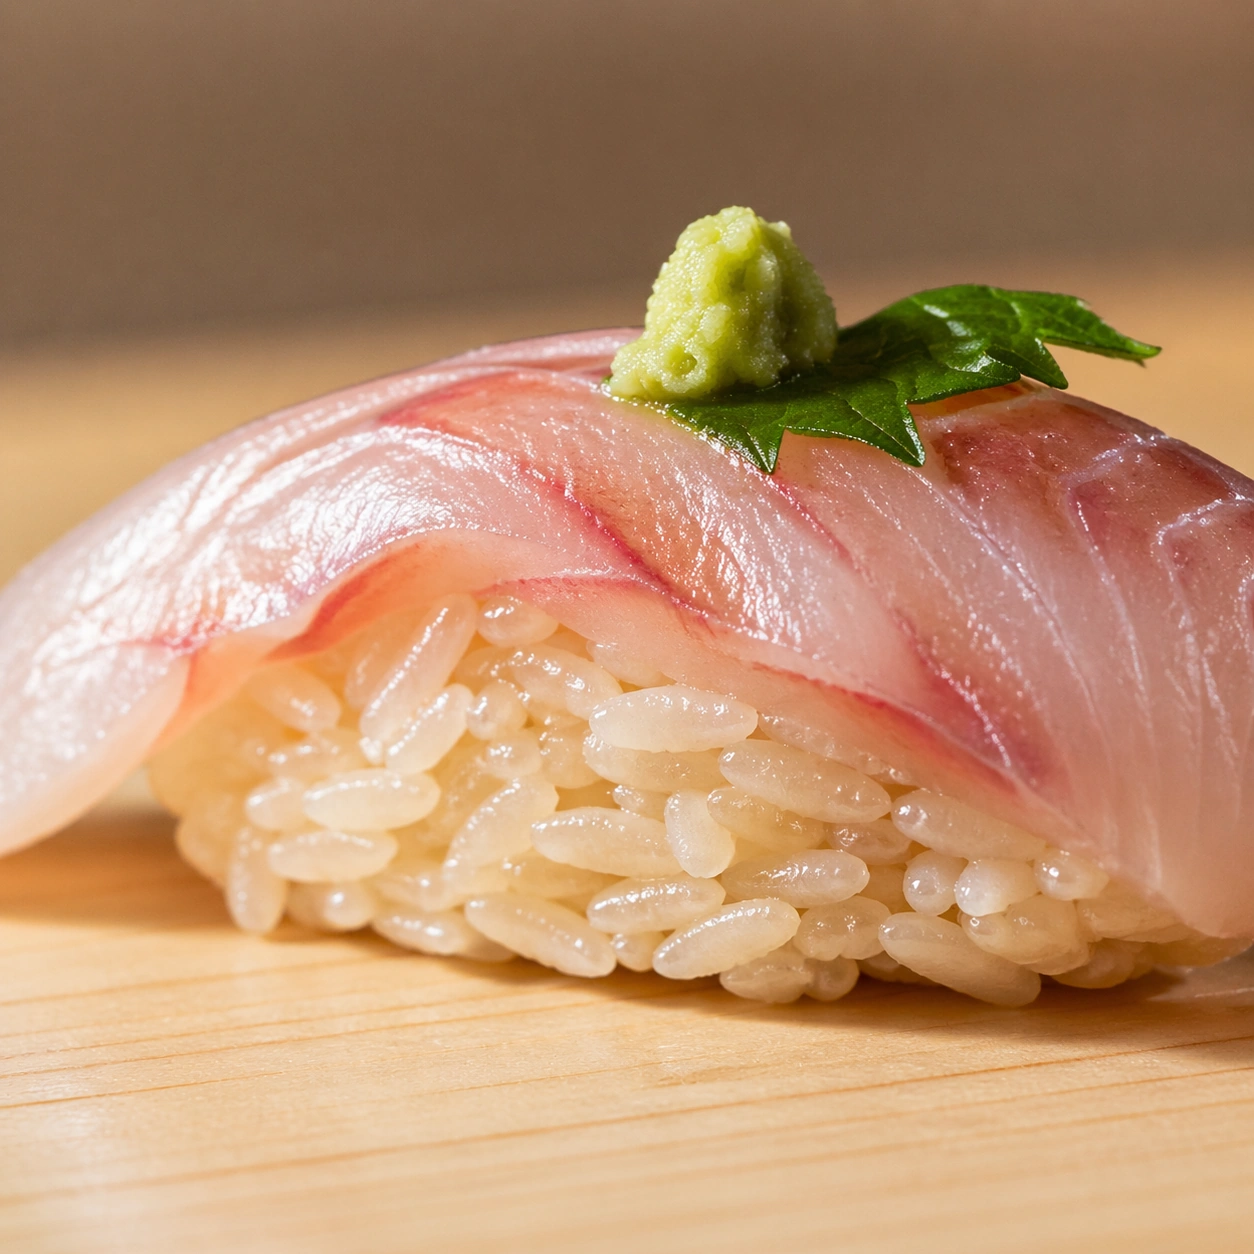
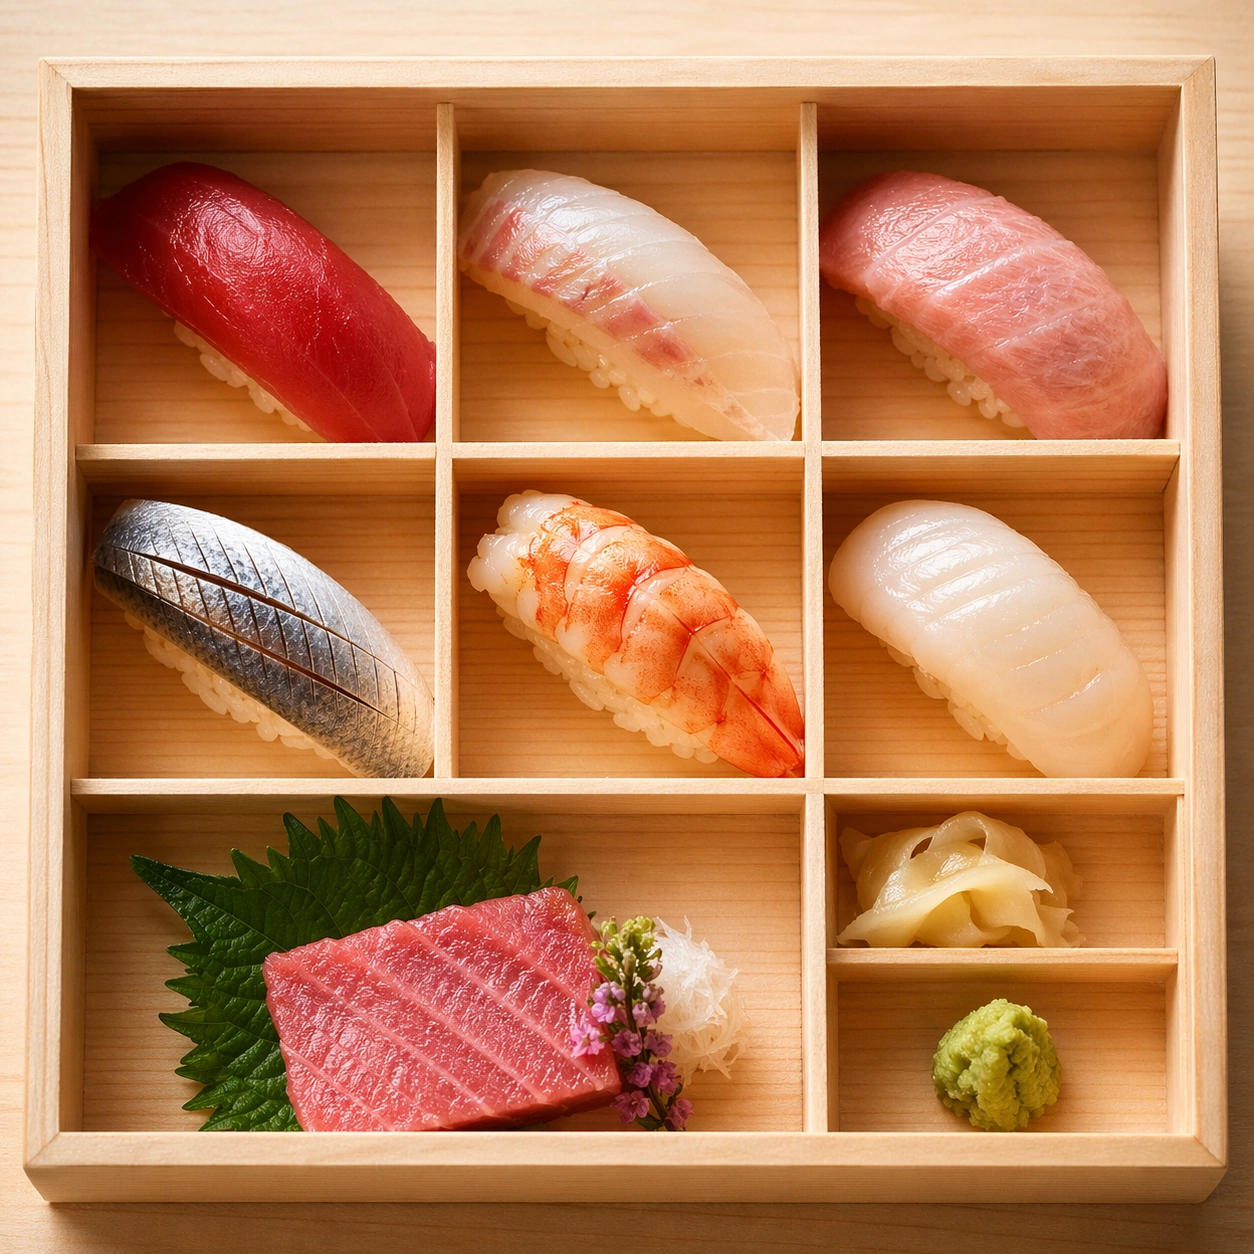
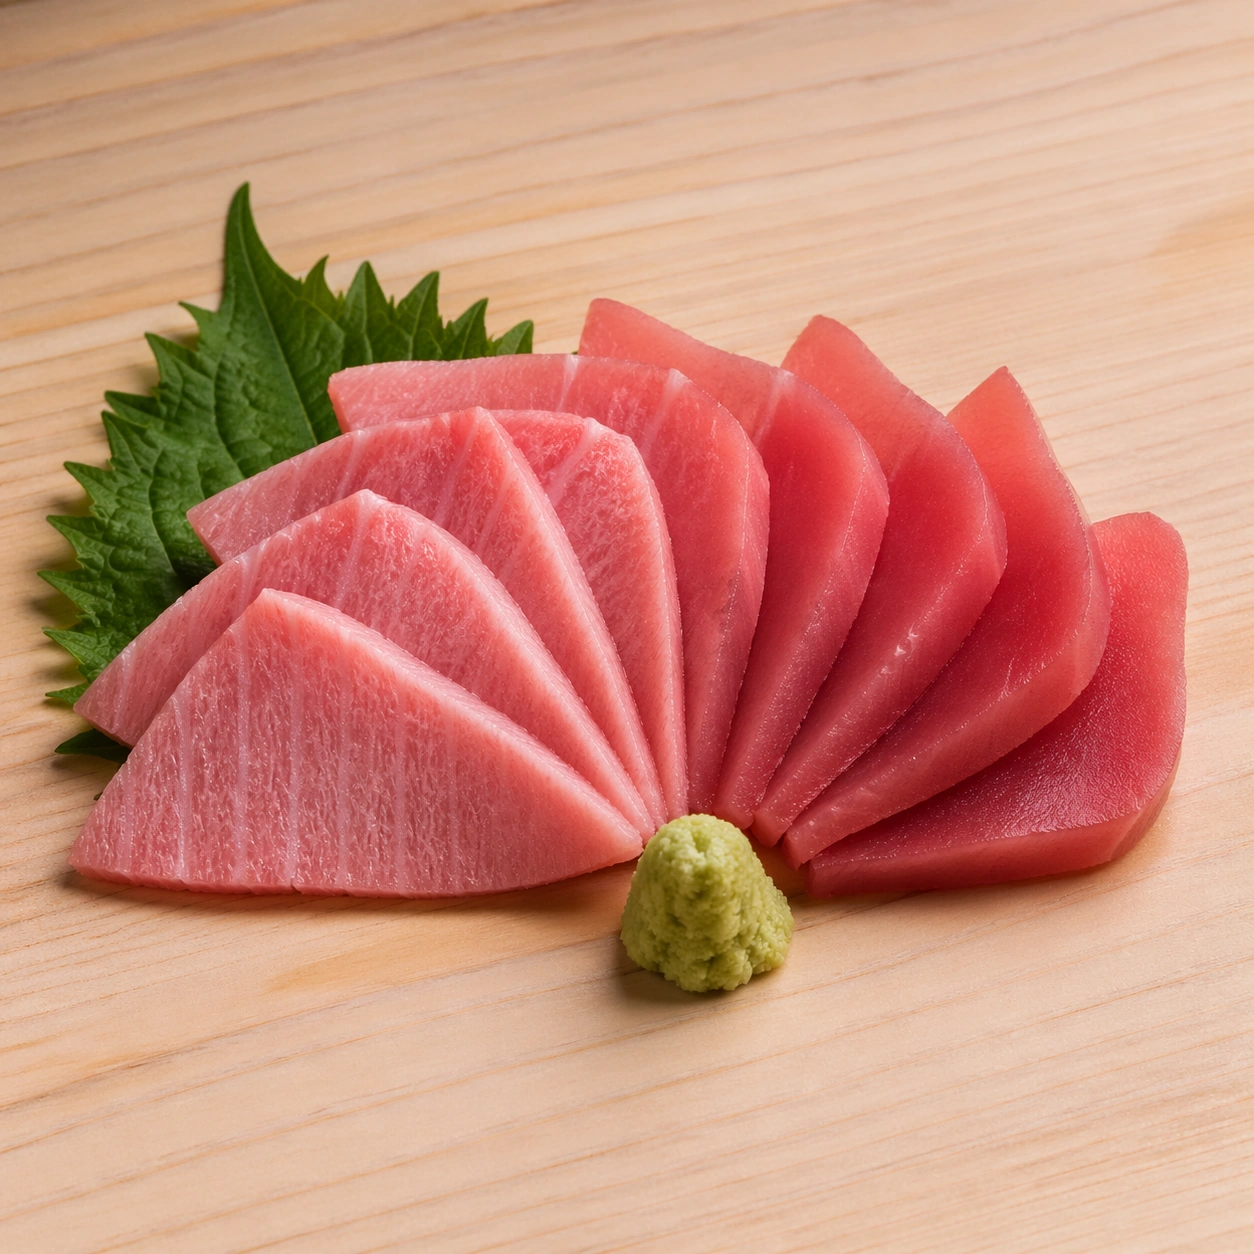
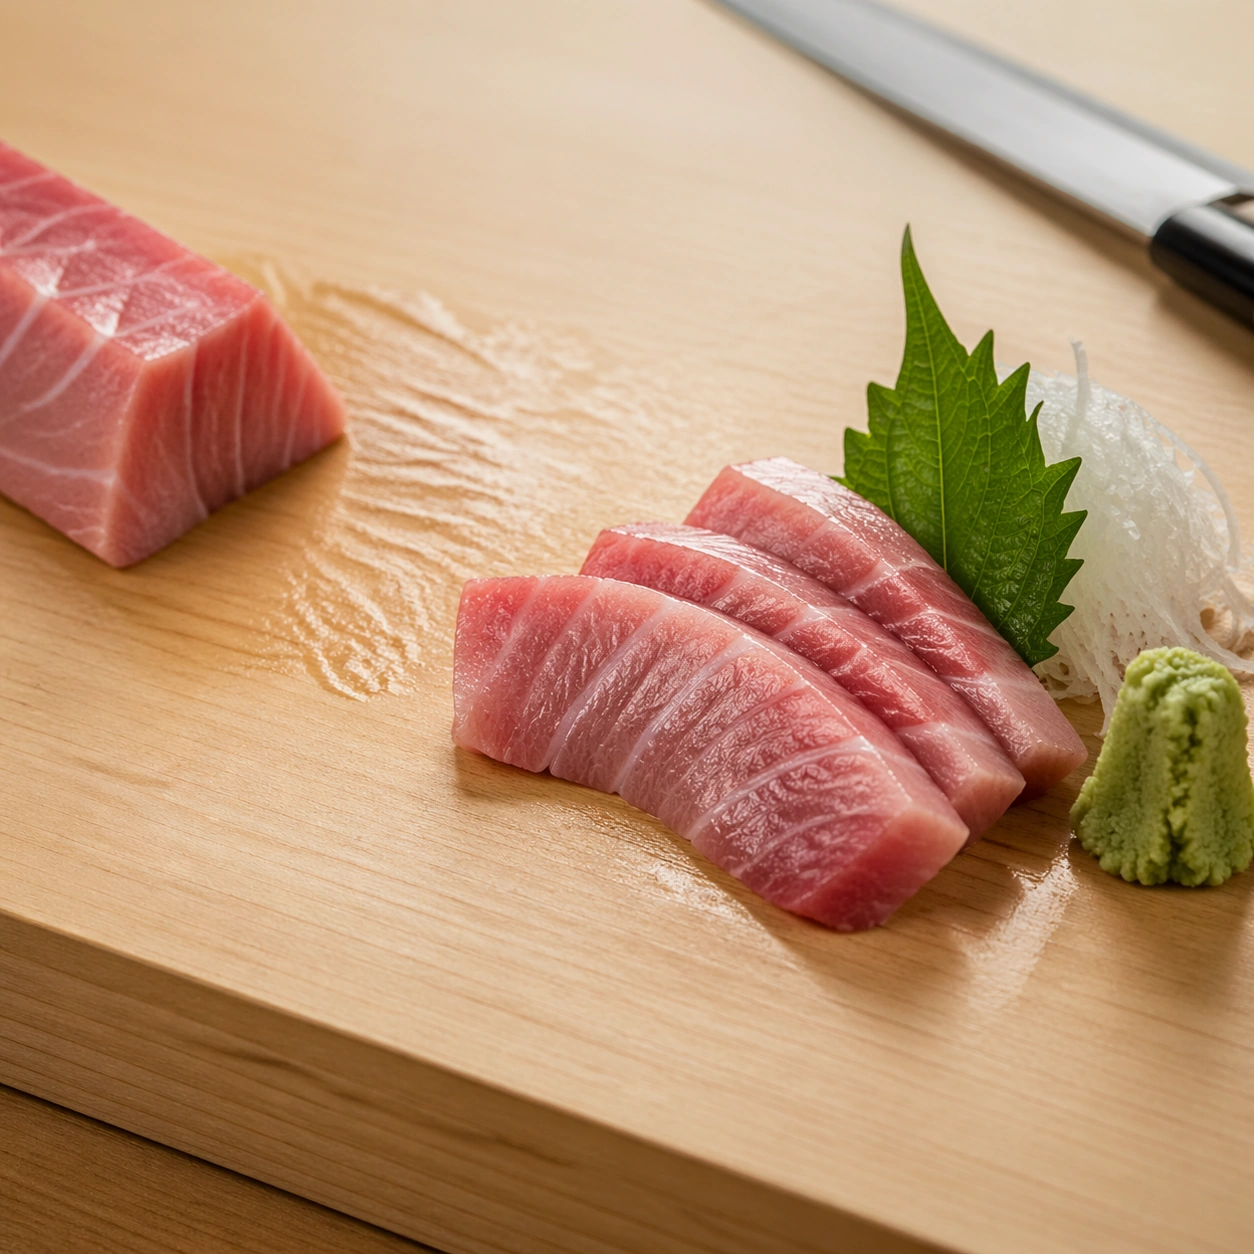
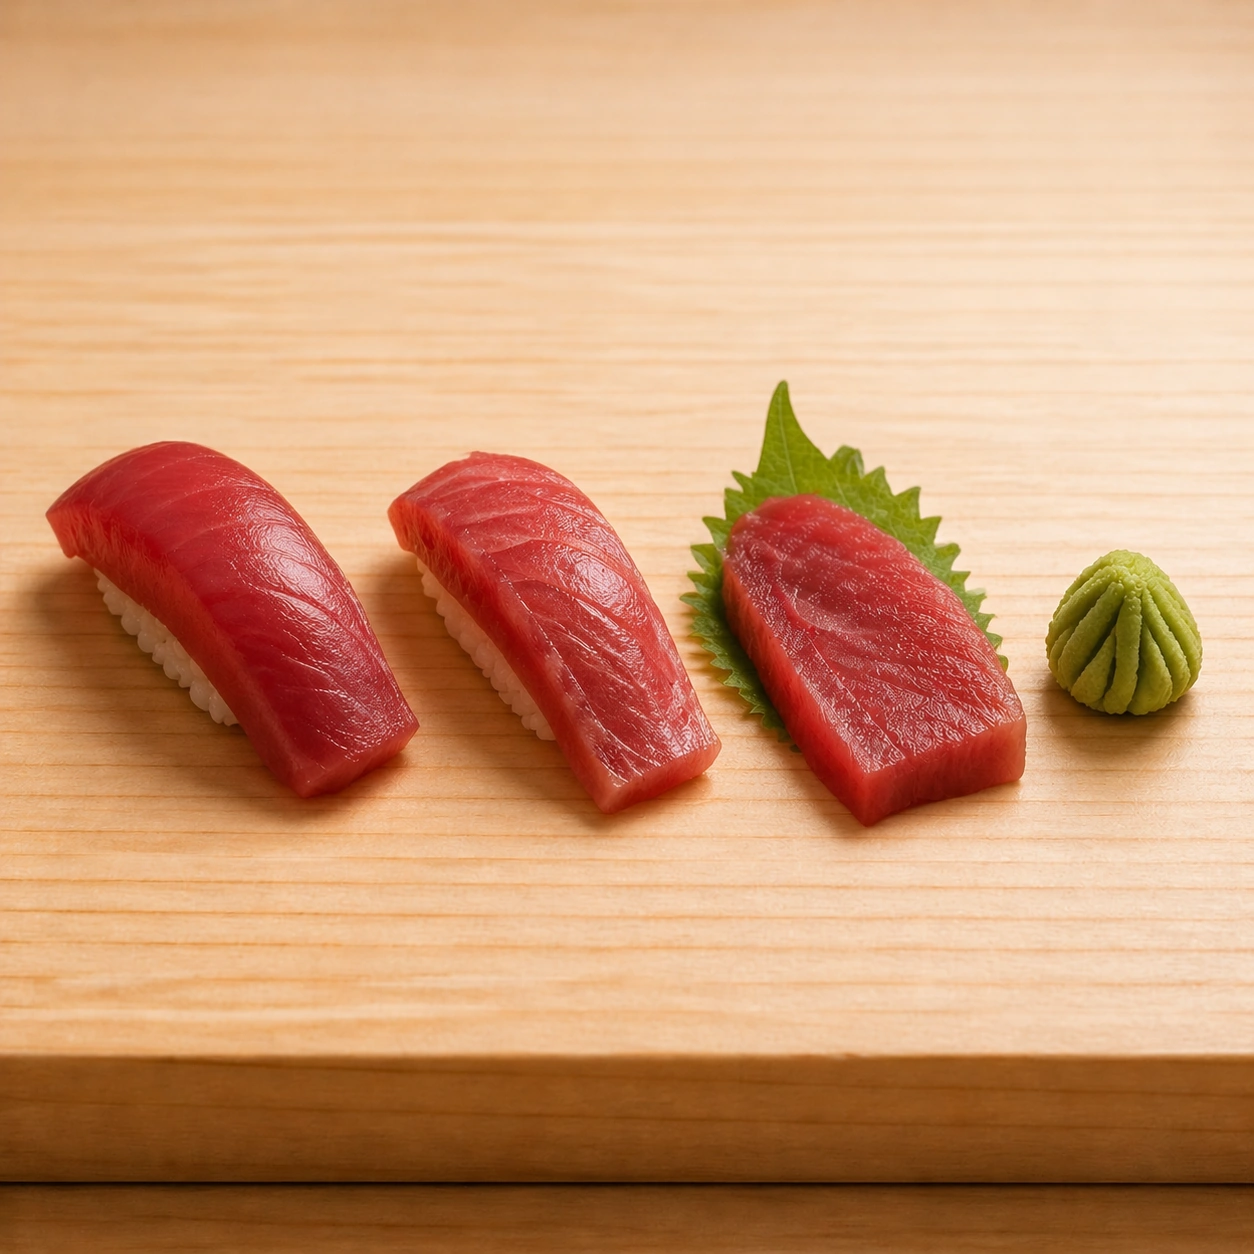
Create a square high-end sushi photograph on pale hinoki wood or a neutral omakase counter, lit with precise raking light that reveals grain in fish and separation in rice. The environment should feel silent, expensive, and almost clinical in its cleanliness. Space, alignment, and proportion matter as much as the ingredients themselves. Maintain the exact counter perspective, wood tone, spacing, and raking light from the reference image so the omakase sequence remains coherent. The atmosphere should stay quiet and nearly clinical.

Subject:
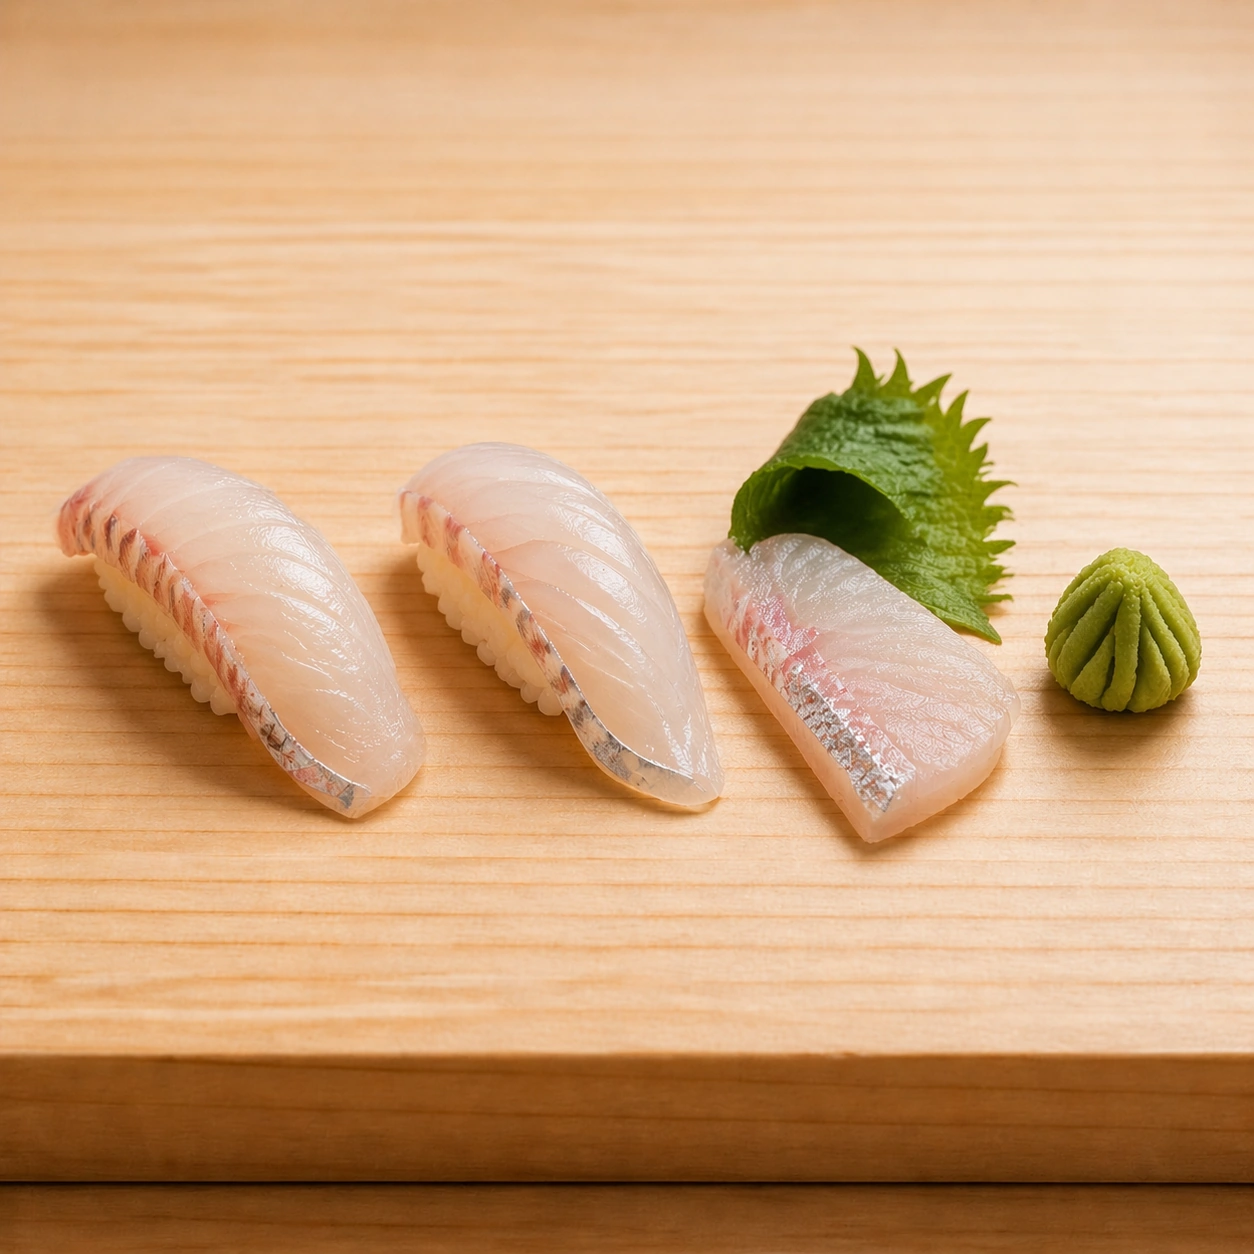
Present pale sea bream nigiri and sashimi with delicate translucency, subtle silver skin traces, and one curled shiso leaf as the only major accent. The fish slices should show knife discipline and soft internal striation, while the rice remains tight and countable. The composition should feel lighter and more ethereal than the tuna variation.

Important details:
Every ingredient should reward macro inspection: fish grain direction, cut angle, moisture, knife marks, rice-grain separation, wasabi texture, shiso curl, and the grain of the wood beneath all need to remain distinct. The result should communicate mastery through restraint and surgical care rather than abundance. Preserve exact counter geometry, spacing, and light logic from the reference model while emphasizing pale translucency, silver skin sheen, and delicate knife work. Rice grains must remain individually readable, never mashed into one mass.

Use case:
Sushi and sashimi precision series study 3/9, translating the anchor lineup into translucent white-fish precision.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no soy sauce pools, no decorative restaurant clutter, no readable menu cards, no plastic sushi display look, no overloaded garnish, no citrus slices everywhere, no plated salad garnish, no decorative ceramic bowls.
使用方法
- 复制完整原始提示词,并保留其中的参数。
- 按需求替换主体、文字和构图要求。
- 在兼容的外部工具中使用,核对当前使用条件并检查结果。
开始前需了解
- 先确认是否需要参考图。标注兼容模型,不代表该示例由这个模型生成。
- 核对名称、数字与画面文字;不同模型版本的结果可能不同。