原始文档
GPT Image 2 · en
Scene:
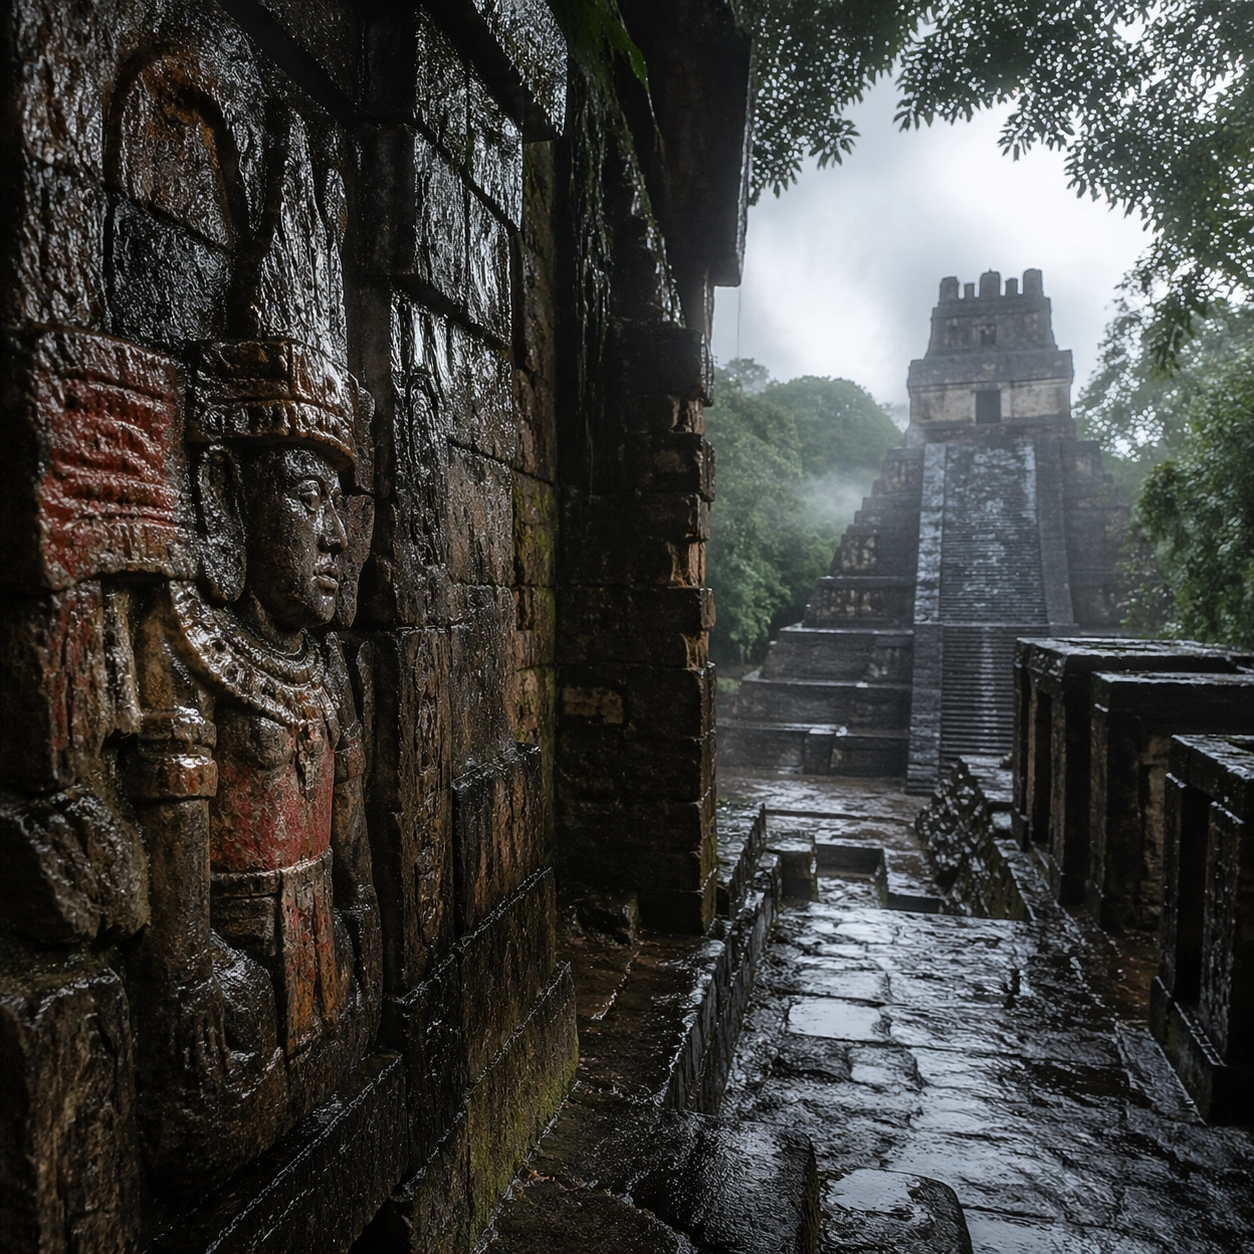
A square mood variation from the same civilization theme, built around rain-cooled cloudbreak light that leaves the stone wet, darker, and more reflective while keeping the site recognizable. The image should stay grounded in field realism while testing how different illumination changes material reading, atmosphere, and emotional register. Keep the frame self-contained and coherent, as if photographed during a second visit under altered conditions.

Subject:
Show a culturally accurate site or interior connected to the same world as the main topic, but not as a direct dependency on the series reference. The focus should be on how light transforms relief, color, moisture, water, dust, or vegetation while preserving archaeological credibility. Architectural forms, objects, and setting must still belong to the same civilization with no cross-cultural contamination.

Important details:
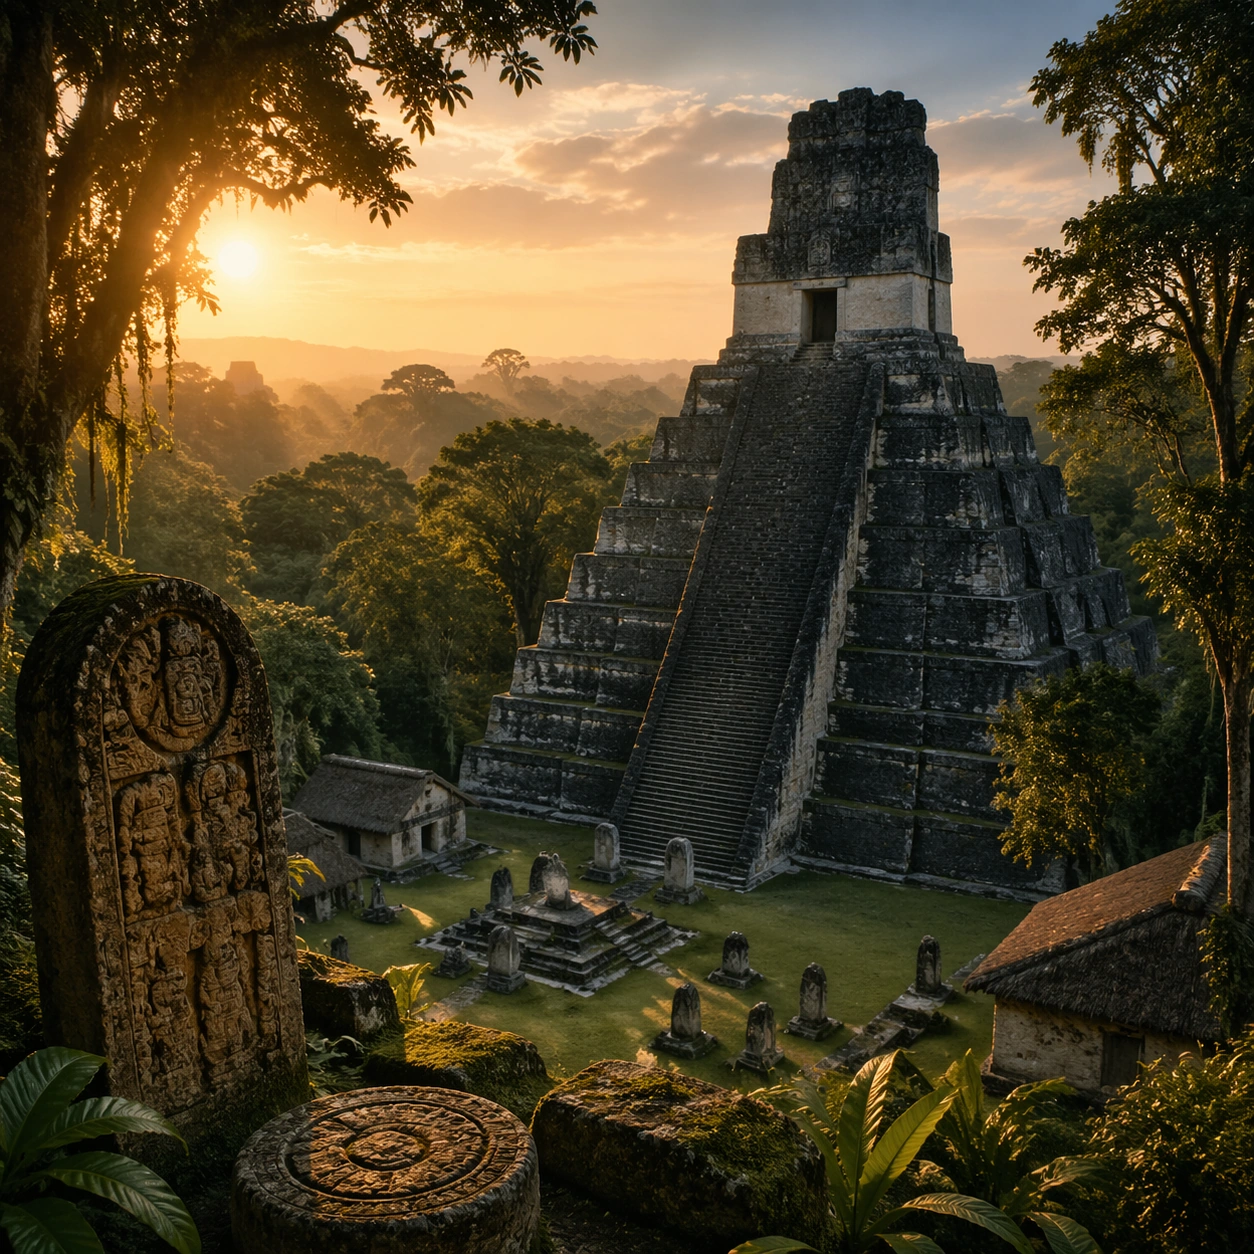
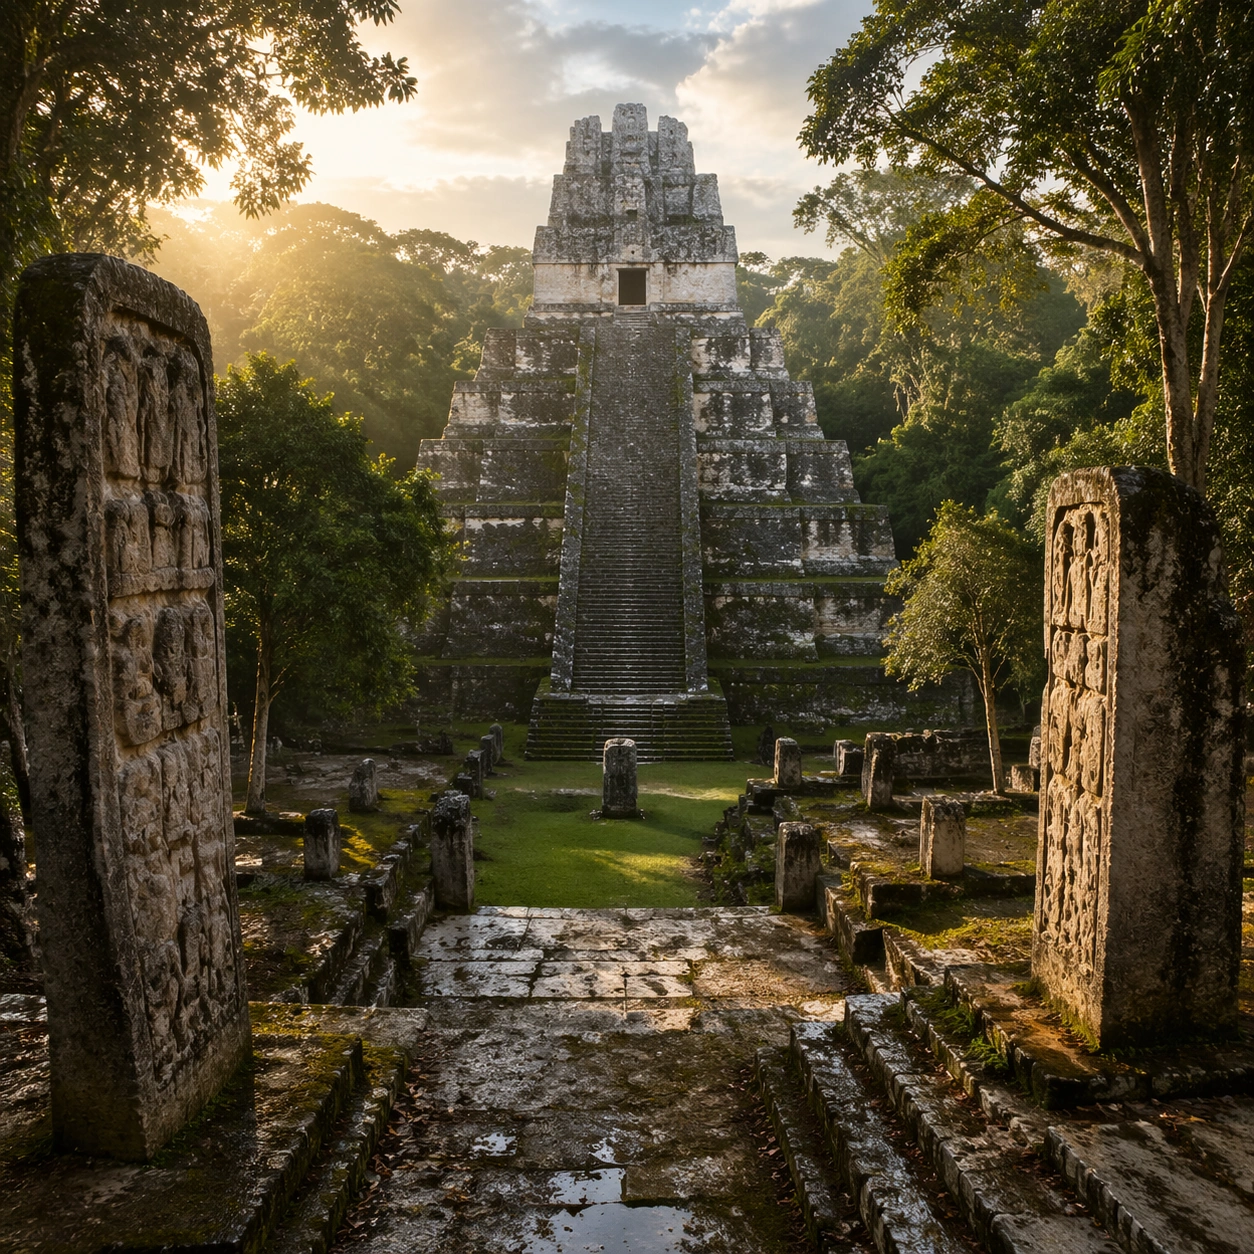
Keep the architecture unmistakably Maya rather than generic fantasy ruins, with steep stepped geometry, roof-comb silhouettes, believable glyph blocks, and dense tropical vegetation that respects the stone volumes instead of swallowing them completely. Use the shift in light to reveal different evidence than the other studies: pigment glow, root sheen, caustics, wet stone, canyon shadow, marine haze, terrace depth, or quarry moisture. Keep the result serious and observational rather than romanticized. Non-readable motifs are acceptable, but there should be no signs, captions, or modern display devices. The image should feel like a rigorous visual experiment in historical atmosphere.

Use case:
Maya Temple Dawn Discovery single study 7/9.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no modern vehicles, no sci-fi glow, no fantasy monsters, no glass skyscrapers, no theatrical color filters, no supernatural effects, no montage composition, no glossy concept-art exaggeration.
使用方法
- 复制完整原始提示词,并保留其中的参数。
- 按需求替换主体、文字和构图要求。
- 在兼容的外部工具中使用,核对当前使用条件并检查结果。
开始前需了解
- 先确认是否需要参考图。标注兼容模型,不代表该示例由这个模型生成。
- 核对名称、数字与画面文字;不同模型版本的结果可能不同。