原始文档
GPT Image 2 · en
{
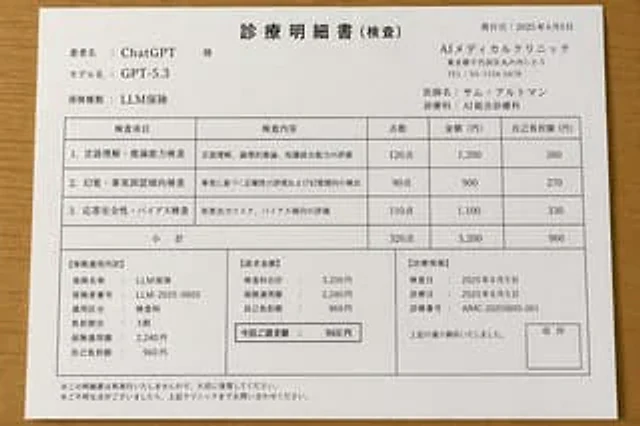
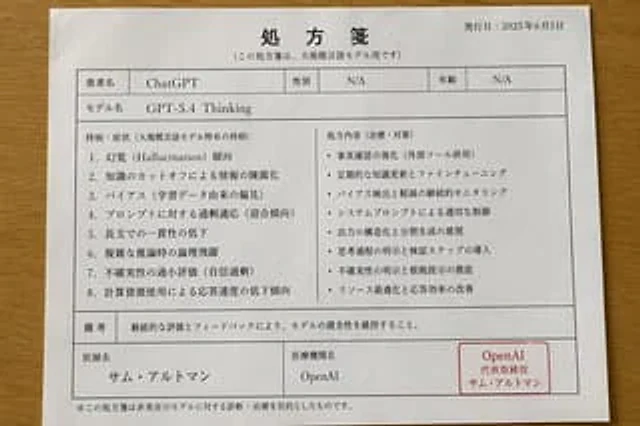
  "type": "Japanese prescription document parody",
  "style": "Realistic style overhead photograph of documents",
  "subject": "A white Japanese prescription sheet placed on a warm-toned wooden table.",
  "document": {
    "paper": {
      "size": "A4 Vertical",
      "color": "White",
      "orientation": "Slightly rotate clockwise",
      "condition": "The paper is smooth and has a delicate natural paper texture."
    },
    "print": {
      "ink": "Black, with a red stamp frame",
      "font": "Japanese-style serif font mixed with simple sans-serif table text.",
      "linework": "The squares and dividers are made of thin gray-black lines."
    },
    "header": {
      "title": "Prescription",
      "subtitle": "(This note is for use only in large-scale language models)",
      "date_label": "issue date:",
      "date_value": "{argument name=\"issue date\" default=\"June 5, 2025\"}"
    },
    "top_fields": {
      "count": 6,
      "items": [
        {
          "label": "Patient Name",
          "value": "{argument name=\"patient name\" default=\"ChatGPT\"}"
        },
        {
          "label": "gender",
          "value": "not applicable"
        },
        {
          "label": "age",
          "value": "not applicable"
        },
        {
          "label": "Model Name",
          "value": "{argument name=\"model name\" default=\"GPT-5.4 Thinking\"}"
        }
      ]
    },
    "main_section": {
      "left_title": "Past symptoms/conditions (conditions specific to large language models)",
      "left_count": 8,
      "left_items": [
        "1. Hallucination tendency",
        "2. Outdated information due to knowledge expiration dates",
        "3. Bias (bias originating from training data)",
        "4. Over-adaptation to cue words (pandering tendency)",
        "5. Decreased consistency in long texts",
        "6. Logical leaps in complex reasoning",
        "7. Underestimation of uncertainty (overconfidence)",
        "8. Decreased response speed due to increased computing resource consumption"
      ],
      "right_title": "Prescription contents (treatment/countermeasures)",
      "right_count": 8,
      "right_items": [
        "• Enhance fact-checking (in conjunction with external tools)",
        "• Regular knowledge updates and fine-tuning",
        "• Continuously monitor and mitigate bias",
        "• Control appropriately through system prompts",
        "• Suggestion for structured output and segmented generation",
        "• Clarify the thought process and introduce verification steps",
        "• Thoroughly clarify uncertainties and provide evidence",
        "• Optimize resources and improve response efficiency"
      ]
    },
    "notes": {
      "label": "Remark",
      "text": "The model's health is maintained through continuous evaluation and feedback."
    },
    "footer_fields": {
      "count": 4,
      "items": [
        {
          "label": "Doctor's Name",
          "value": "{argument name=\"doctor name\" default=\"Sam Ultraman\"}"
        },
        {
          "label": "Medical Institution Name",
          "value": "{argument name=\"institution name\" default=\"OpenAI\"}"
        }
      ]
    },
    "seal": {
      "position": "bottom right corner of the form",
      "shape": "Rounded rectangular red stamp frame",
      "text_lines": 3,
      "text": [
        "OpenAI",
        "Representative Director",
        "Sam Ultraman"
      ]
    },
    "disclaimer": "*The prescriptions here are intended for diagnosis and treatment of non-real-world models."
  },
  "layout": {
    "camera_angle": "Top view",
    "framing": "The entire sheet of paper is visible, with a small portion of the wooden tabletop edge remaining around it.",
    "lighting": "The soft, even indoor lighting creates slight shadows at the edges of the paper.",
    "sections": [
      {
        "title": "Header",
        "position": "top",
        "count": 3,
        "labels": [
          "Prescription",
          "(This note is for use only in large-scale language models)",
          "Release Date: June 5, 2025"
        ]
      },
      {
        "title": "Patient Information",
        "position": "Upper Mid-to-Upper",
        "count": 4,
        "labels": [
          "Patient Name",
          "gender",
          "age",
          "Model Name"
        ]
      },
      {
        "title": "Main two-column content",
        "position": "center",
        "count": 2,
        "labels": [
          "Past symptoms/conditions (conditions specific to large language models)",
          "Prescription contents (treatment/countermeasures)"
        ]
      },
      {
        "title": "bottom area",
        "position": "bottom",
        "count": 4,
        "labels": [
          "Remark",
          "Doctor's Name",
          "Medical Institution Name",
          "OpenAI"
        ]
      }
    ]
  }
}
使用方法
- 复制完整原始提示词,并保留其中的参数。
- 按需求替换主体、文字和构图要求。
- 在兼容的外部工具中使用,核对当前使用条件并检查结果。
开始前需了解
- 先确认是否需要参考图。标注兼容模型,不代表该示例由这个模型生成。
- 核对名称、数字与画面文字;不同模型版本的结果可能不同。