原始文档
GPT Image 2 · en
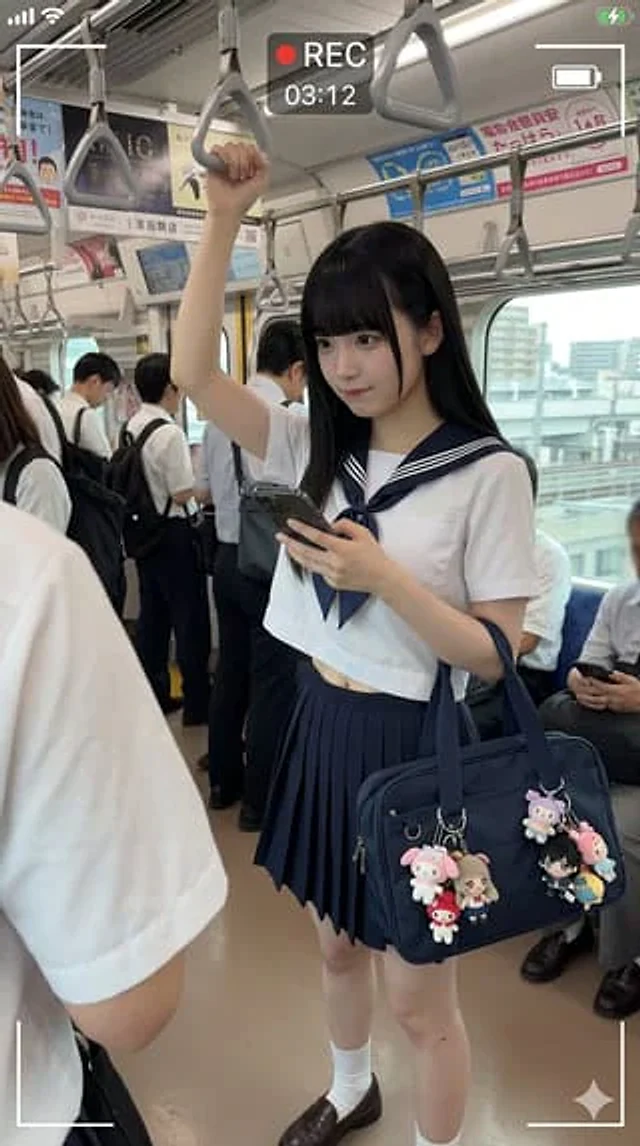
Create a photorealistic vertical smartphone candid photo inside a busy Japanese commuter train, shot from standing passenger height with a wide-angle phone lens. The main subject is {argument name="character description" default="a Japanese high school girl with long straight black hair"} standing in the aisle, wearing a classic navy-and-white sailor school uniform: short-sleeve white cropped sailor blouse with navy collar and double white stripes, navy neckerchief, navy pleated skirt, white crew socks, and brown loafers. Her face is intentionally hidden by a centered soft-edged square pixel blur/mosaic censor block. She raises her left arm to hold one gray triangular overhead train strap and looks downward while holding a dark smartphone in her right hand. On her shoulder is {argument name="bag description" default="a navy rectangular school shoulder bag"} decorated with exactly 5 visible dangling character charms: a pink bunny plush, a small red mushroom-like mascot, a blonde anime girl doll, a black-haired anime boy doll, and a pink-and-blue pastel plush on the far right. Surround her with other commuters in white shirts and school uniforms, some standing and some seated, with their faces blurred; include train windows showing an urban city view outside, metal poles, fluorescent ceiling lights, Japanese ad posters above the windows, and many gray triangular hanging straps receding into the background. Add a realistic phone video recording overlay: white corner frame brackets, a red dot and “REC” at the top center, timer text {argument name="recording time" default="03:12"}, small phone status icons at the top corners, and a small sparkle icon near the bottom right. Lighting should be natural daylight mixed with train interior fluorescent light, highly realistic, slightly compressed social-media photo quality, candid documentary mood, no glamour posing, no watermark.使用方法
- 复制完整原始提示词,并保留其中的参数。
- 按需求替换主体、文字和构图要求。
- 在兼容的外部工具中使用,核对当前使用条件并检查结果。
开始前需了解
- 先确认是否需要参考图。标注兼容模型,不代表该示例由这个模型生成。
- 核对名称、数字与画面文字;不同模型版本的结果可能不同。