原文
GPT Image 2 · en
Scene:
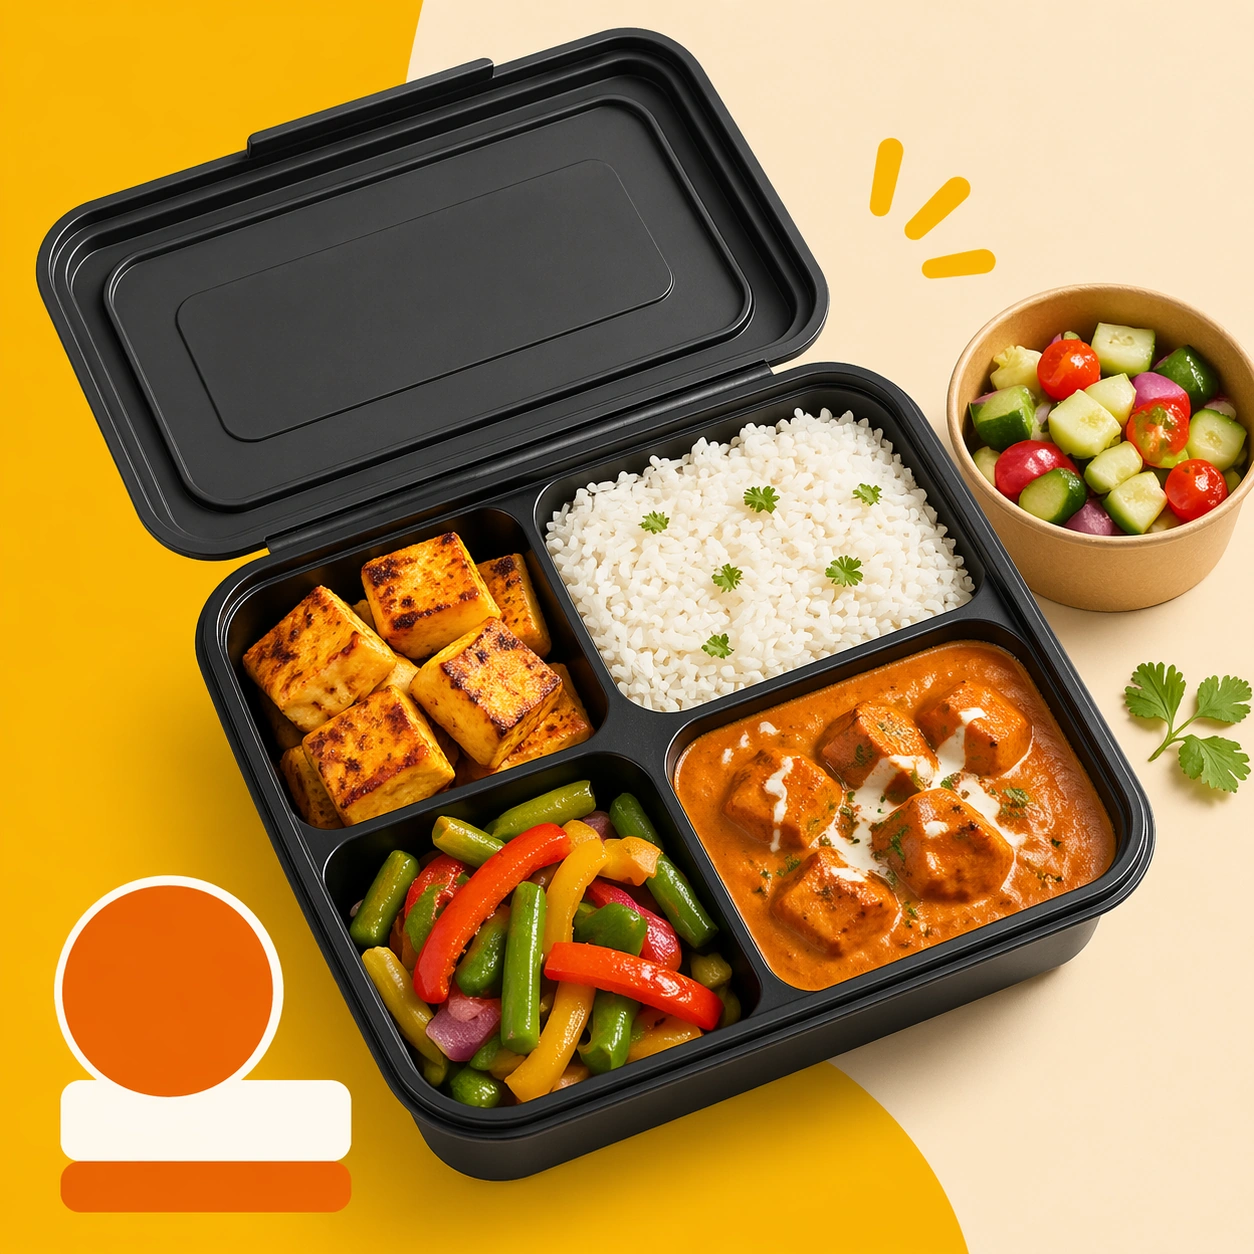
Compose a square food-commerce image optimized for instant readability in app tiles, promo cards, or delivery grids. The image should emphasize appetizing clarity, strong hierarchy, and modular layout zones while staying photorealistic and commercially grounded. Packaging, dish crop, and badge-like design shapes can appear, but all text must remain unreadable. Use a bright square crop with one open lunch container, one side element, and strong modular negative space around the food.

Subject:
The food should look craveable at thumbnail scale, with clear portion logic, supporting side items when relevant, and delivery-aware presentation that prioritizes speed, legibility, and conversion. Make the lunch box feel balanced, complete, and office-friendly, with ingredients separated enough to remain legible on small screens.

Important details:
This theme is about commerce reasoning. Preserve sharp hero food silhouettes, obvious combo structure, and clean tile-safe framing so the assets can survive small screens. Abstract text areas, CTA-like shapes, and offer badges are allowed only as non-legible design modules. Keep everything polished, modern, and immediately useful for ordering surfaces. This image should feel fully self-contained while still belonging to the same broader topic and commercial world. Clean compartment lines, lid geometry, and ingredient color contrast should make the image highly scannable for app browsing.

Use case:
Delivery Tiles single study 5/9, built for Prompt Atlas coverage of a food and beverage commercial visual system.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no readable text, no logos, no app UI chrome, no fake prices, no delivery-bag chaos, no greasy blur, no clutter that hurts thumbnail legibility, no office desk clutter, no readable brand tape, no cafeteria tray vibe.
使い方
- パラメータを含む元のプロンプト全体をコピーします。
- 被写体、文字、構図を自分の要件に置き換えます。
- 対応する外部ツールで使用し、利用条件と結果を確認します。
開始前の確認
- 参考画像の要否を確認してください。互換モデルの表示は、そのモデルでの生成実績を意味しません。
- 名前、数値、画像内の文字を確認します。モデルの版で結果は変わります。