Oryginalny dokument
GPT Image 2 · en
{
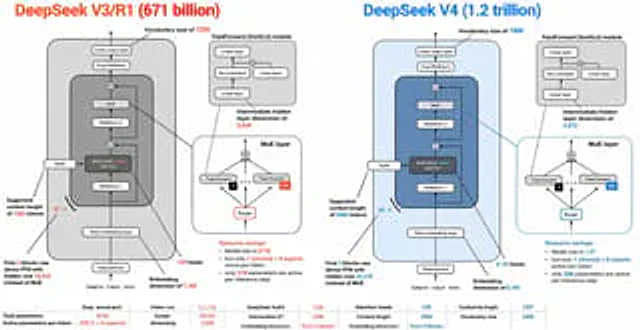
  "type": "Side-by-side AI architecture comparison infographic",
  "style": "Simple technical charts, white background, thin black outline, rounded rectangles, dashed annotation boxes, color-coded highlights, presentation style, vector infographics.",
  "canvas": {
    "aspect_ratio": "2:1",
    "resolution": "Horizontal width"
  },
  "title_row": {
    "left_title": "DeepSeek V3/R1 (671 billion parameters)",
    "right_title": "DeepSeek V4 (1.2 trillion parameters)",
    "left_title_color": "Bright orange-red",
    "right_title_color": "Bright blue"
  },
  "layout": {
    "columns": 2,
    "sections": [
      {
        "title": "DeepSeek V3/R1 (671 billion parameters)",
        "position": "left half",
        "count": 9,
        "labels": [
          "Vocabulary size 129k",
          "FeedForward (SwiGLU) module",
          "The intermediate hidden layer has a dimension of 2,048.",
          "MoE Layer",
          "Supports 128k token context length",
          "The first three blocks use a dense FFN with a hidden size of 18,432 instead of MoE.",
          "Example text input",
          "Embedding dimension 7,168",
          "128 attention heads"
        ]
      },
      {
        "title": "DeepSeek V4 (1.2 trillion parameters)",
        "position": "right half",
        "count": 9,
        "labels": [
          "Vocabulary size 160k",
          "FeedForward (SwiGLU) module",
          "The intermediate hidden layer has a dimension of 3,072.",
          "MoE Layer",
          "Supports 256k token context length",
          "The first three blocks use a dense FFN with a hidden size of 24,576 instead of MoE.",
          "Example text input",
          "Embedding dimension 8,192",
          "128 attention heads"
        ]
      },
      {
        "title": "Bottom Comparison Table",
        "position": "Bottom full width",
        "count": 10,
        "labels": [
          "Total number of parameters",
          "Number of active parameters per token",
          "Hidden layer size",
          "Example Dimension",
          "DeepSeek V3/R1",
          "Intermediate layer (FF)",
          "Attention",
          "Context length",
          "Embedded Dimension",
          "Vocabulary size"
        ]
      }
    ]
  },
  "left_panel": {
    "background": "Light gray rounded rectangle",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token Embedding Layer",
        "RMSNorm 1",
        "Multi-head potential attention (MLA)",
        "RMSNorm 2",
        "MoE",
        "Ultimately, RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "RoPE connects to the attention block on the left.",
    "attention_block": {
      "label": "Multi-head potential attention (MLA)",
      "accent": "The word \"Latent\" is displayed in orange-red lettering."
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "linear layer",
        "SiLU activation function",
        "linear layer",
        "linear layer"
      ],
      "diagram": "Multiply the two branches, then project them."
    },
    "moe_inset": {
      "title": "MoE Layer",
      "count": 5,
      "blocks": [
        "Top composite node",
        "Feedforward network",
        "Feedforward network",
        "routing",
        "Expert Counting Badge 256"
      ],
      "details": "A small black square with one selected expert, an arrow pointing to the expert, and a dashed line separator."
    },
    "annotations": {
      "vocab": "Vocabulary size 129k",
      "ff_dim": "The intermediate hidden layer has a dimension of 2,048.",
      "context": "Supports 128k token context length",
      "dense_first_blocks": "The first three blocks use a dense FFN with a hidden size of 18,432 instead of MoE.",
      "resource_savings": "Resource savings: The model size is 671 bytes, but each token activates only 1 (shared) + 8 experts; only 37 bytes of parameters are activated per inference step."
    },
    "bottom_stats": {
      "count": 10,
      "items": [
        "Total number of parameters: 671B",
        "Activity parameters per token: 37B (1 + 8 experts)",
        "Hidden layer size: 7,128",
        "Example dimension: 28,432",
        "Intermediate layer (FF): 2,048",
        "Attention: 128",
        "Context length: 128k",
        "Embedding dimension: the first 3 blocks",
        "Context length: 22G7",
        "Vocabulary size: 129k"
      ]
    }
  },
  "right_panel": {
    "background": "Light blue rounded rectangle",
    "main_stack": {
      "count": 8,
      "blocks": [
        "Tokenized text",
        "Token Embedding Layer",
        "RMSNorm 1",
        "Multi-head potential attention (MLA)",
        "RMSNorm 2",
        "MoE",
        "Ultimately, RMSNorm",
        "Linear output layer"
      ]
    },
    "side_module": "RoPE connects to the attention block on the left.",
    "attention_block": {
      "label": "Multi-head potential attention (MLA)",
      "accent": "The word \"Latent\" is in blue text."
    },
    "feedforward_inset": {
      "title": "FeedForward (SwiGLU) module",
      "count": 4,
      "blocks": [
        "linear layer",
        "SiLU activation function",
        "linear layer",
        "linear layer"
      ],
      "diagram": "Same structure as the left panel"
    },
    "moe_inset": {
      "title": "MoE Layer",
      "count": 5,
      "blocks": [
        "Top composite node",
        "Feedforward network",
        "Feedforward network",
        "routing",
        "Expert Counting Badge 384"
      ],
      "details": "A small black square with one selected expert, an arrow pointing to the expert, a dashed separator, and a blue border for emphasis."
    },
    "annotations": {
      "vocab": "Vocabulary size 160k",
      "ff_dim": "The intermediate hidden layer has a dimension of 3,072.",
      "context": "Supports 256k token context length",
      "dense_first_blocks": "The first three blocks use a dense FFN with a hidden size of 24,576 instead of MoE.",
      "resource_savings": "Resource savings: The model size is 1.2T, but each token only activates 1 (shared) + 8 experts; only 52B parameters are activated per inference step."
    },
    "bottom_stats": {
      "count": 10,
      "items": [
        "Total parameters: 1.2T",
        "Activity parameters per token: 52B (1 + 8 experts)",
        "Hidden layer size: 7.2B",
        "Example dimension: 28,432",
        "Intermediate layer (FF): 3,072",
        "Attention: 128",
        "Context length: 256k",
        "Embedding dimension: the first 3 blocks",
        "Context length: 22G7",
        "Vocabulary size: 160k"
      ]
    }
  },
  "global_notes": "Create a highly detailed Transformer architecture comparison diagram using a mirrored layout. Each half contains a large model stack diagram and two illustrations: one feedforward module and one MoE layer. Use arrows between blocks, add tiny technical labels, and use connecting lines to link the labels to related components. Keep the typography compact and presentation-like, using orange-red for all V3/R1 and blue for all V4. Include a compact metrics table spanning full width at the bottom. Retain the slightly imperfect hand-drawn infographic style, with small text and dense annotations."
}
Jak używać
- Skopiuj cały oryginalny prompt wraz z parametrami.
- Dostosuj temat, tekst i kompozycję do swoich potrzeb.
- Użyj zgodnego narzędzia zewnętrznego; sprawdź warunki dostępu i wynik.
Przed rozpoczęciem
- Sprawdź, czy potrzebny jest obraz referencyjny. Zgodność nie potwierdza modelu użytego do przykładu.
- Sprawdź nazwy, liczby i napisy; wyniki zależą od wersji modelu.