原始文档
GPT Image 2 · en
Scene:
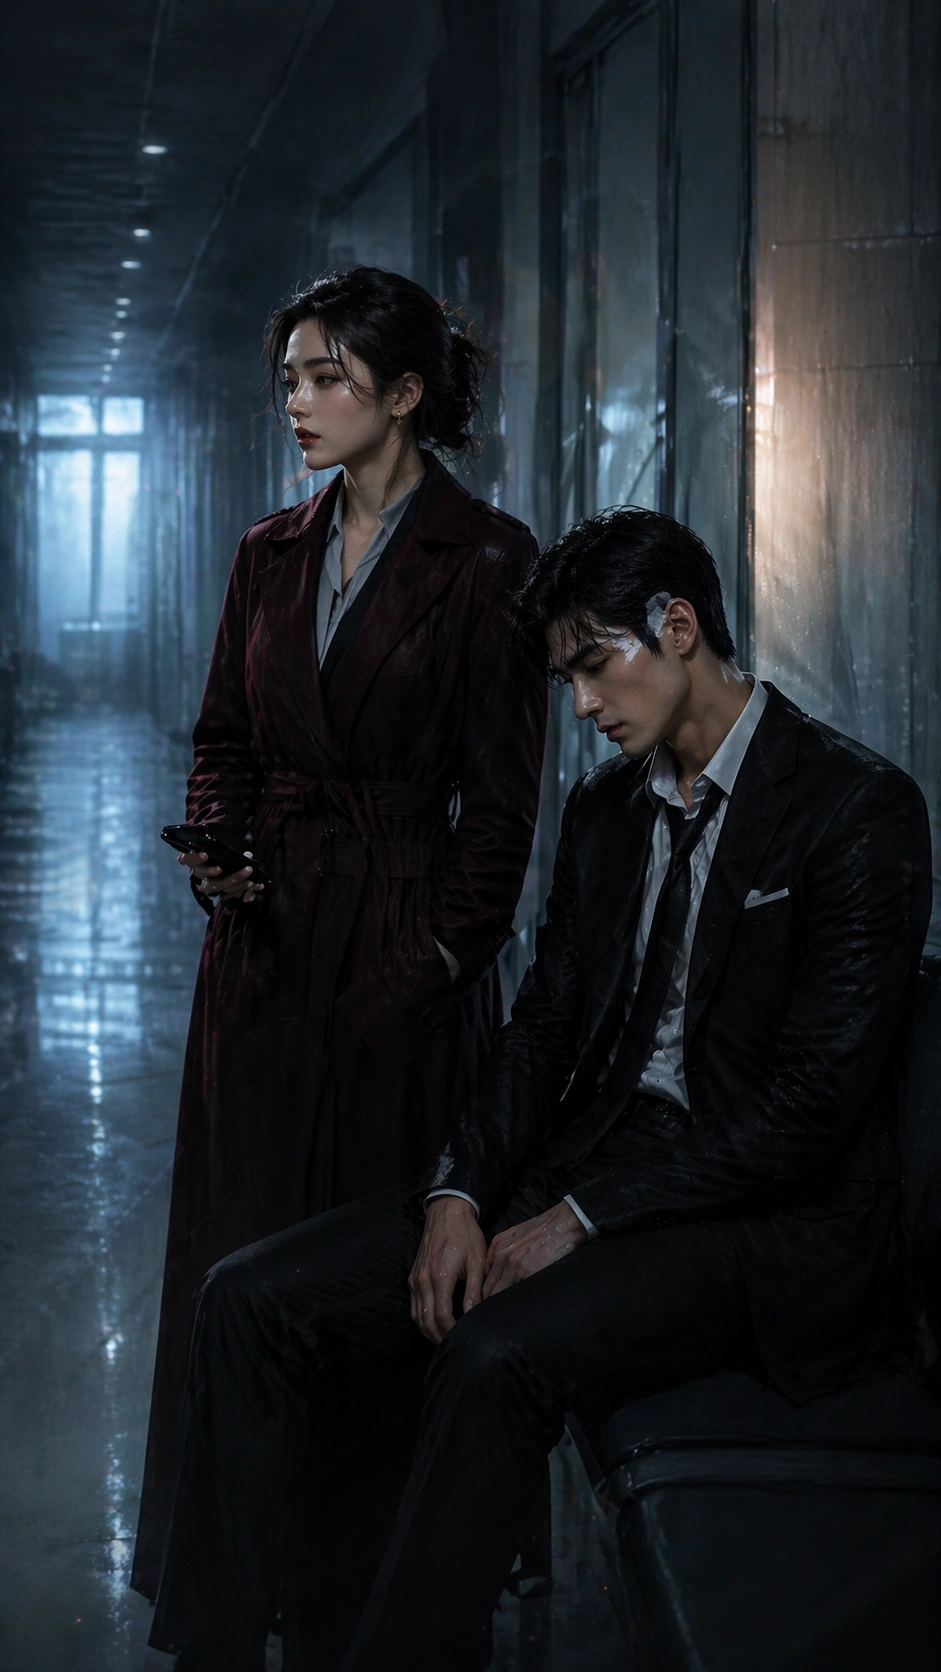
A tall 9:16 episode poster in a private hospital corridor before dawn, with sterile overhead lighting softened by blue morning haze, frosted glass panels, muted reflections on pale floor tiles, and one thin warm bedside glow leaking from an unseen room. The layout should feel engineered for mobile conversion: clear headroom for a hook image, central emotional scene, and a lower band quiet enough for future platform badges or titles that remain unreadable here.

Subject:
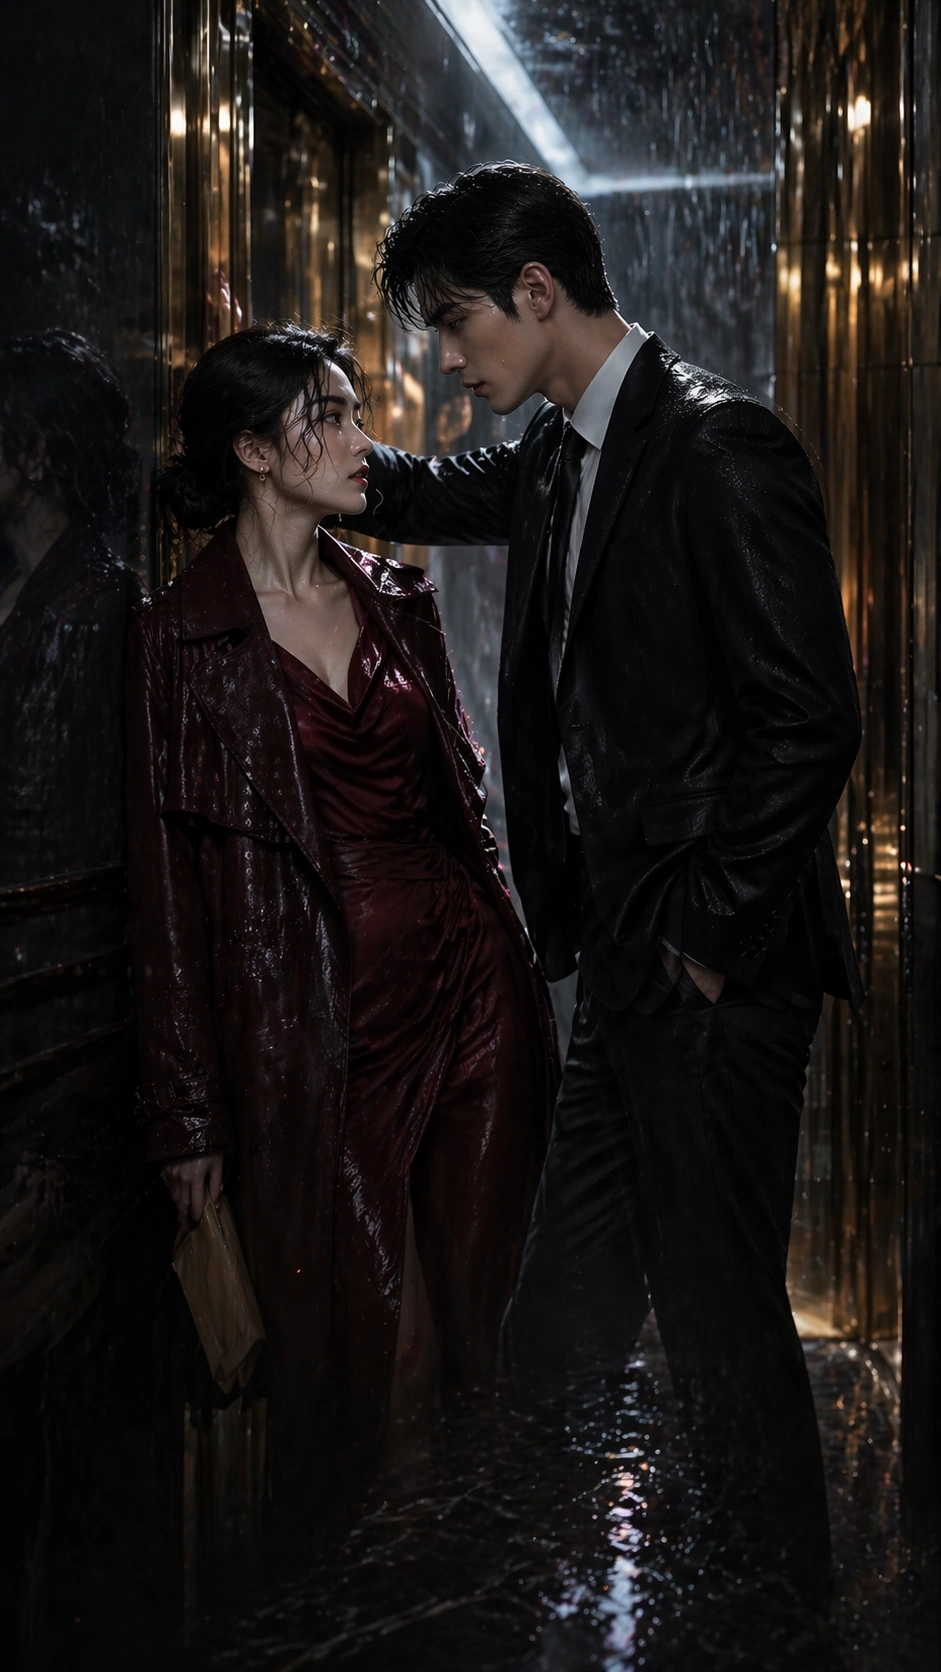
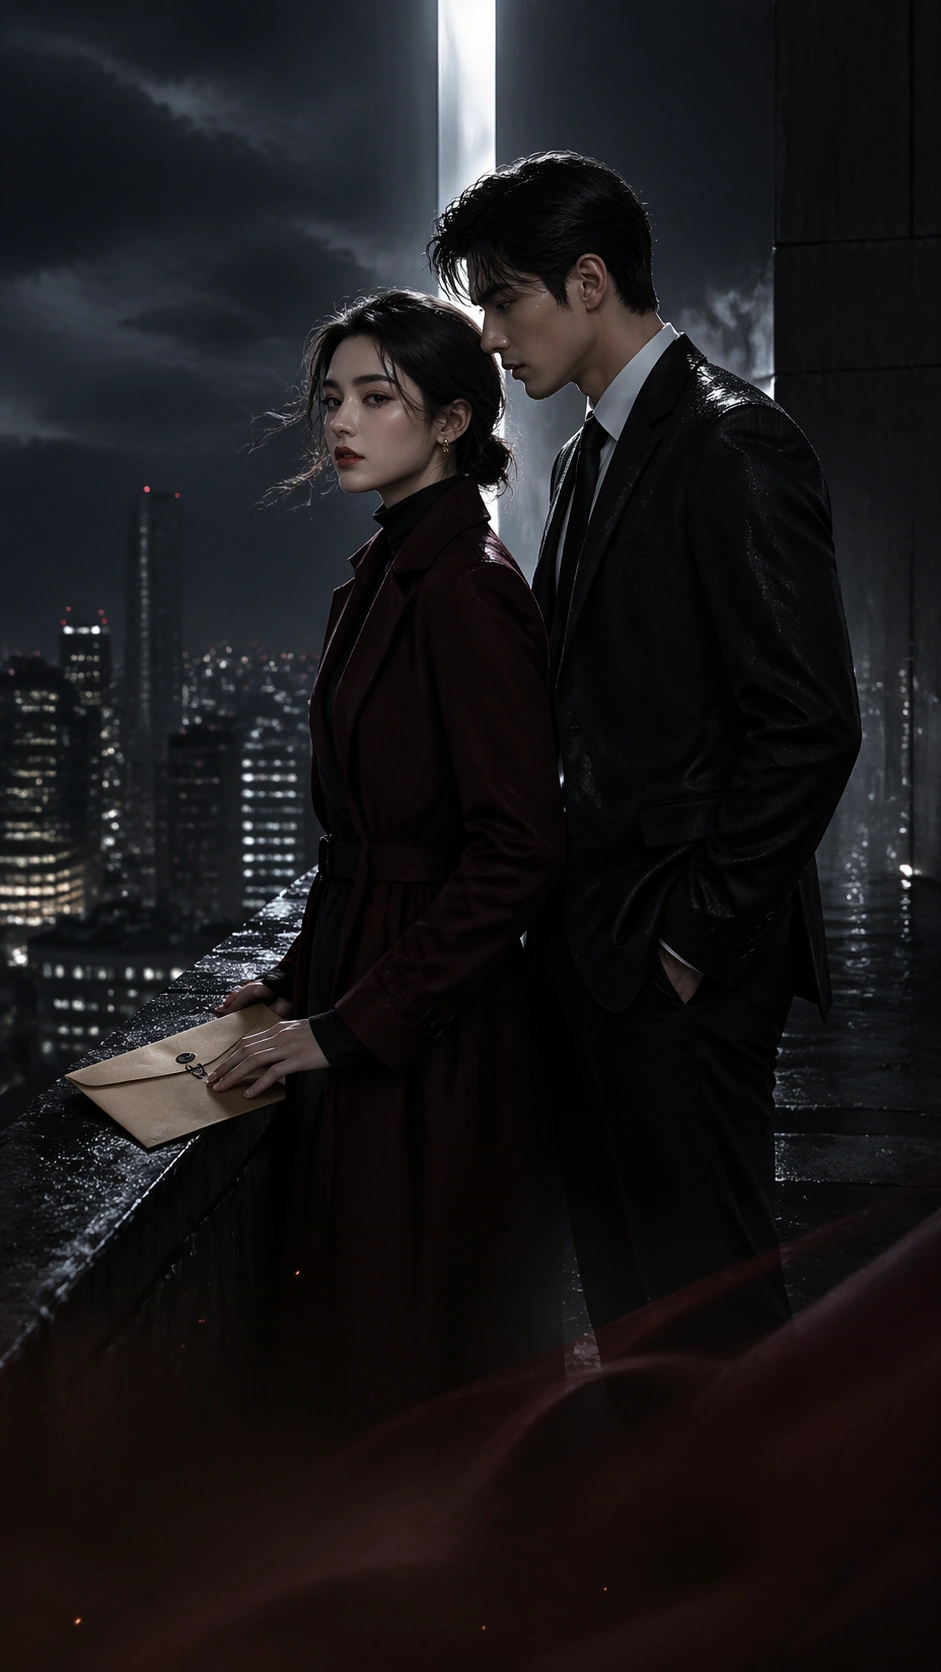
Using the referenced pair as the continuity source, preserve the same heiress and bodyguard from image 01, now worn down by accumulated conflict. The bodyguard sits injured on a hallway bench with shirt collar loosened and bandage at the temple; the heiress stands beside him in a severe coat over hospital visitor clothes, holding his phone but looking away to hide concern. Their poses should suggest a temporary truce and emotional turning point. Keep their faces, height relationship, hair shapes, and key costume language consistent with the reference poster.

Important details:
This image should prove that serial consistency can survive a quieter chapter. The vertical poster must remain clean, dramatic, and app-cover legible even though the action is minimal. Use corridor depth, glass reflections, bandage detail, and subdued body language instead of noisy plot props. The result should feel like an episode-cover cliffhanger that invites taps while still resembling polished commercial key art.

Use case:
Vertical Drama Poster System series study 4/9, testing a softer hospital-truce chapter while preserving the same reference couple and narrow-screen poster logic.

Constraints:
No readable text, no watermark, no logos, preserve exact 9:16 aspect ratio, no medical-drama clutter, no extra nurses, no comedy warmth, no giant medical monitors, no hand-holding cliché, no washed-out blank corridor, no visible app UI chrome.
使用方法
- 复制完整原始提示词,并保留其中的参数。
- 按需求替换主体、文字和构图要求。
- 在兼容的外部工具中使用,核对当前使用条件并检查结果。
开始前需了解
- 先确认是否需要参考图。标注兼容模型,不代表该示例由这个模型生成。
- 核对名称、数字与画面文字;不同模型版本的结果可能不同。