Original document
GPT Image 2 · en
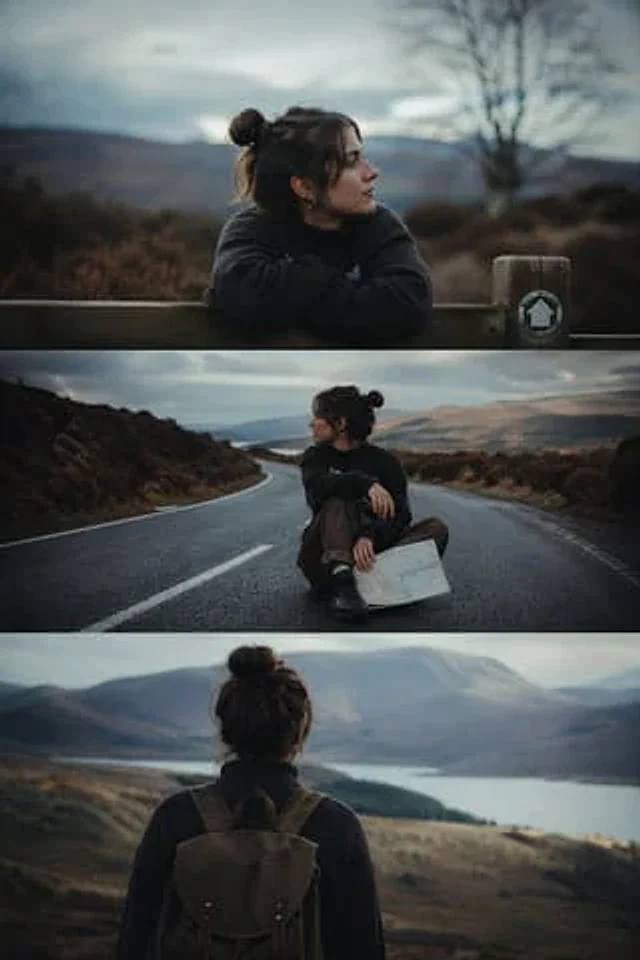
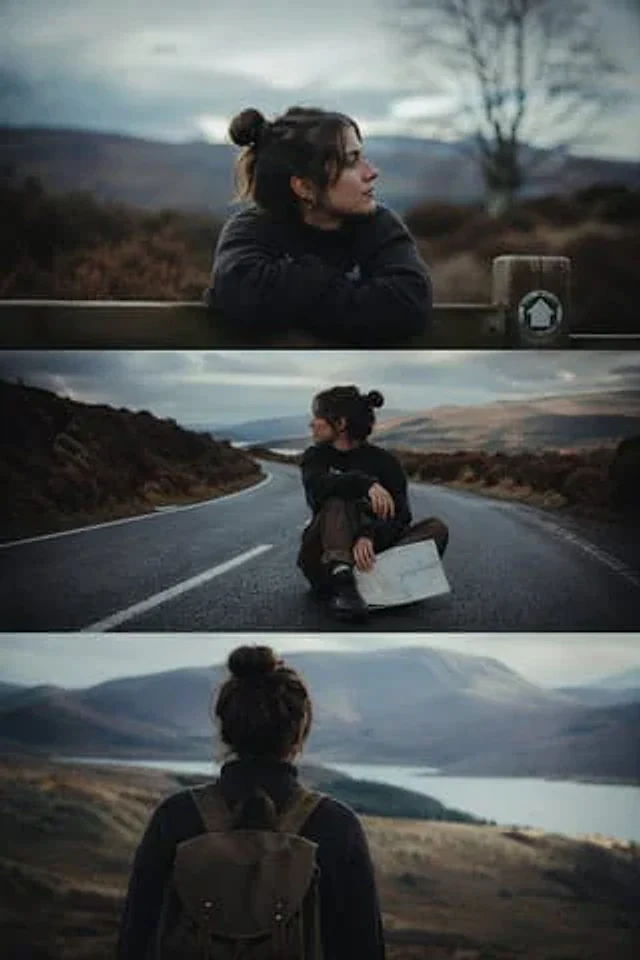
{"type":"cinematic 3-frame sequential film stills","style":"ultra-realistic, moody, natural light, shallow depth of field, muted earthy color grading, soft overcast atmosphere, subtle film grain","subject":{"count":1,"description":"young woman traveler with dark brown hair in a messy bun, wearing a dark oversized sweater, brown trousers, and hiking boots","face_visibility":"face turned away or in profile in all 3 frames"},"layout":{"orientation":"vertical triptych with 3 stacked horizontal frames separated by thin borders","sections":[{"title":"top frame","position":"top","count":1,"labels":["woman leaning with folded arms on a wooden fence, looking to the right"]},{"title":"middle frame","position":"center","count":1,"labels":["woman sitting alone in the middle of an empty winding road, holding a folded paper map, looking left"]},{"title":"bottom frame","position":"bottom","count":1,"labels":["rear view of woman wearing a rugged backpack, standing and looking over a lake and mountain valley"]}]},"environment":{"location":"remote highland landscape with rolling hills, sparse leafless trees, heather and brush, distant mountains, and a lake","weather":"cloudy, cool, slightly misty"},"camera":{"framing":"cinematic storytelling sequence, medium portrait in top frame, full-body seated shot in middle frame, medium back view in bottom frame","lens":"shallow-focus documentary photography look","aspect":"tall vertical image"},"details":{"props_count":3,"props":["wooden fence with a small circular trail marker sign showing a white house-like icon","folded paper map","brown canvas hiking backpack"]}}How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.