
Original document
GPT Image 2 · en
Scene:
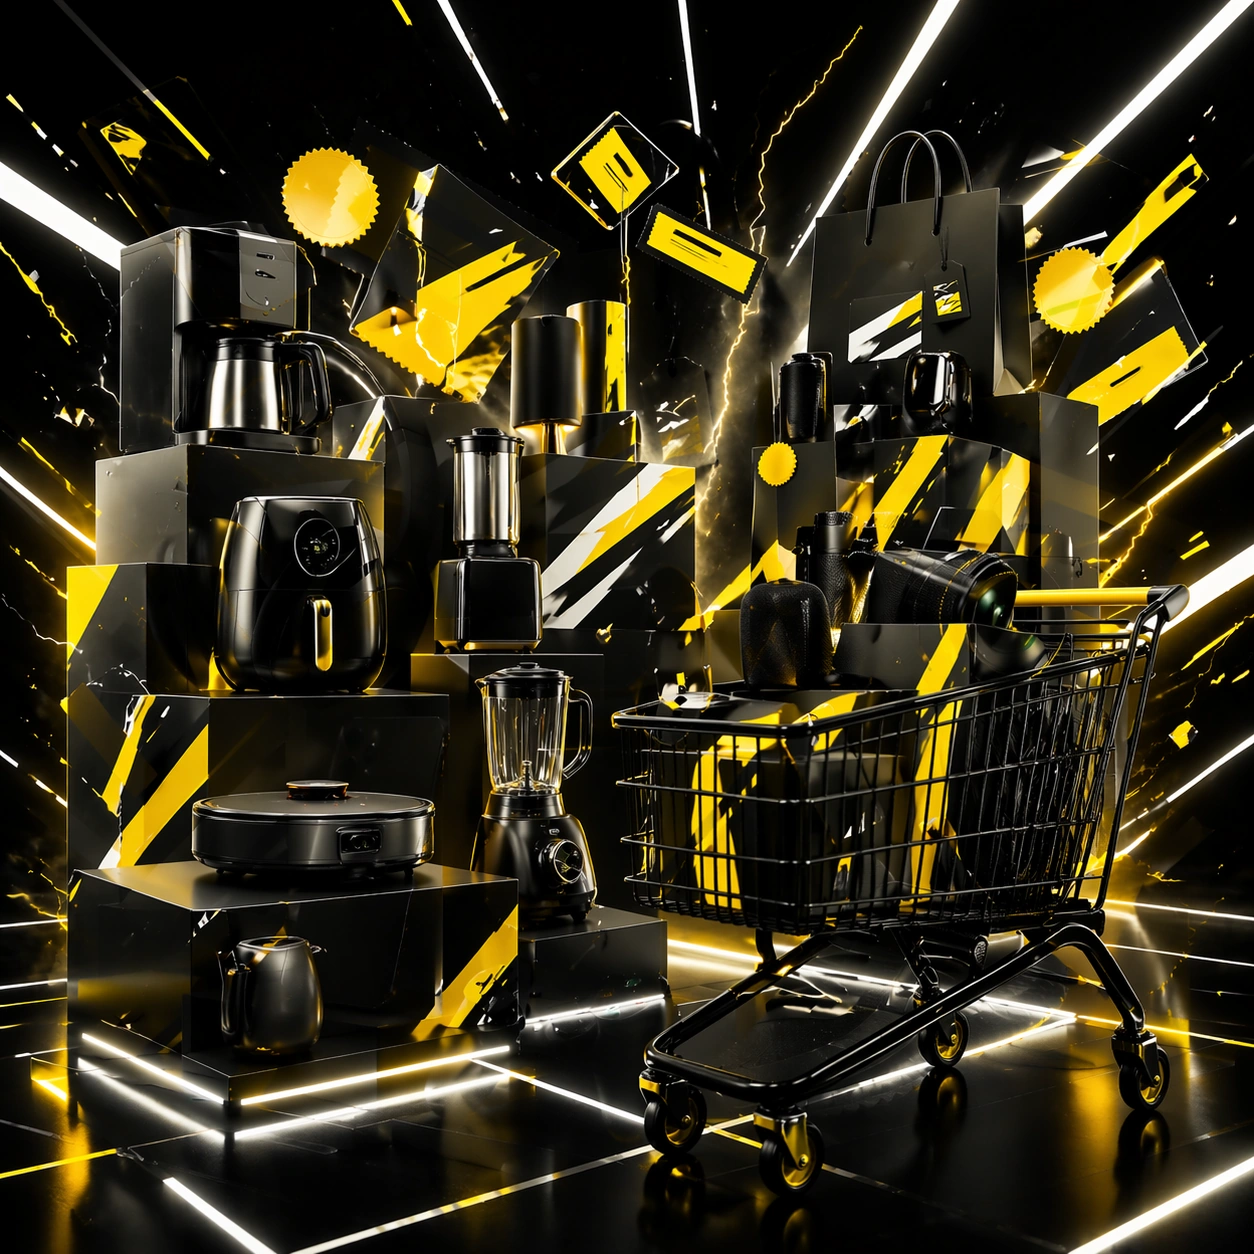
Create a square dependent campaign image within the same Black Friday world, using the exact black base, stark white bars, yellow sale accents, and crisp reflected light from the reference image, but expand the space to suggest a cart-driven retail scene. The frame should stay graphic and pressure-heavy while introducing more environment cues around stacked goods and checkout movement.

Subject:
Feature home-tech-like products, boxed appliances or accessories, cart silhouettes, and abstract sale surfaces arranged into a premium frenzy composition. Preserve exact layout logic, accent rhythm, and lighting identity from the reference model while shifting the scene toward basket-building and cart urgency. The imagery must remain original, non-branded, and optimized for campaign usability.

Important details:
Treat this as the same sale grammar under a new retail use case. Maintain crisp hierarchy, disciplined geometry, and strong thumbnail read. The cart cue should strengthen urgency without turning the image into a literal supermarket shot. Keep reflections, box edges, and accent panels believable and polished. The final asset should feel like a direct extension of the reference campaign, ready for homepage takeovers or app sale promotions.

Use case:
Black Friday series study 4/9.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, preserve exact campaign identity from the reference image, no readable checkout screens, no currency symbols, no supermarket aisle clutter, no logo boxes, no human crowd, no random red holiday cues, no low-end bargain-bin mess.
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.