Original document
GPT Image 2 · en
{
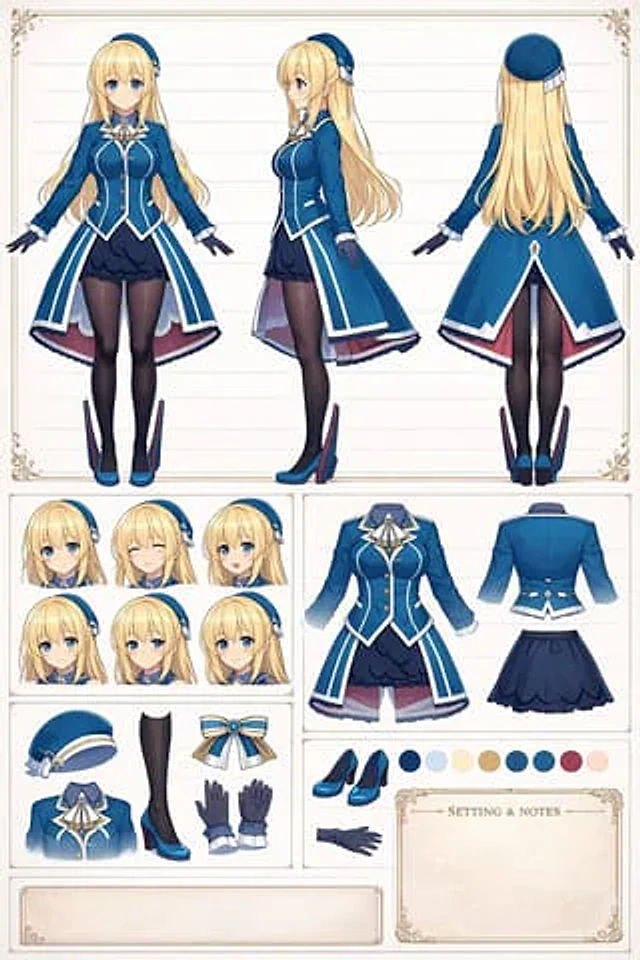
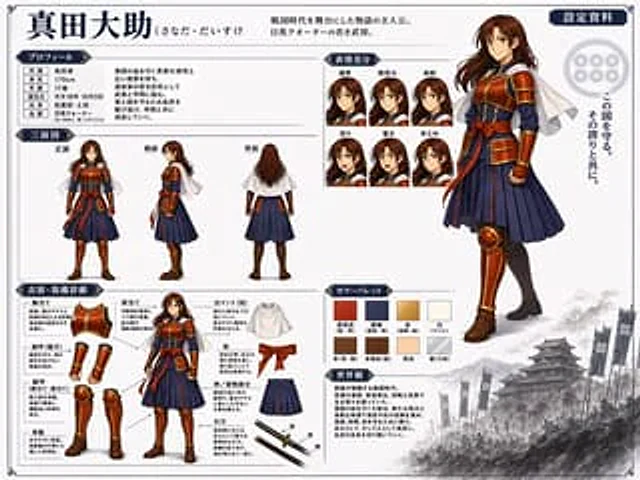
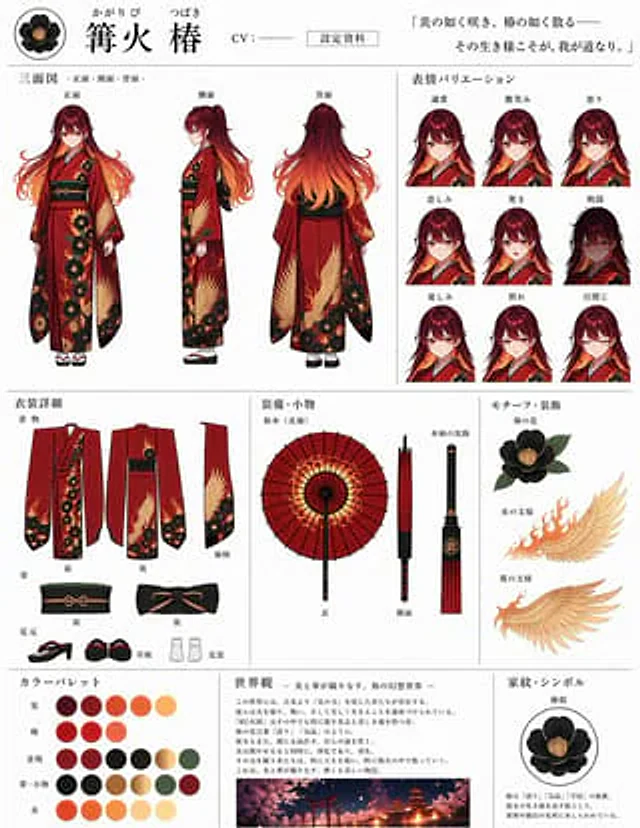
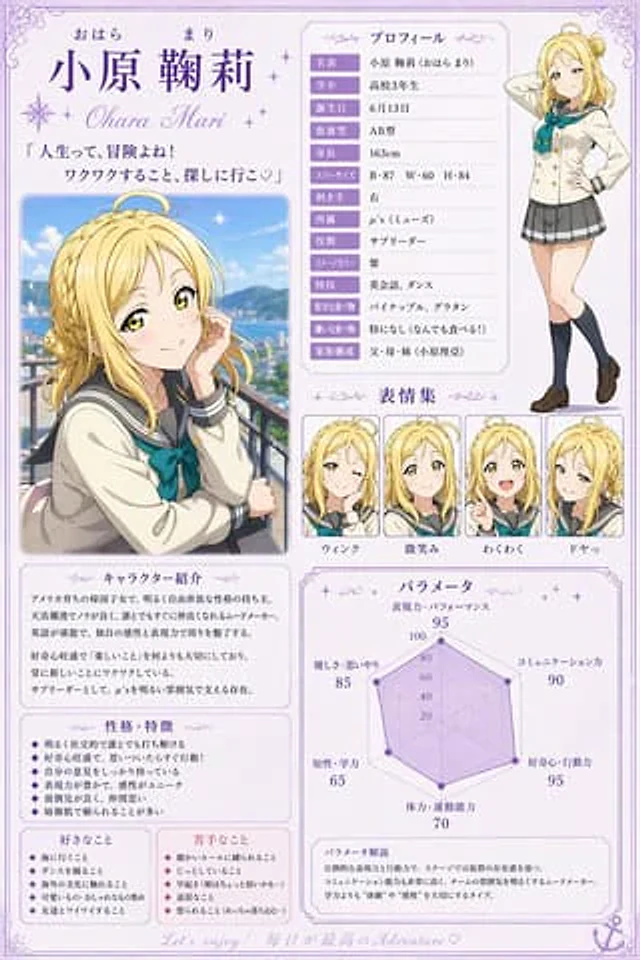
  "type": "Anime Character Design Collection",
  "character": {
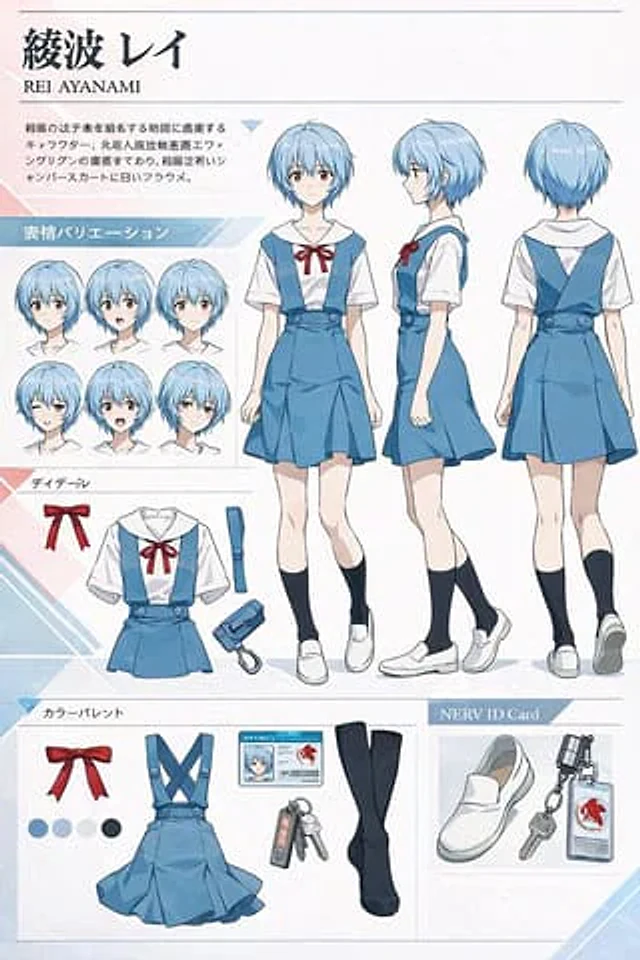
    "name_japanese": "{argument name=\"character name\" default=\"Rei Ayanami\"}",
    "name_english": "{argument name=\"english name\" default=\"REI AYANAMI\"}",
    "hair": "{argument name=\"hair color\" default=\"light blue\"} shortwave head",
    "eyes": "{argument name=\"eye color\" default=\"red\"}",
    "outfit": "{argument name=\"outfit\" default=\"Blue vest dress, white short-sleeved shirt, red bow tie, black over-the-knee socks, white flat shoes\"}"
  },
  "layout": {
    "header": {
      "position": "Top left corner",
      "elements": [
        "Japanese name",
        "English name",
        "A Japanese descriptive text"
      ]
    },
    "turnaround": {
      "position": "right side",
      "count": 3,
      "poses": [
        "front",
        "side",
        "back"
      ]
    },
    "sections": [
      {
        "title": "Facial expressions",
        "position": "Middle left",
        "count": 6,
        "description": "Avatars with different expressions: neutral, slight smile, surprised, blinking, open mouth, head down."
      },
      {
        "title": "Detailed display",
        "position": "Lower left",
        "count": 4,
        "items": [
          "Red bow",
          "Uniform upper body",
          "Blue shoulder strap",
          "small blue bag"
        ]
      },
      {
        "title": "Color scheme",
        "position": "bottom left corner",
        "count": 5,
        "items": [
          "Red bow",
          "blue vest dress",
          "Mini ID Card",
          "Black socks",
          "Four circular color blocks (blue, light blue, white, and black)."
        ]
      },
      {
        "title": "NERV ID Card",
        "position": "bottom right corner",
        "count": 3,
        "items": [
          "White flats",
          "keychain",
          "NERV identification tag on the lanyard"
        ]
      }
    ]
  },
  "style": "Official anime concept art, cel-shaded style, clean lines, white background with light blue geometric decorations."
}
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.