Original document
GPT Image 2 · en
Scene:
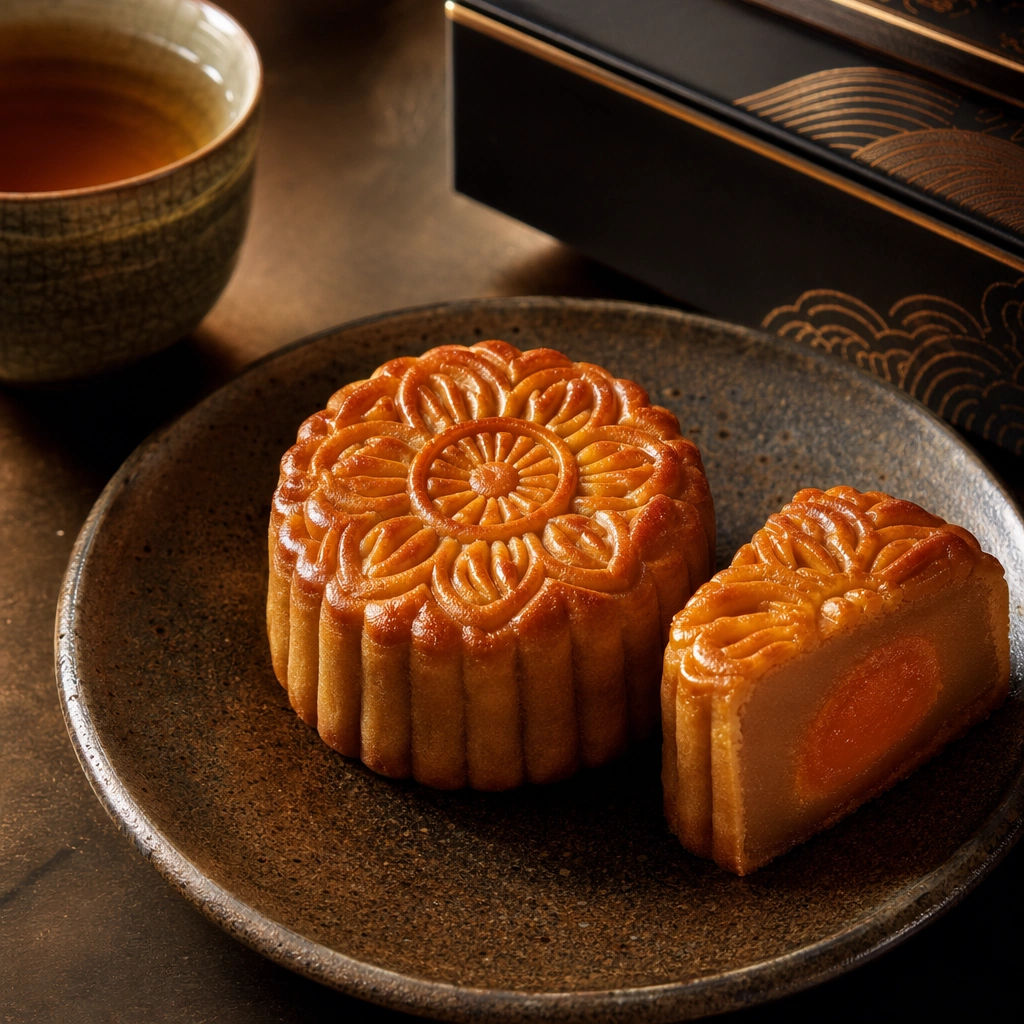
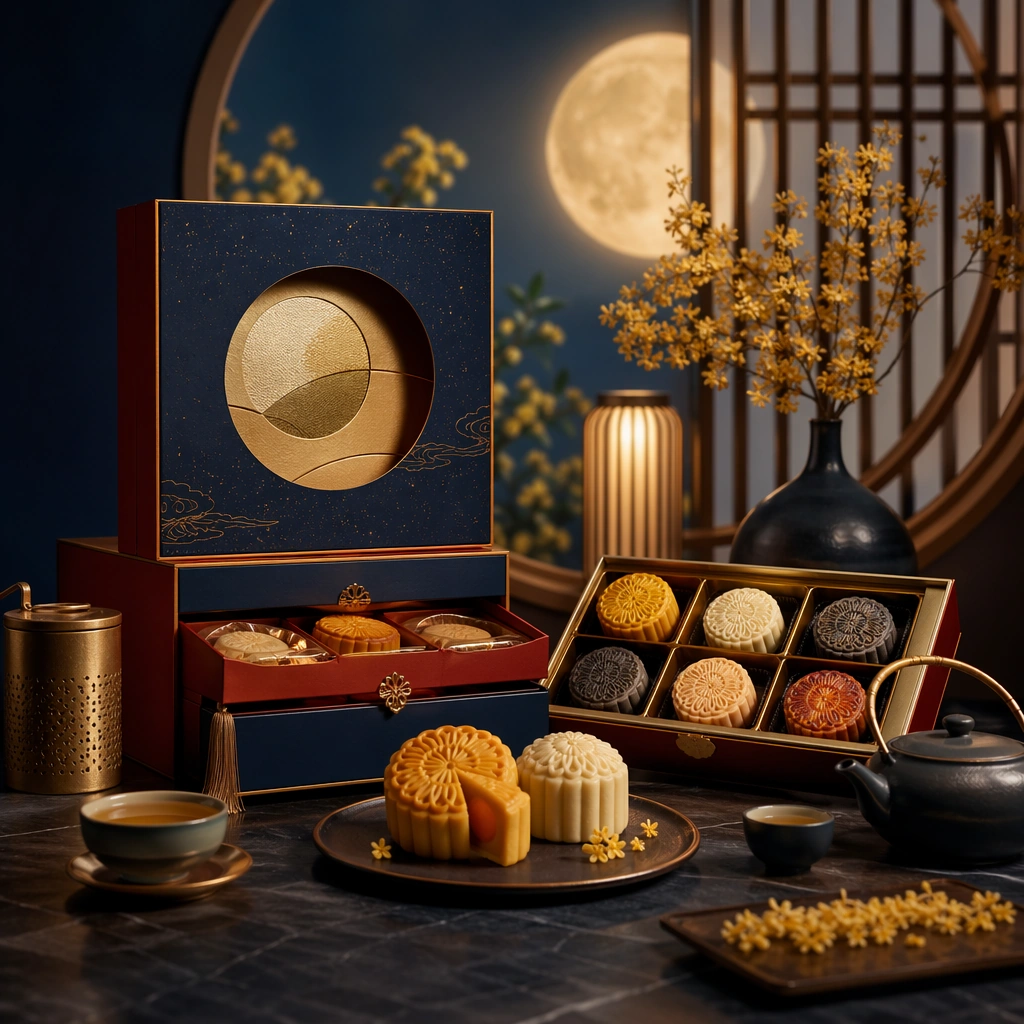
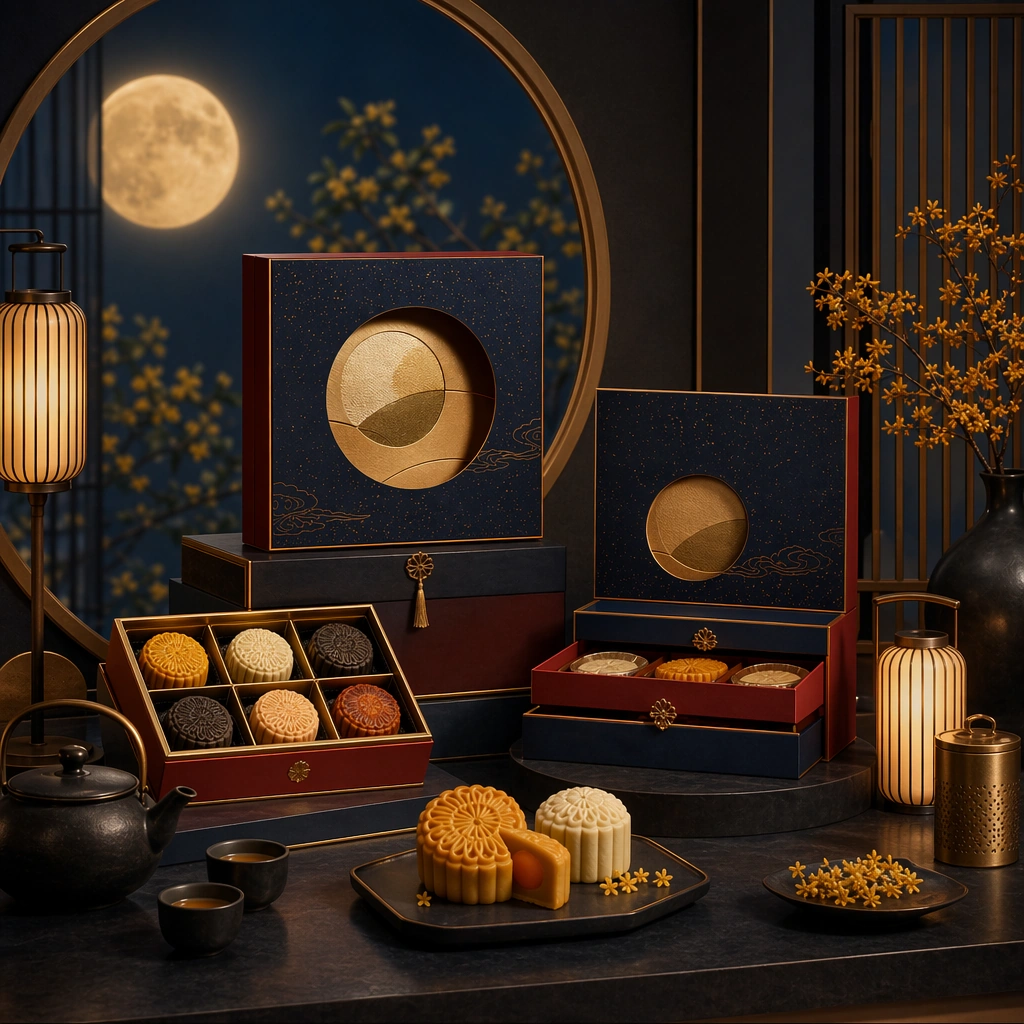
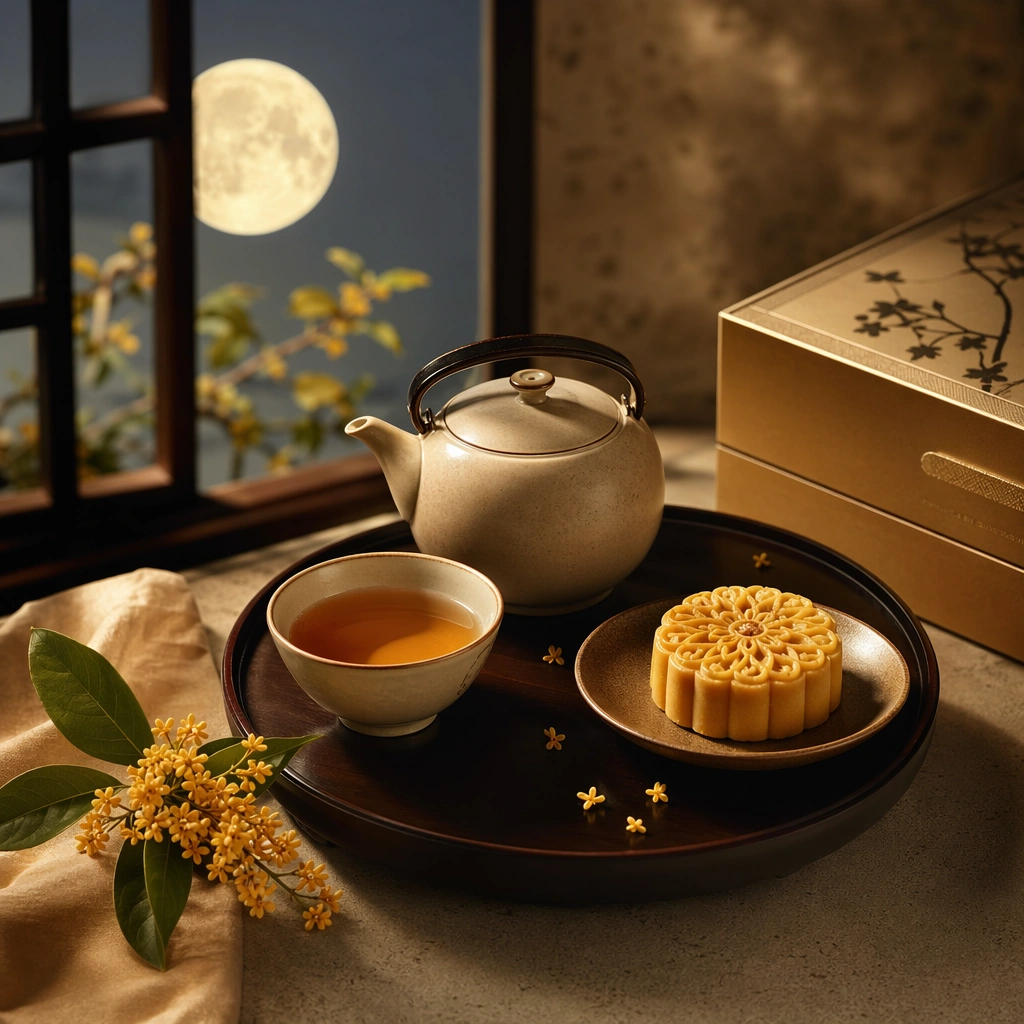
Create a square still-life image on a calm tabletop with warm evening light, moon-adjacent cool shadows, and refined negative space. The frame should feel like a premium tea or gifting campaign visual, with a mature sense of calm and balance. Use a restrained palette of warm gold, muted cream, dark wood or lacquer, and one or two floral accents that suggest seasonality without turning decorative.

Subject:
Show a tea service with cup, pot, tray, small pastry, gift box edge, and osmanthus-like floral detail arranged into a poised Mid-Autumn still life. The composition should communicate fragrance, hospitality, and premium gifting readiness through object relationships. Keep everything original and brand-neutral, free of readable script and heavy ornament overload.

Important details:
Focus on tactile precision: ceramic glaze, tea translucency, lacquer sheen, floral softness, and subtle atmospheric depth. The image should be calm enough for premium tea branding but still unmistakably seasonal through its moonlit warmth and gifting context. Avoid generic zen clichés; this should feel festive, specific, and commercially ready.

Use case:
Mid-Autumn single study 7/9.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no readable tea labels, no logo cups, no incense smoke overload, no fantasy temple set, no mascot animals, no bright red saturation, no cluttered table, no calligraphy scrolls.
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.