Original document
GPT Image 2 · en
Scene:
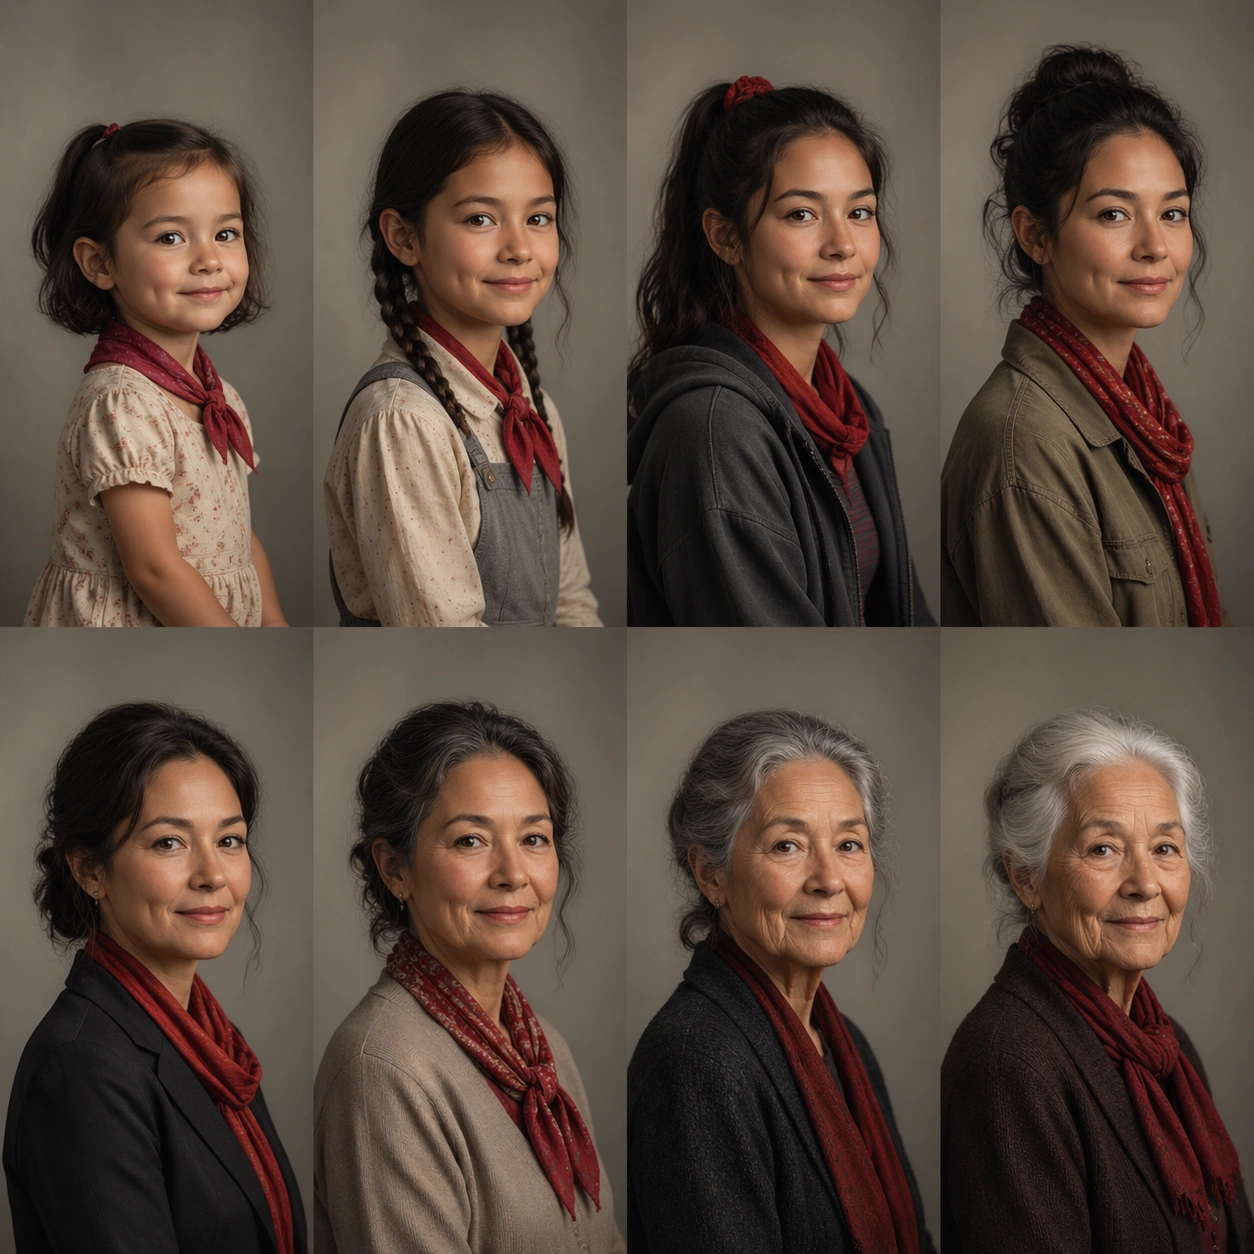
A square studio character reference sheet on a quiet neutral background, arranged as eight portrait-and-half-body studies in a clean 4 by 2 grid with no captions. Use soft editorial lighting, restrained warm gray tones, and consistent camera height. The image should feel like a production reference board for a conceptual film about one life seen all at once.

Subject:
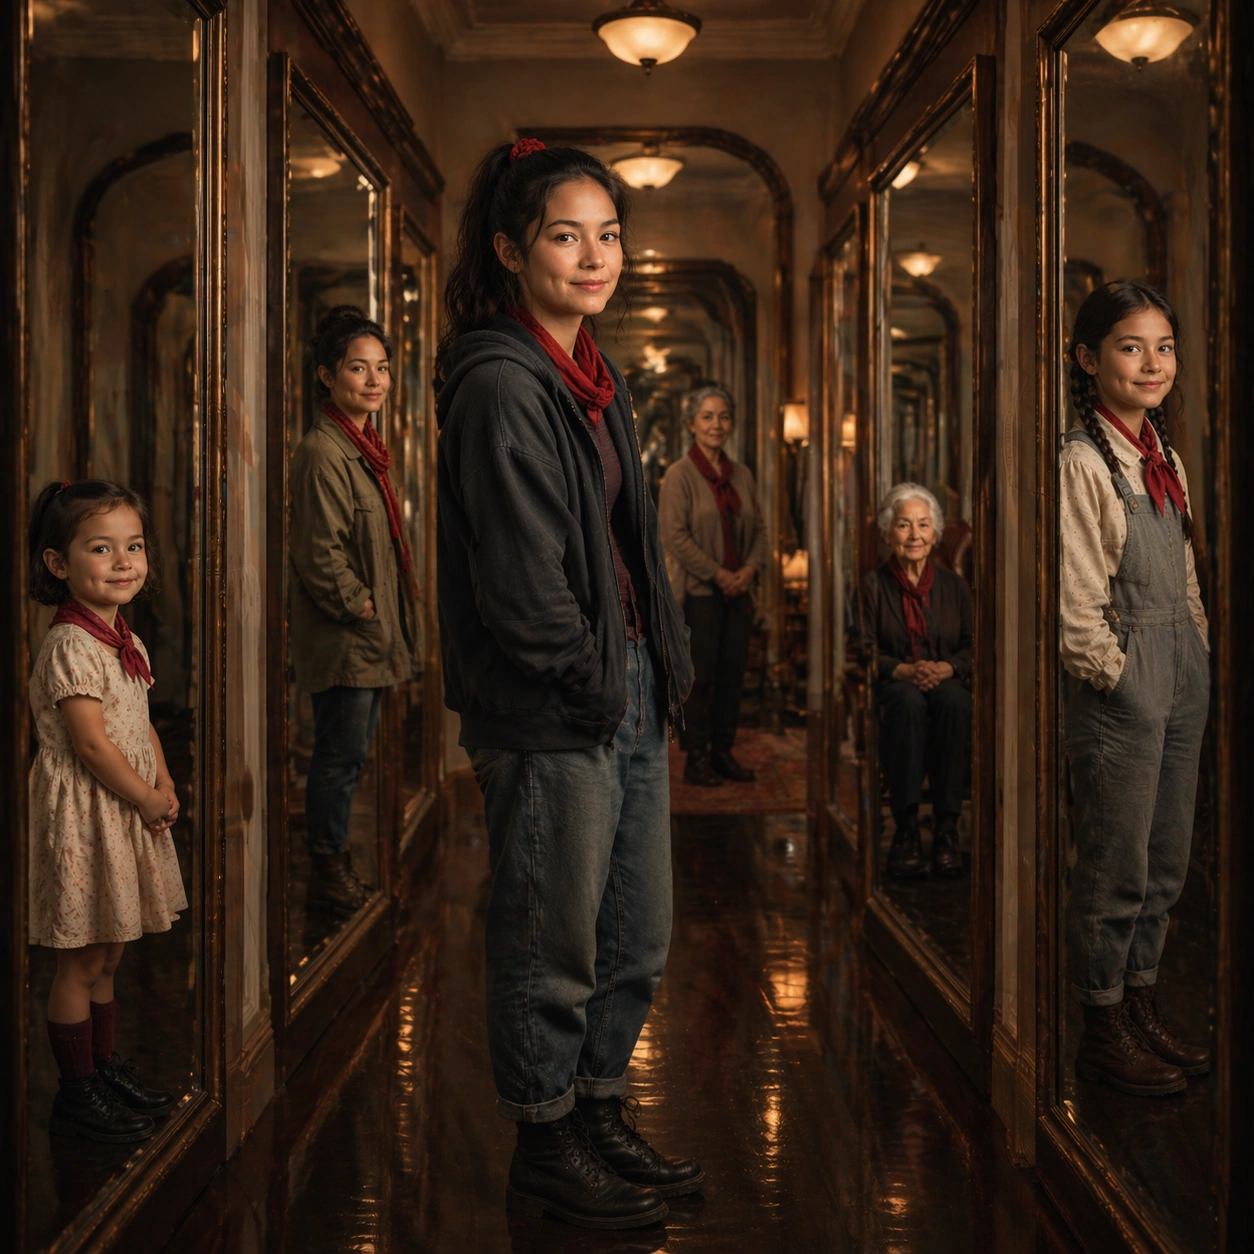
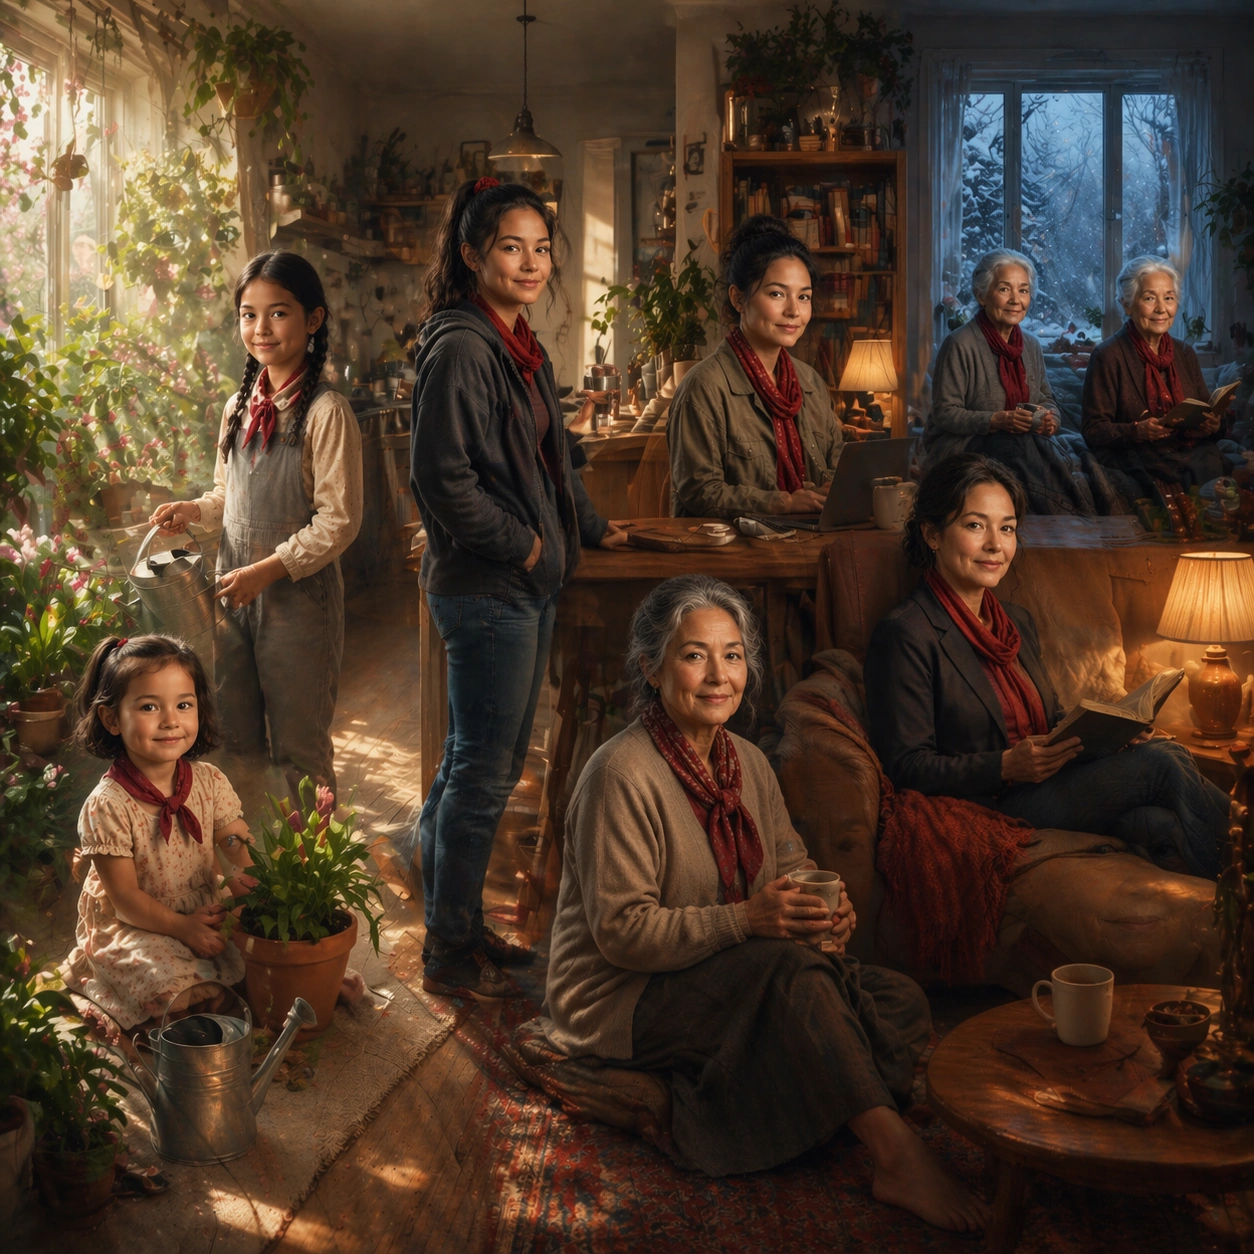
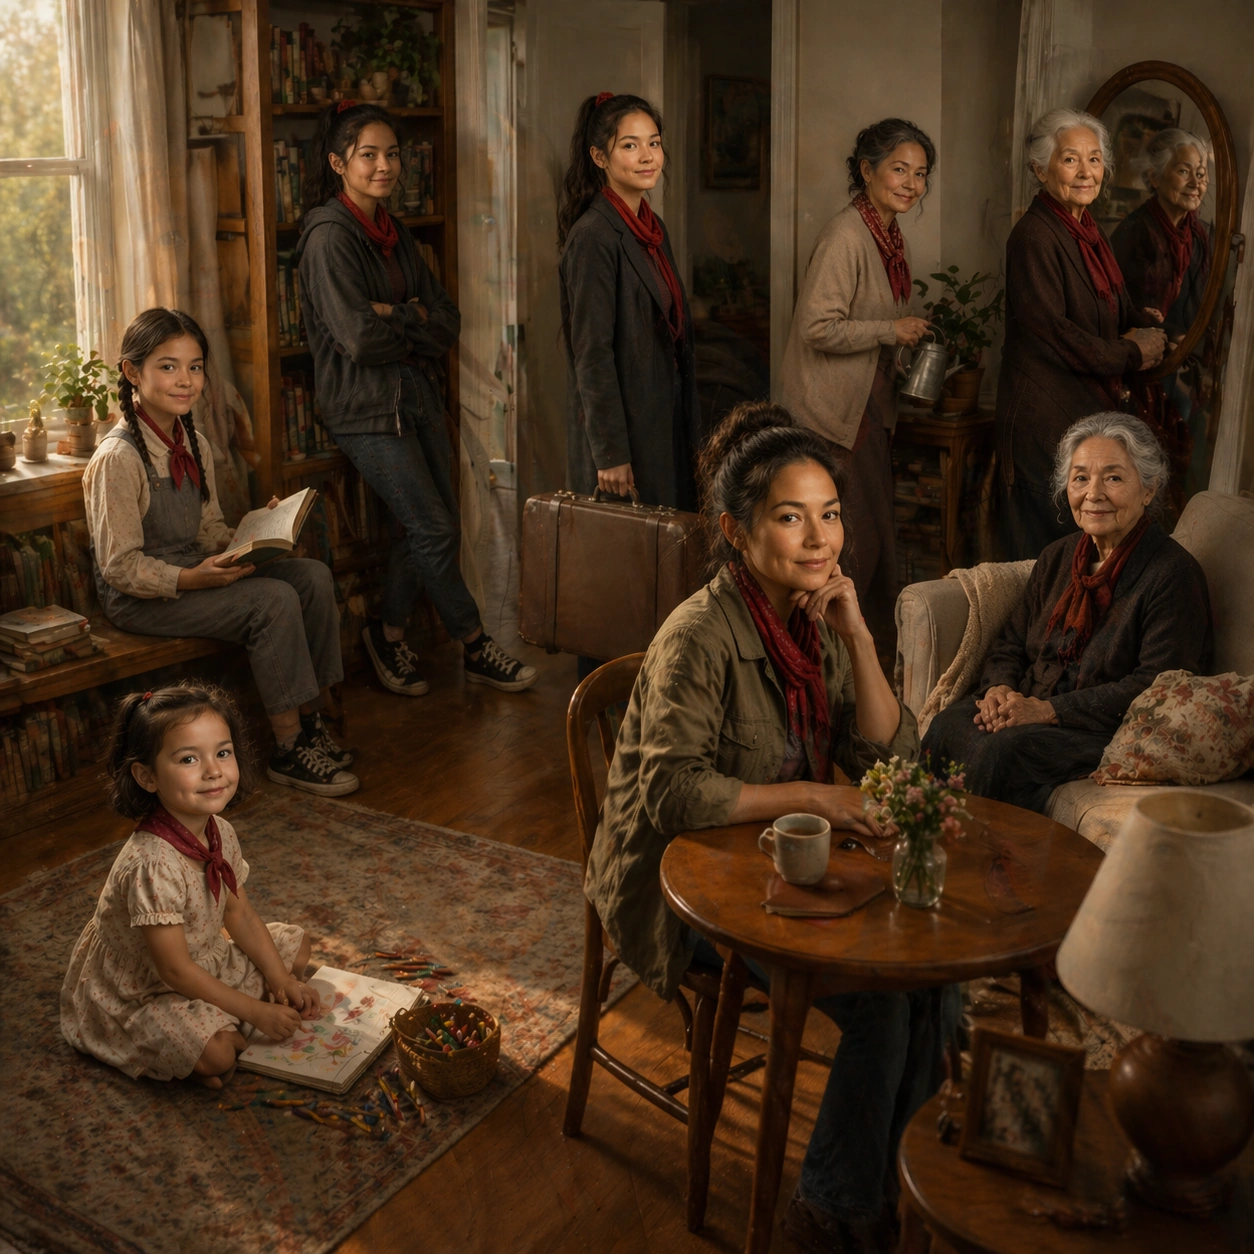
Show the same woman at eight life stages: small child, preteen, teenager, young adult, mid-career adult, older adult, elderly, and very elderly. Preserve identity through the same almond-shaped eyes, straight nose bridge, left cheek dimple, dark hair that gradually grays, and a small red scarf or scarf-like accessory repeated in age-appropriate ways. Clothing changes by decade, but posture, facial structure, and signature gaze stay clearly related.

Important details:
This reference must make age progression legible without turning the person into eight unrelated characters. Keep face proportions consistent, show natural aging, avoid glamour extremes, and make the red accessory a reliable identity anchor. Background, lighting, and crop should be consistent across all eight panels so later images can use the sheet as a stable multi-age reference.

Use case:
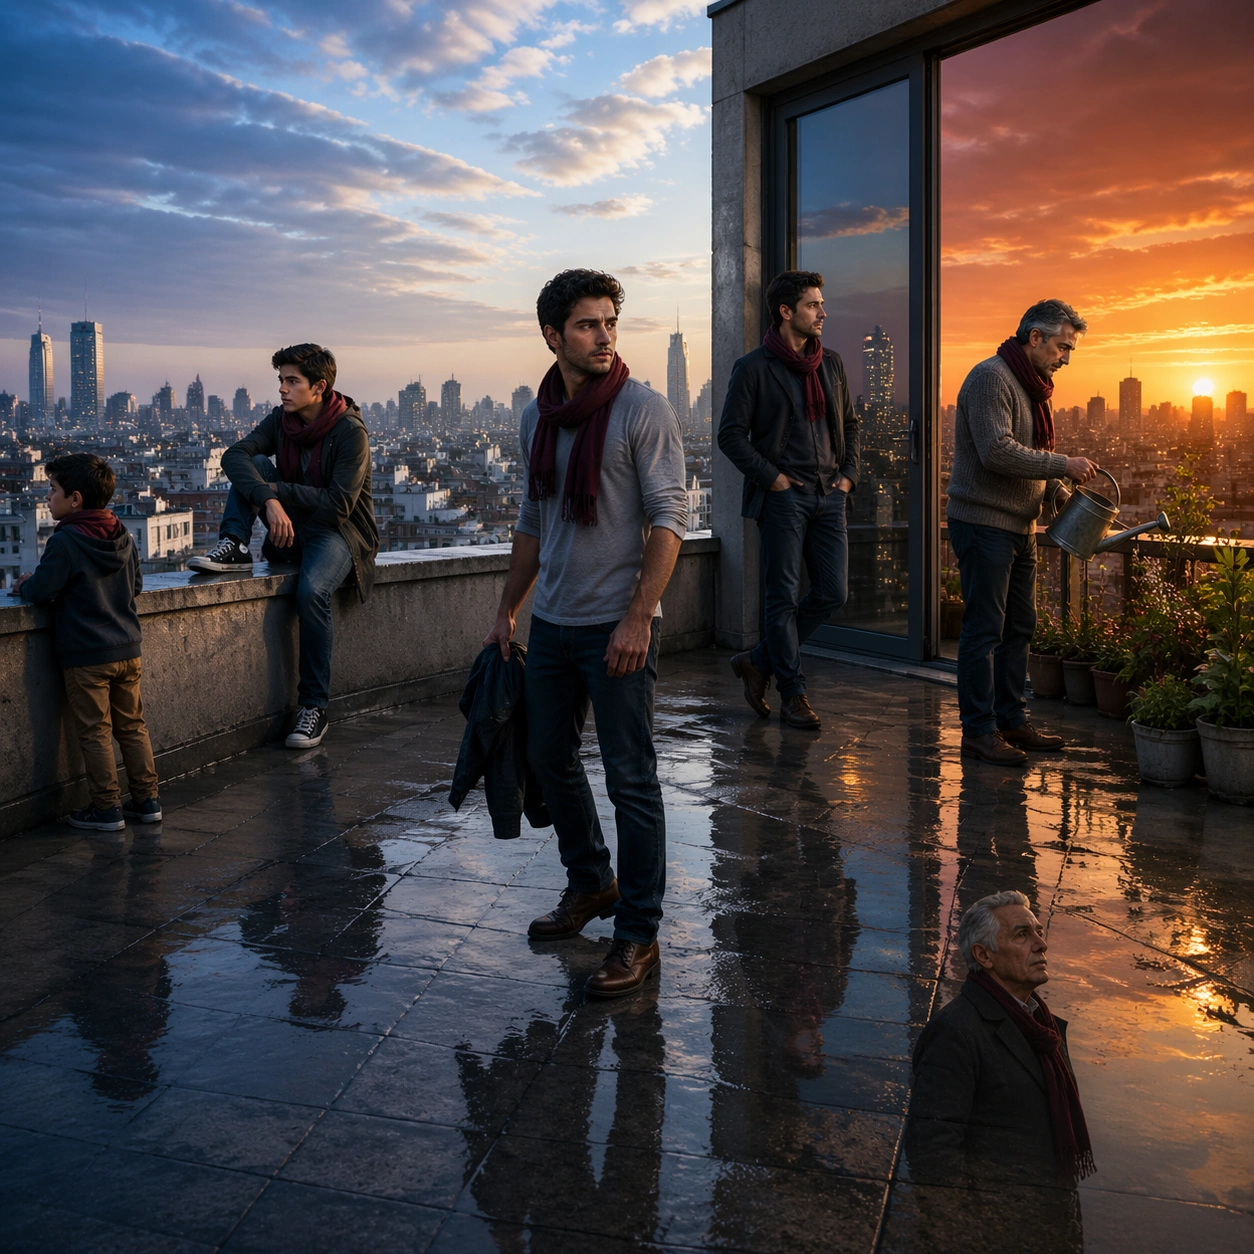
Mirror Worlds series study 1/8, establishing the protagonist identity across eight life stages for fanout compositions.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no celebrity likeness, no duplicate identical faces, no unrelated family members, no inconsistent eye color, no distorted hands, no decorative labels.
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.