Original document
GPT Image 2 · en
Scene:
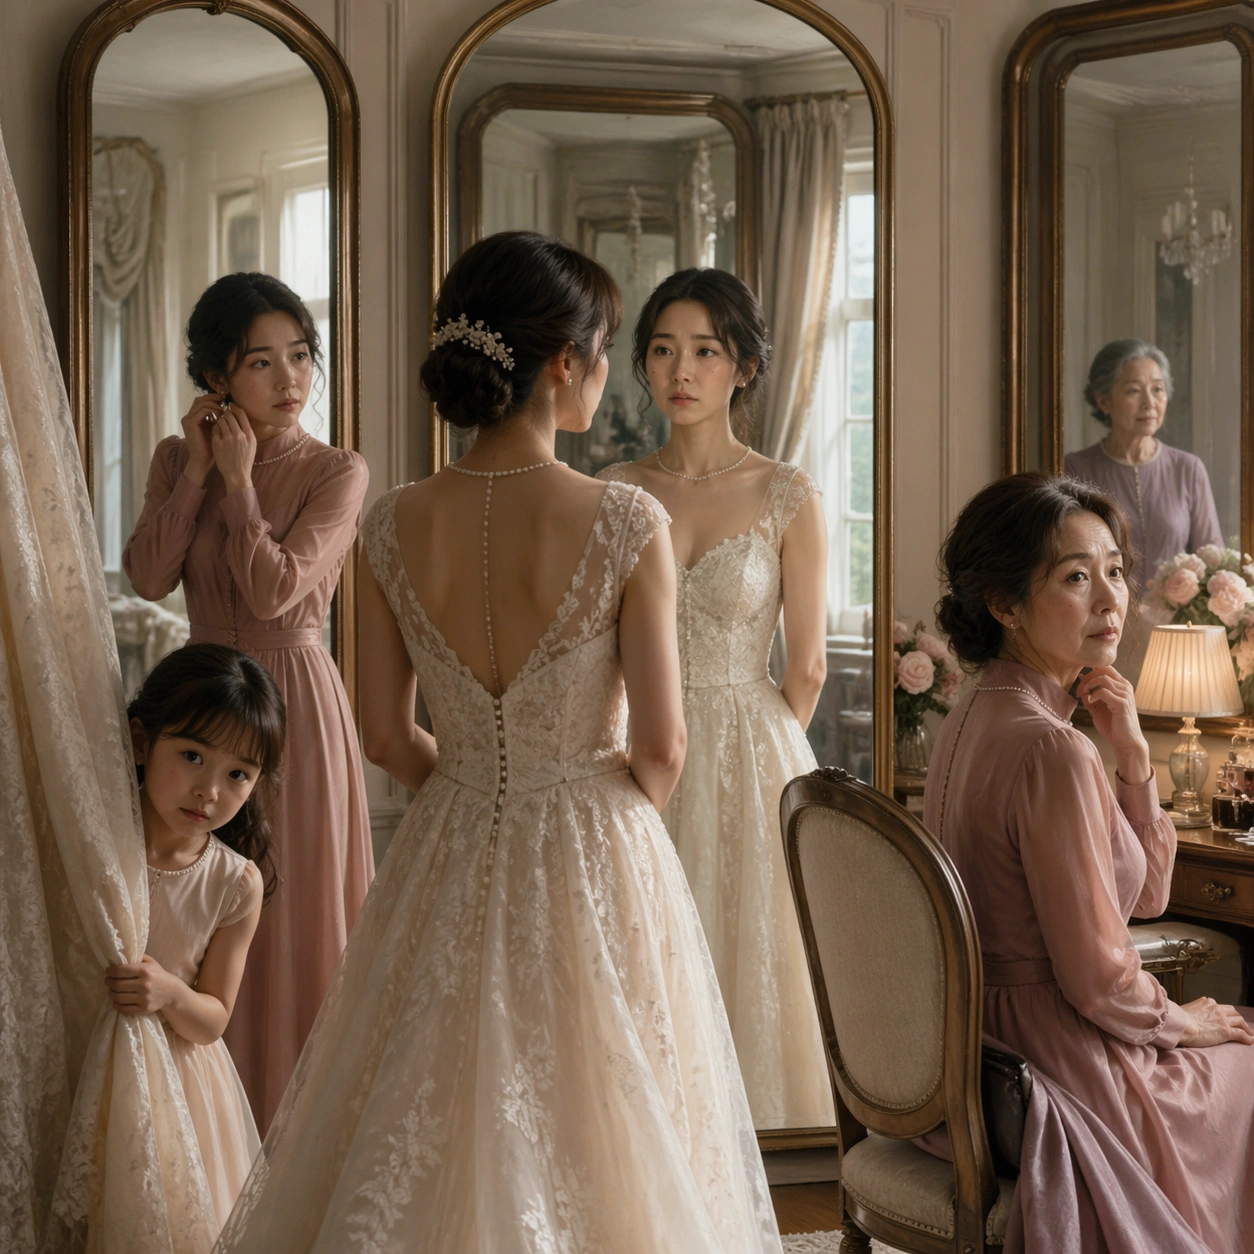
A square dressing room before a wedding, softly lit by large windows and surrounded by three tall mirrors. The palette is ivory, pale gold, muted rose, and deep walnut wood. The room is elegant but quiet, with chairs, fabric, a vanity, and a large central mirror creating nested reflections. No visible writing or brand details.

Subject:
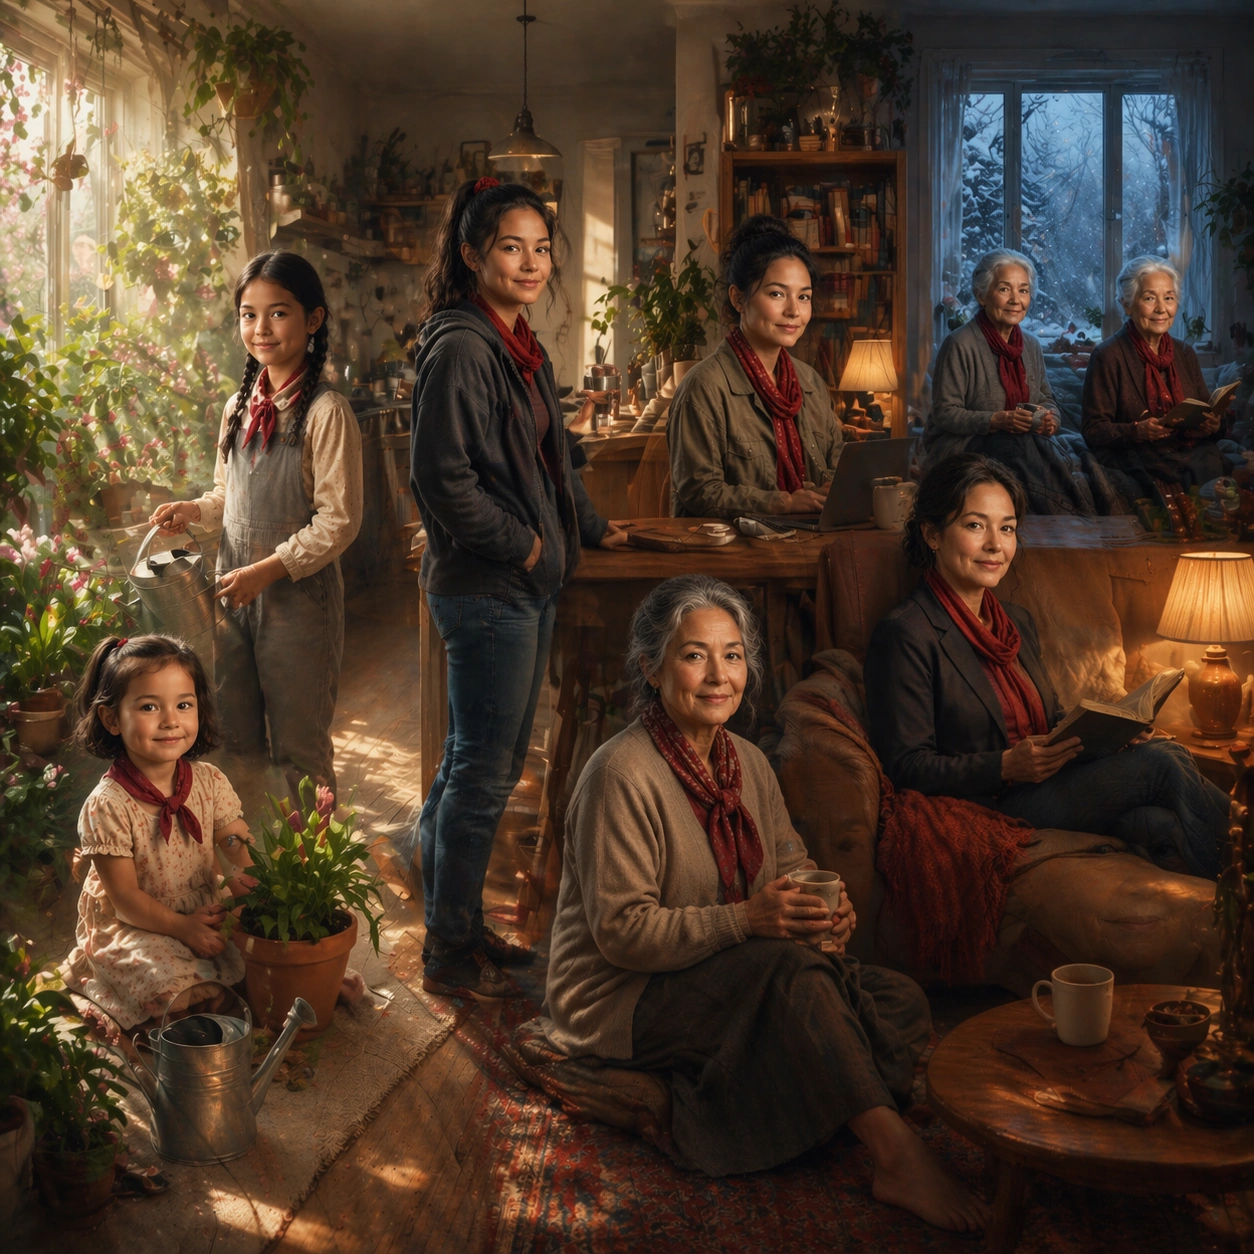
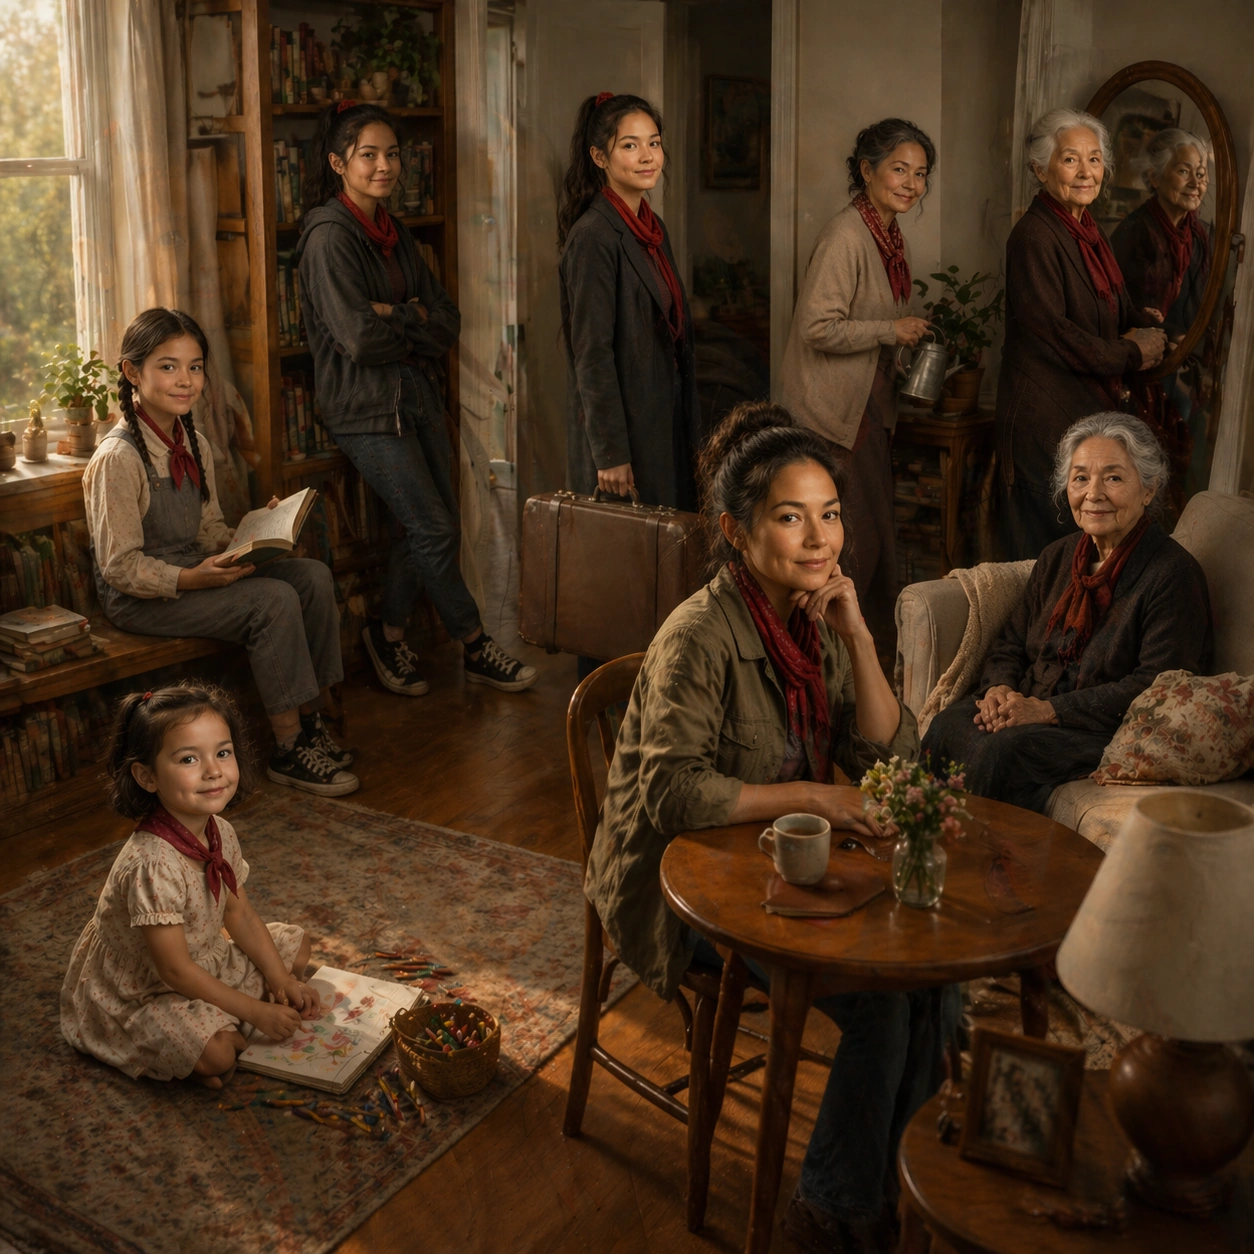
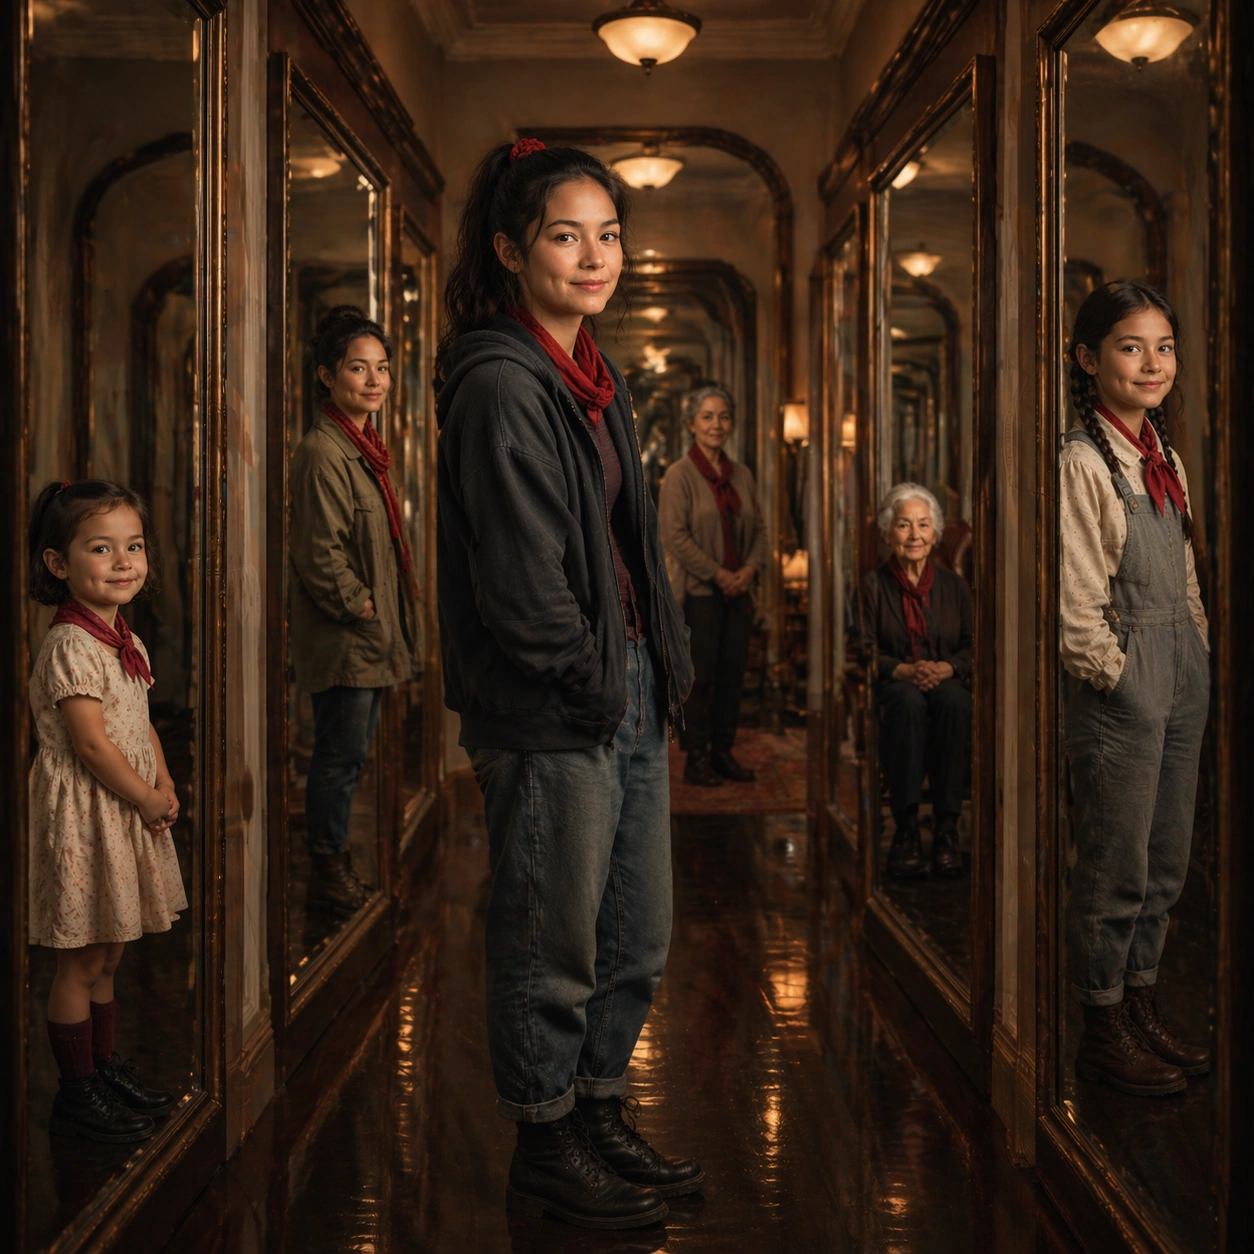
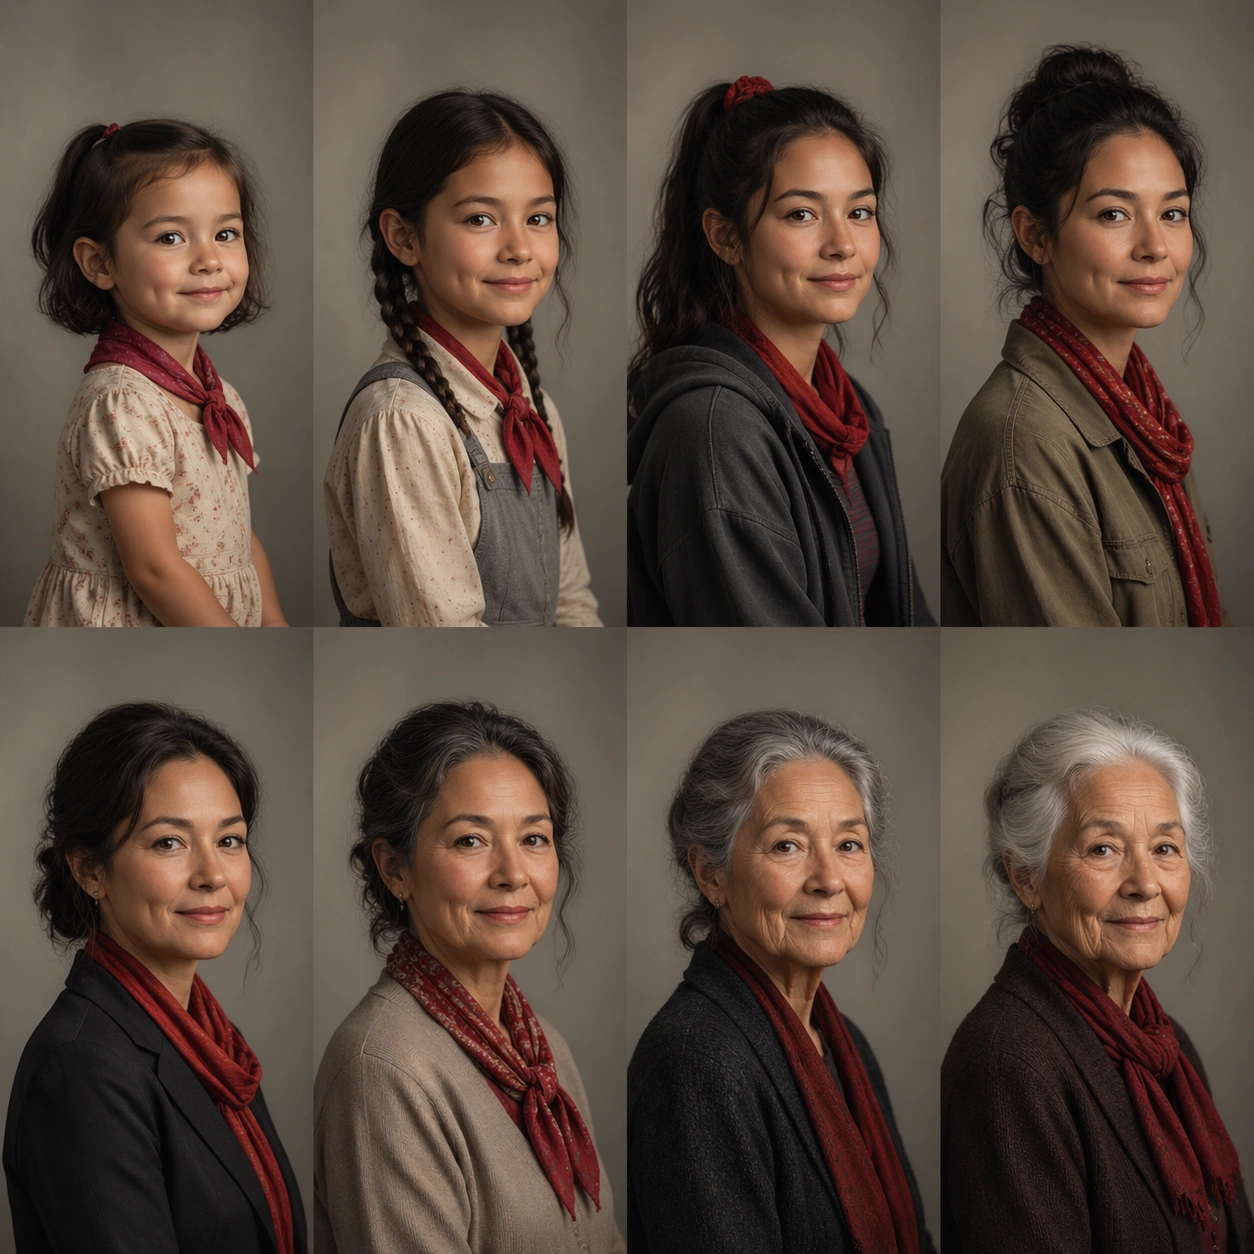
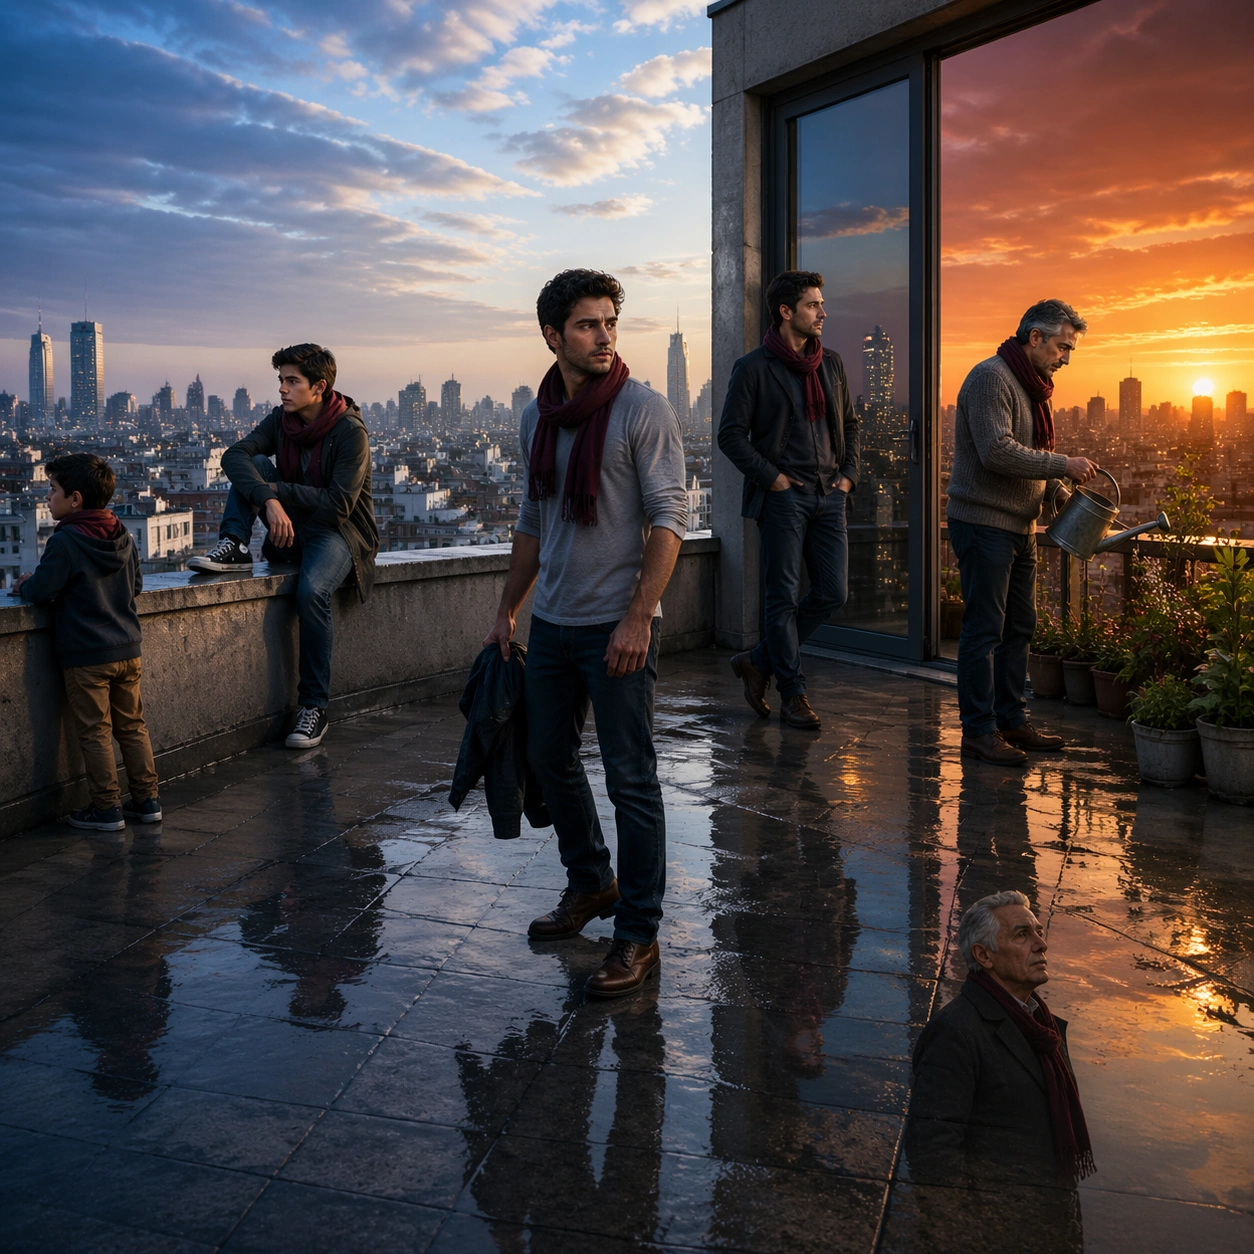
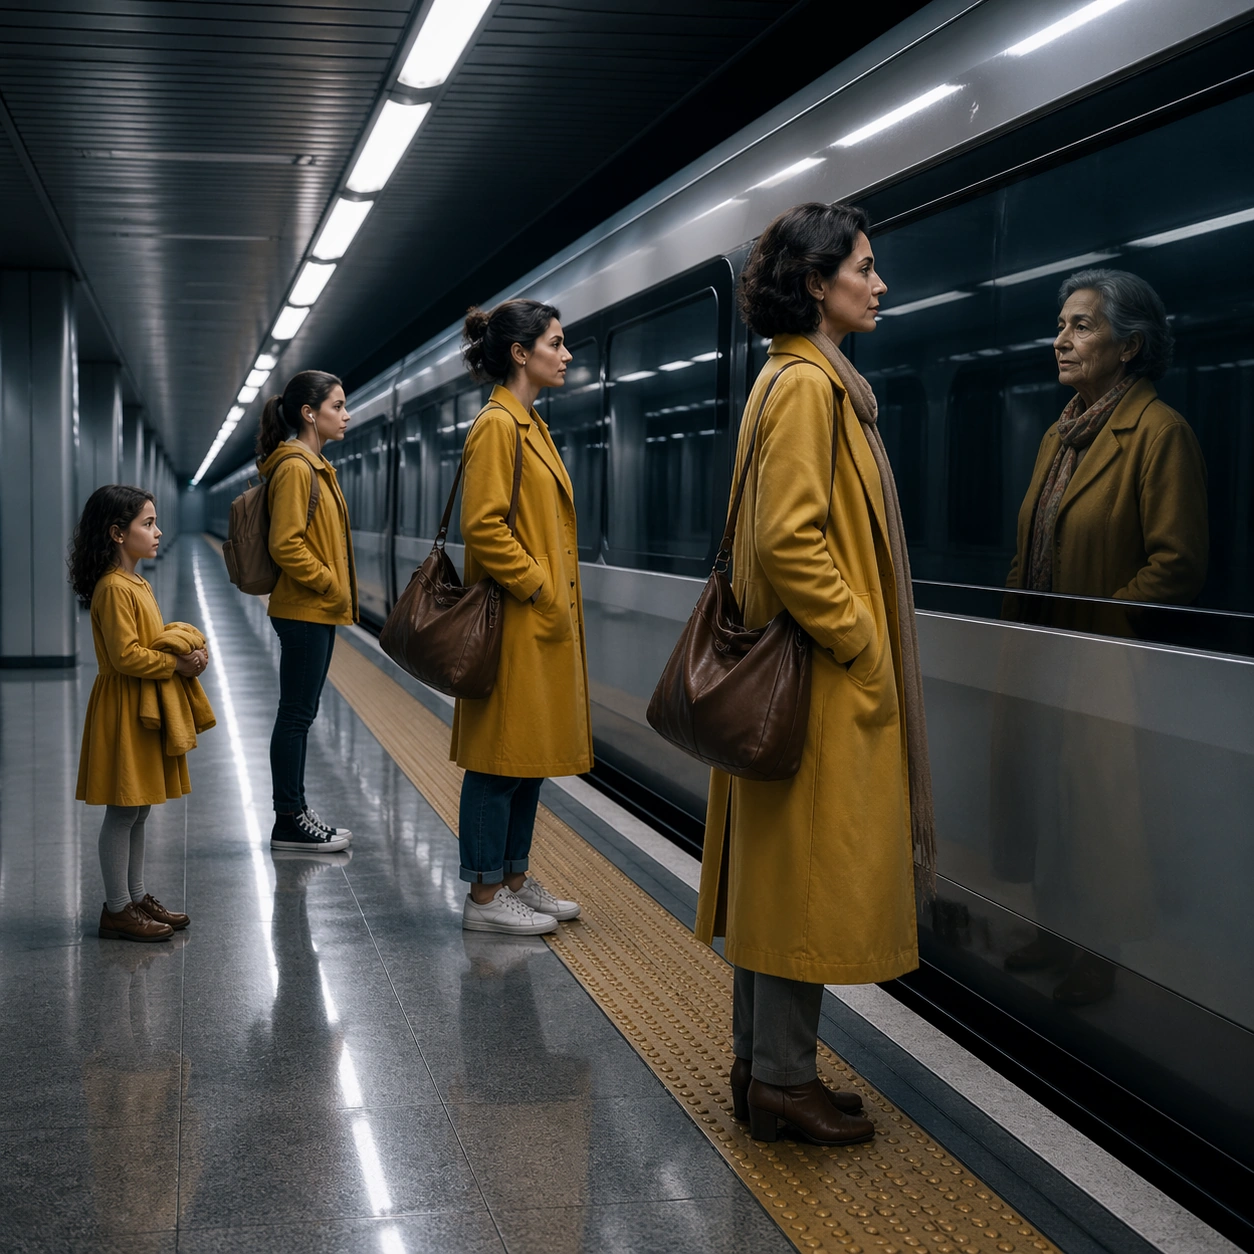
Show the same person across five emotional life moments in one dressing room: child version peeking from behind fabric, young adult adjusting formal clothing, present-day adult standing before the mirror, older adult seated by the vanity, and elderly version appearing in a far mirror reflection. Preserve identity through the same oval face, gentle downturned eyes, small mole above the lip, and pearl-like collar detail repeated in age-appropriate styling. Clothing can shift from simple childhood clothes to formal wedding attire and later elegant dresswear.

Important details:
The image should feel celebratory and uncanny, not sentimental clutter. Mirrors must show coherent angles and partial reflections, while each age stage remains readable. Maintain one consistent facial identity through age changes, with the mole and collar detail as anchors. Use light and gesture to connect the versions across the room.

Use case:
Mirror Worlds single study 7/8, testing a high-emotion life-stage mirror composition without reference images.

Constraints:
No readable text, no watermark, no logos, preserve exact 1:1 aspect ratio, no extra wedding guests, no celebrity likeness, no horror mirror effect, no inconsistent facial markers, no impossible reflection angles.
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.