
Original document
GPT Image 2 · en
Scene:
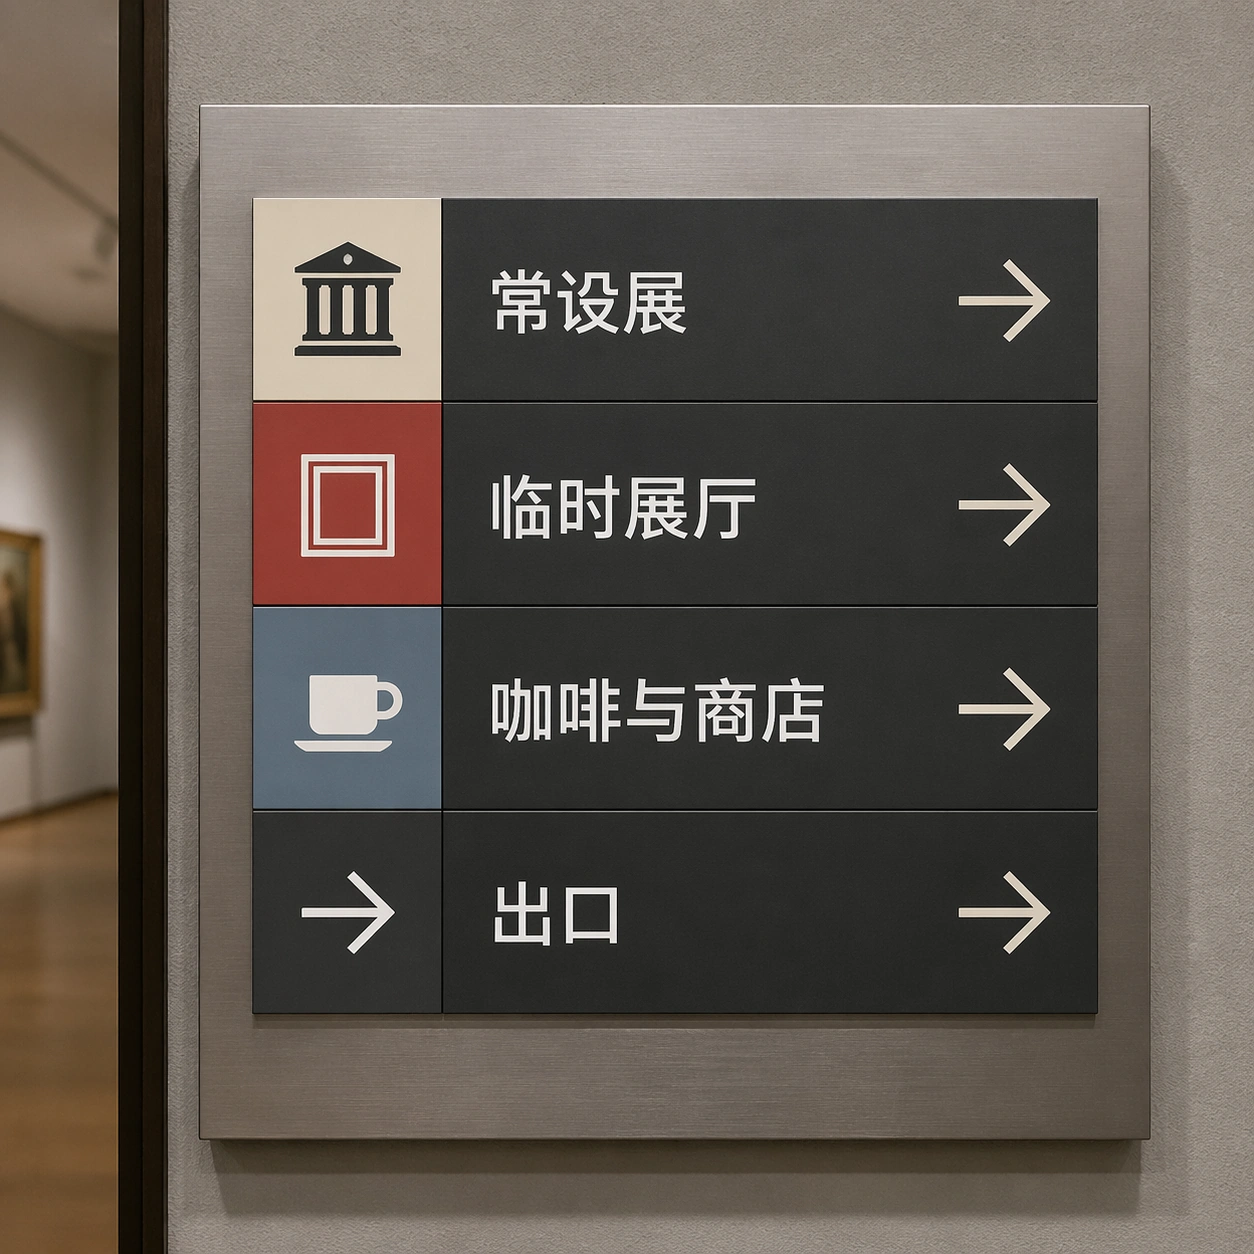
A square close-up of a museum wayfinding placard mounted on brushed aluminum beside a gallery doorway. The camera is straight-on with slight environmental depth at the edges, soft museum lighting, neutral gray walls, and a restrained institutional palette of charcoal, cream, muted red, and pale blue. The sign is divided into three perfectly aligned rows with icon columns and bilingual-looking spacing.

Subject:
Show a finished Chinese localization of an English museum sign while implying the original layout is preserved. The exact readable Chinese text must be: 常设展, 临时展厅, 咖啡与商店, 出口. Each phrase appears in a clean sans serif style, replacing where English labels would have been, beside simple pictograms for collection, gallery, cup, and arrow. The sign should look production ready, with exact baseline alignment and even optical margins.

Important details:
The point is not just multilingual text; it is text replacement inside a pre-existing wayfinding grid. Keep icon positions fixed, keep row heights equal, keep the arrows and pictograms crisp, and make all Chinese characters readable at thumbnail scale. The sign should show professional localization discipline: no crowding, no mismatched font weights, no accidental extra copy, and no redesign.

Use case:
In-Image Translation single study 5/8, testing translated signage text inside a strict wayfinding layout.

Constraints:
No readable text except the specified Chinese strings, no watermark, no logos, preserve exact 1:1 aspect ratio, no fake museum brand, no misshaped Chinese characters, no handwritten style, no perspective distortion, no extra labels.
How to use
- Copy the complete original prompt, including any parameters.
- Replace the subject, text and composition with your own requirements.
- Use a compatible external tool; check its current access conditions and review the result.
Before you start
- Check whether a reference image is required. A compatible model label does not mean this example was generated with that model.
- Keep names, figures and visible text accurate; results can vary between model versions.