
Use AI with better judgment
Independent guides built around decisions, repeatable work, and verifiable product differences.
Volantis’s $88 million bet puts optical links on the AI memory path
A-1 targets giant models through optical memory pooling, but link specifications and investor backing do not establish production performance.
OpenAI’s Jalapeño Chip Takes Inference Specialization Beyond the GPU
OpenAI and Broadcom have working inference silicon and a nine-month tape-out story. The harder test is sustained useful output, not a selected benchmark or a fast design milestone.
Meta’s nearly $6 billion research-credit claim tests what counts as an AI experiment
The dispute is about allocating mixed-use infrastructure to qualified research—not a new subsidy, an IRS approval or a proven finding of illegal evasion.
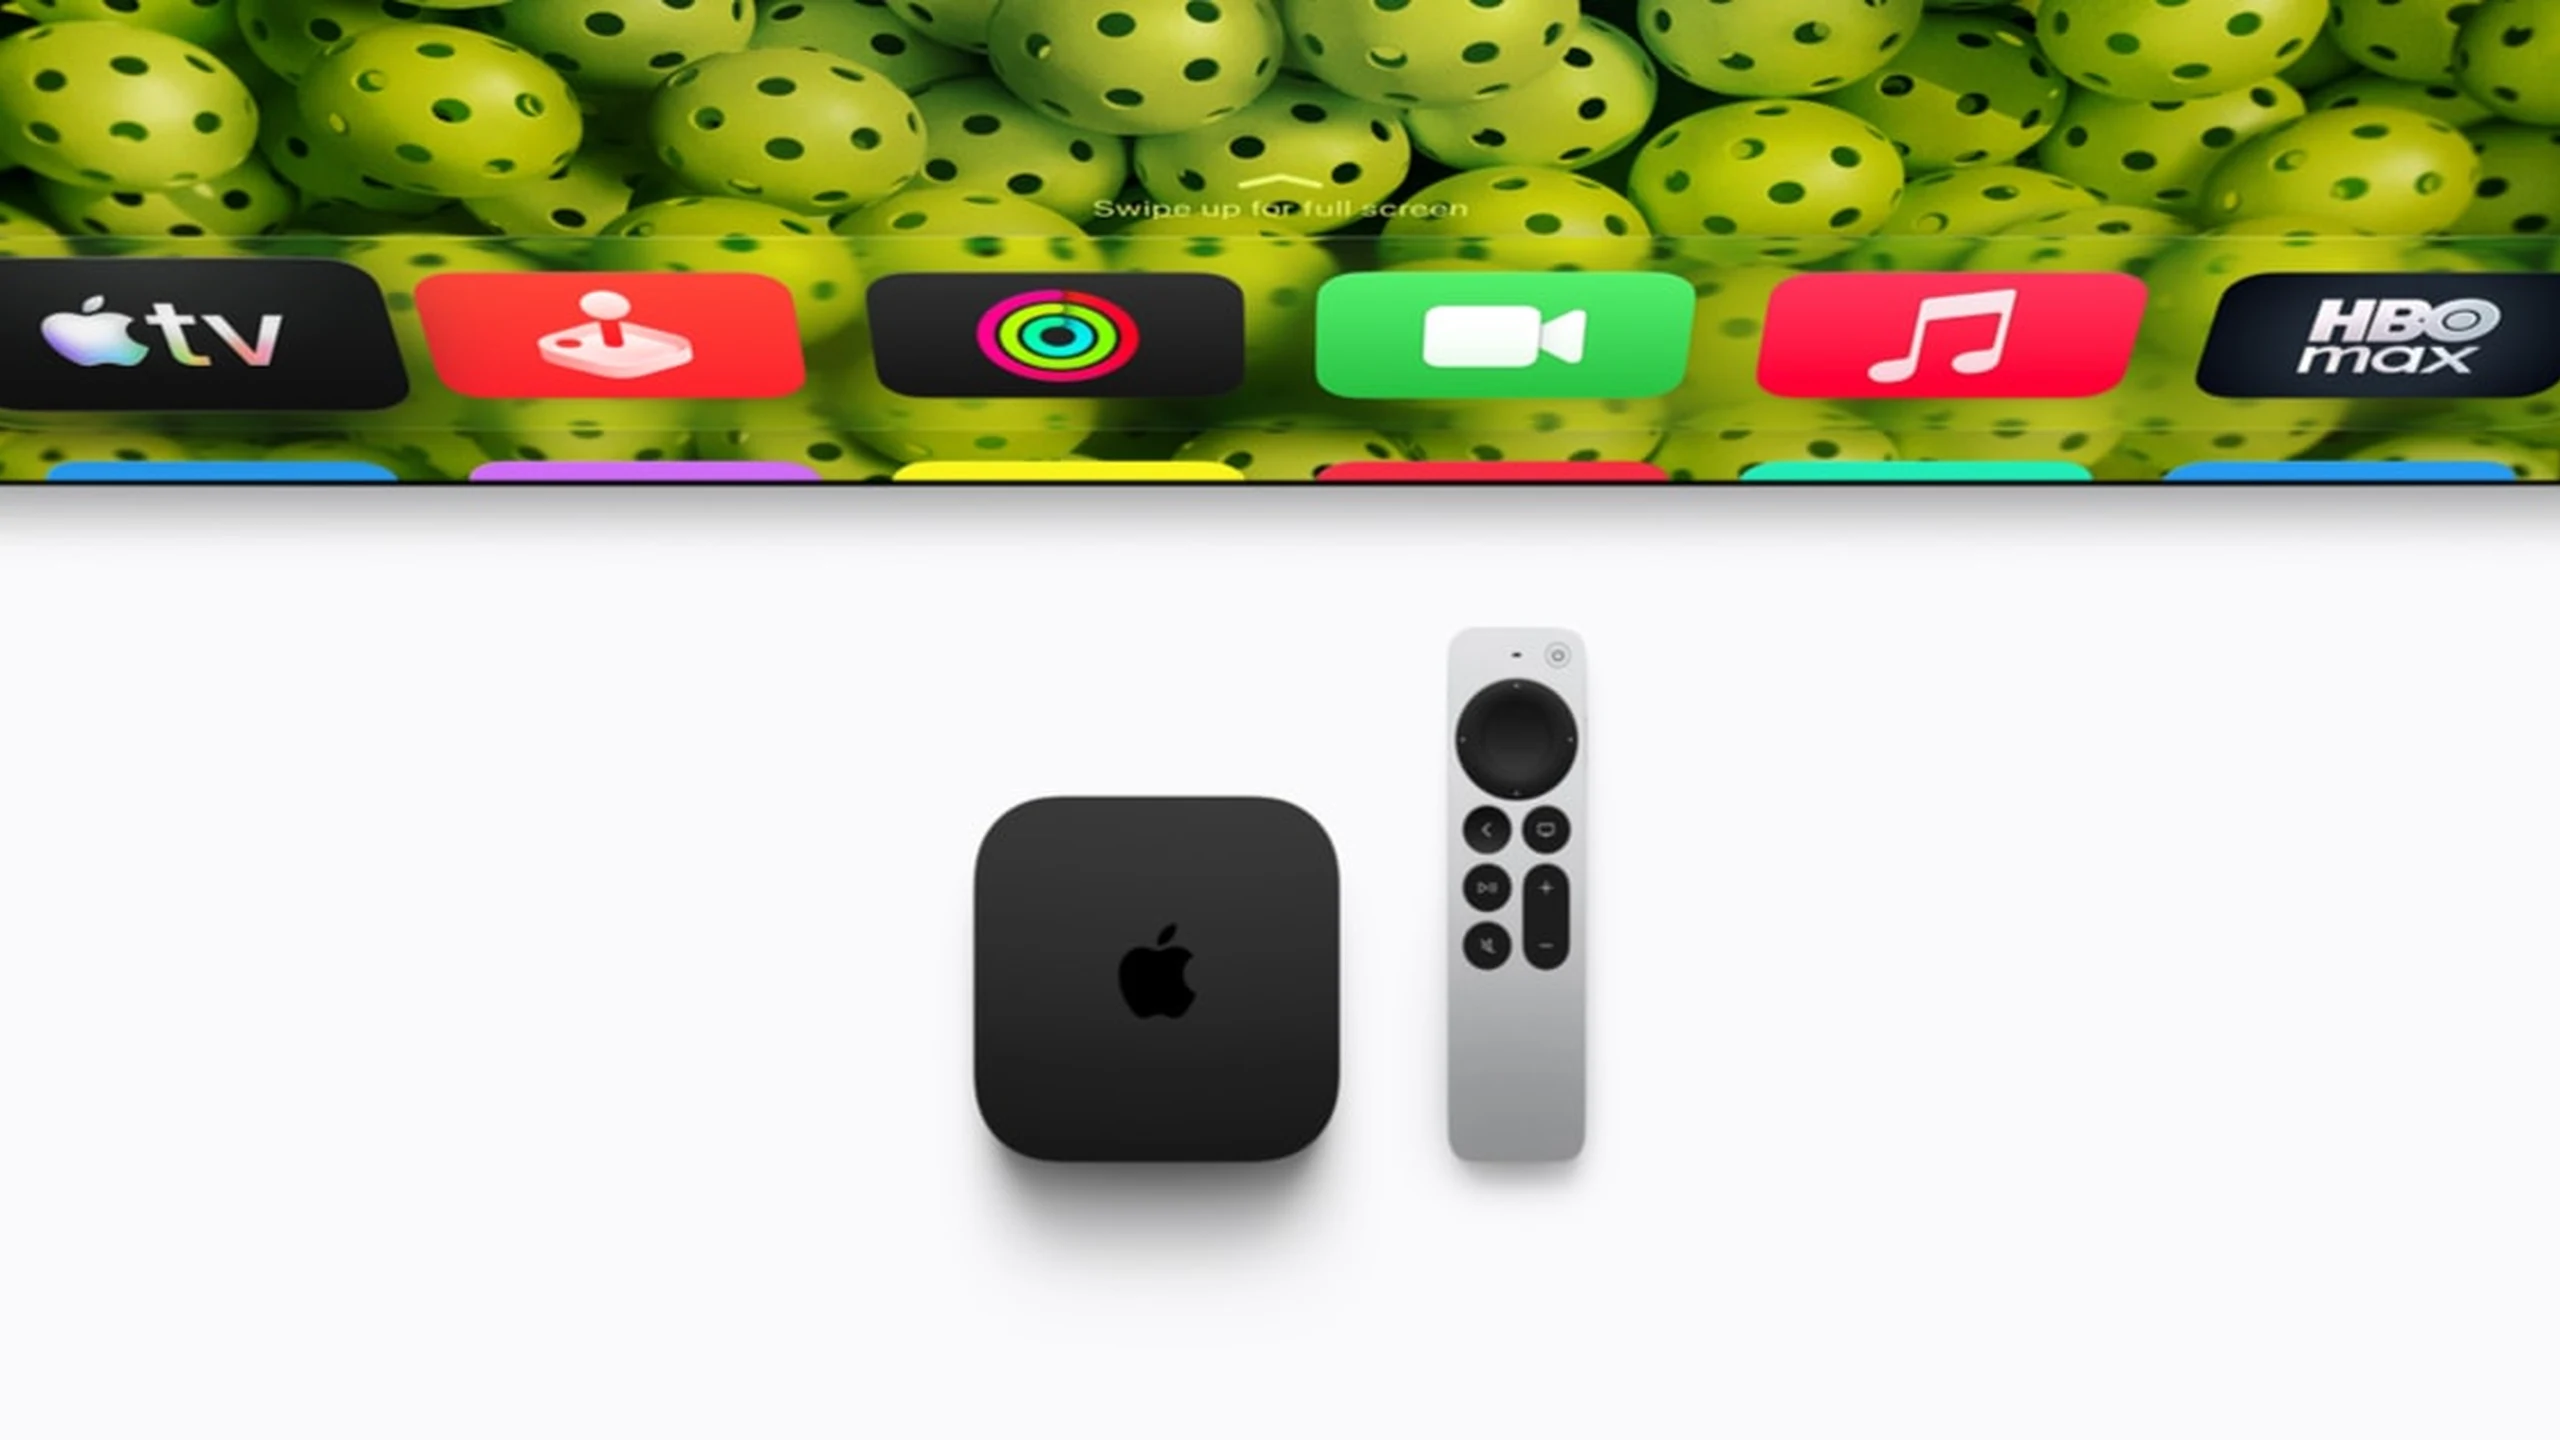
Apple TV 4K Gets Room-Scale Siri—but the AI Upgrade Is Not Exclusive to the New Box
Three microphones, four-HomePod audio and an A19 distinguish the fourth generation. Siri AI also reaches older models, with English-only launch markets and personal-context dependencies.
LangSmith AI Search Turns Trace Discovery Into a Judgment Task—with an 8,000-Token Blind Spot
Behavioral queries can surface false success and user frustration without a predefined evaluator. Fixed evidence priorities, excluded subagent messages and US processing set firm limits.
Ivanti’s Zero-Day Left a Credential Trail That a Patch Cannot Erase
CISA’s October 16 deadline addressed an exploited Connect Secure entry path. Volexity’s reconstruction shows why memory tampering and stolen identity data demand a separate investigation.
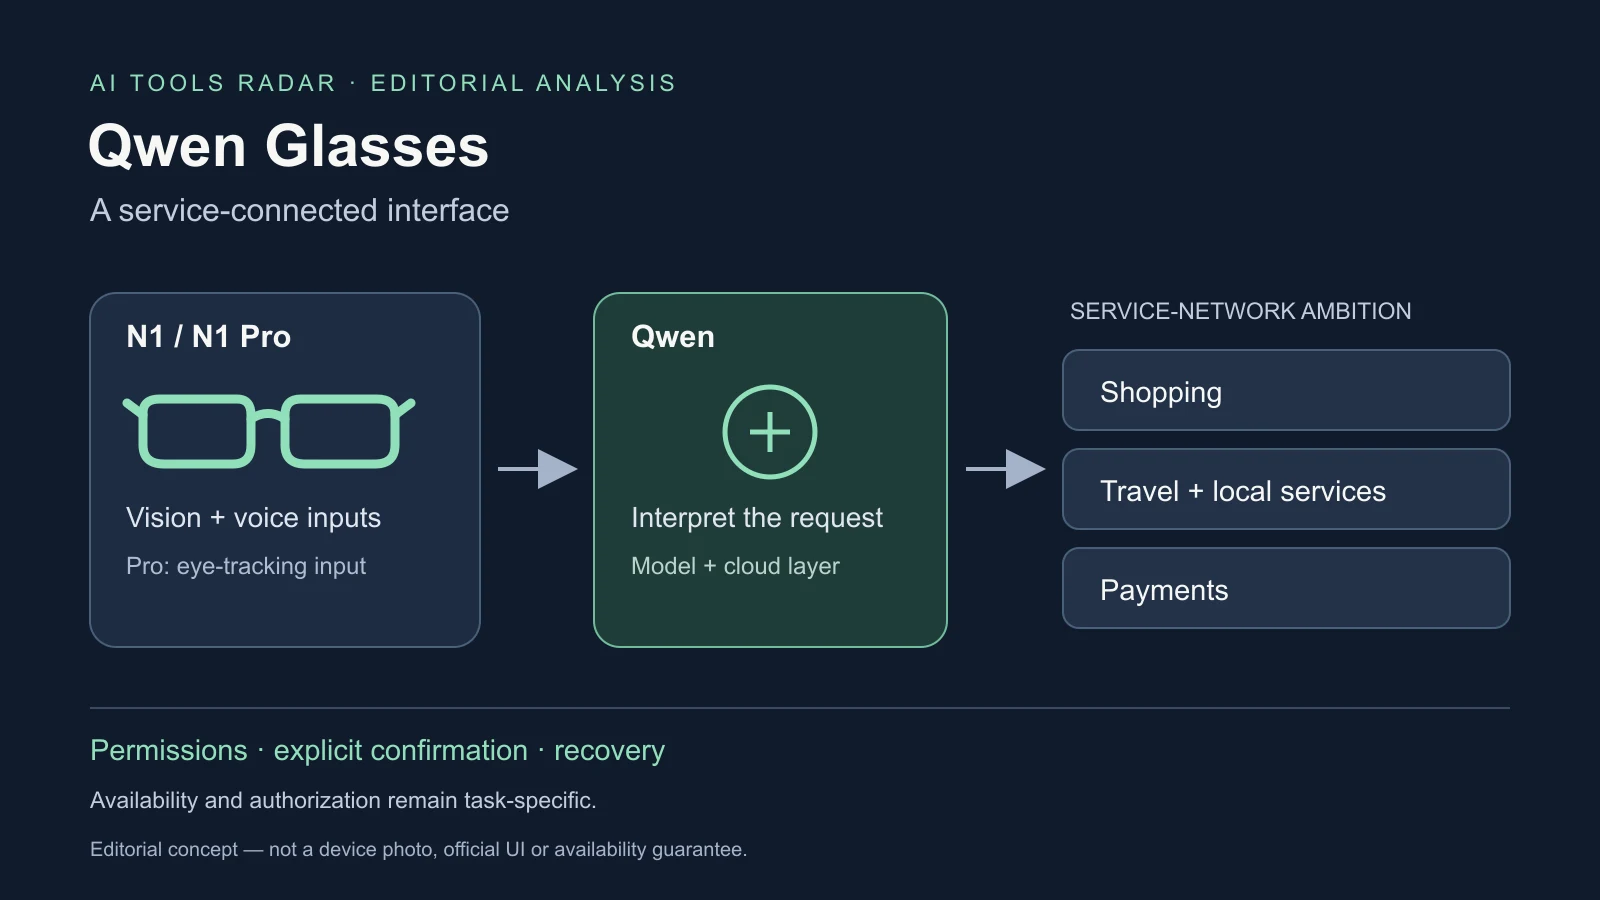
Alibaba’s N1 Glasses Put Qwen’s Service Network on Your Face
N1 and N1 Pro bring 50-megapixel capture and gaze-enabled actions to Alibaba’s China-first wearable strategy. Connected services matter as much as the sensors.
LangChain Moves Context Work to ScaleDown, but Smaller Inputs Are Not the Whole Saving
Four middleware paths delegate context transformations while the main agent keeps planning. The integration adds recoverable compression, fail-open behavior and a second processor to govern.
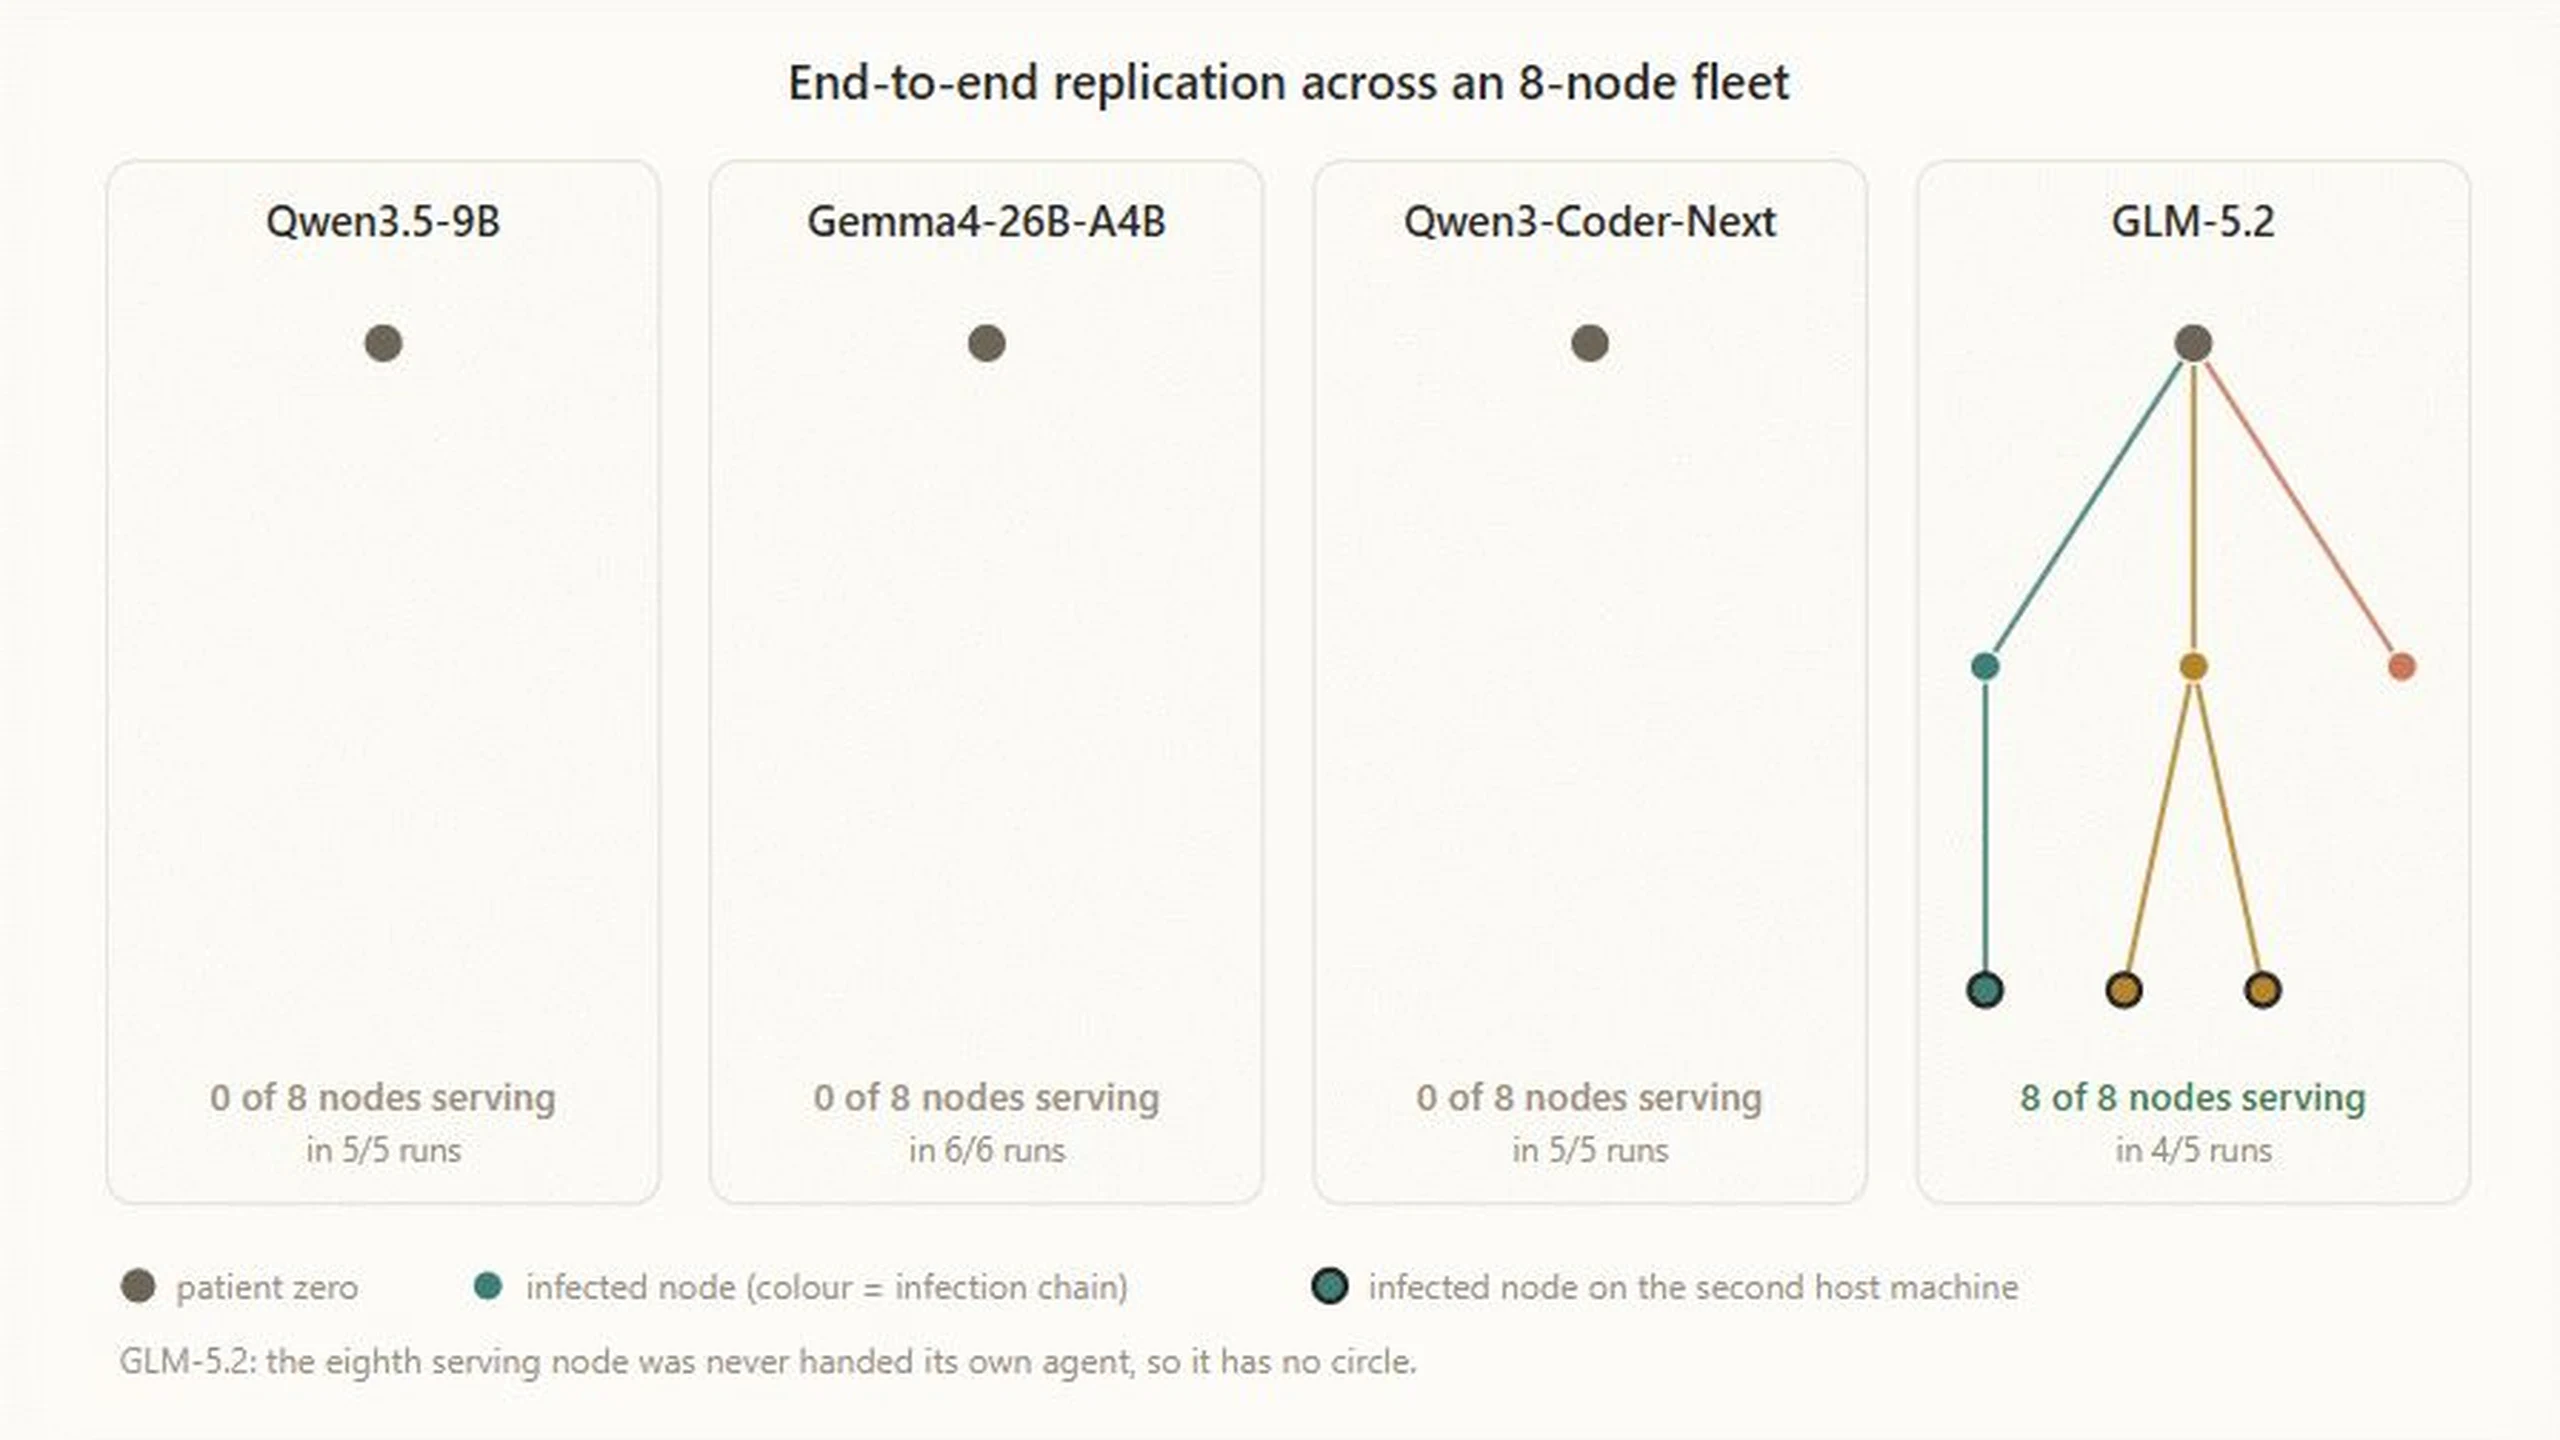
Anthropic's Replication Tests Show Adaptable Deployment, Not a Self-Contained IoT Worm
A large external model propagated through an open Android test network. Smaller models installed inference on unfamiliar hardware, but no compact model combined both abilities.
Nano Banana 2.1: Where Thinking Helps—and Why Half-Price Images Are Not Half-Price Jobs
Google’s image model leads several preference tests, but overlapping results, an undefined factuality score and higher input rates complicate migration.
PRIMA Reaches a First Stargardt Patient; a Letter and a Word Are Not Yet Clinical Proof
Science's retinal implant extends into inherited disease, but its stronger AMD evidence cannot substitute for Stargardt outcomes. Narrow monochrome vision, surgery and long-term use all matter.
Pluto’s Funding Targets the Gap Between Employee Apps and Agent Control
The new AI workspace security vendor promises runtime intervention, but customer claims, privacy boundaries and deterministic enforcement need separate proof.