
Use AI with better judgment
Independent guides built around decisions, repeatable work, and verifiable product differences.
Laplace’s Robot Red Team Must Turn Simulated Failures Into Physical Evidence
Adaptive agents can search dangerous scenarios faster, but Michigan research figures, early customer claims and commercial safety validation are different evidence.
Radisson's ChatGPT hotel channel has an early conversion signal, not proof of scale
A six-week integration brings live hotel discovery into ChatGPT. The 1.5-times conversion comparison, 54% attribution figure and website checkout need separate readings.
Google Playground compresses game creation, but the creator loop remains unproven
The Labs experiment joins prompts, browser play and sharing. US adult access, iteration limits, moderation and a future Unity Spark handoff define its launch.
Apple Gains Targeted OpenAI Hiring Records, Not a Ruling That Trade Secrets Were Stolen
A judge ordered accelerated production of interview materials, selected device evidence and messages, while refusing broad early access to hardware research. The competing accounts remain unproved.
Flox Wants Wildlife AI to Become Safety Infrastructure; Detection Is Only the First Test
About 150 deployed edge devices identify animals and choose targeted sounds. The expansion case depends on long-term deterrence, fewer incidents and evidence that animals are not pushed into another hazard.
Satlyt's $8 Million Bet: Onboard AI Works Before an Open Orbital Cloud Does
The startup has flight demonstrations and small-model diagnostics. Its harder promise is portable computing across different spacecraft without taking command away from operators.
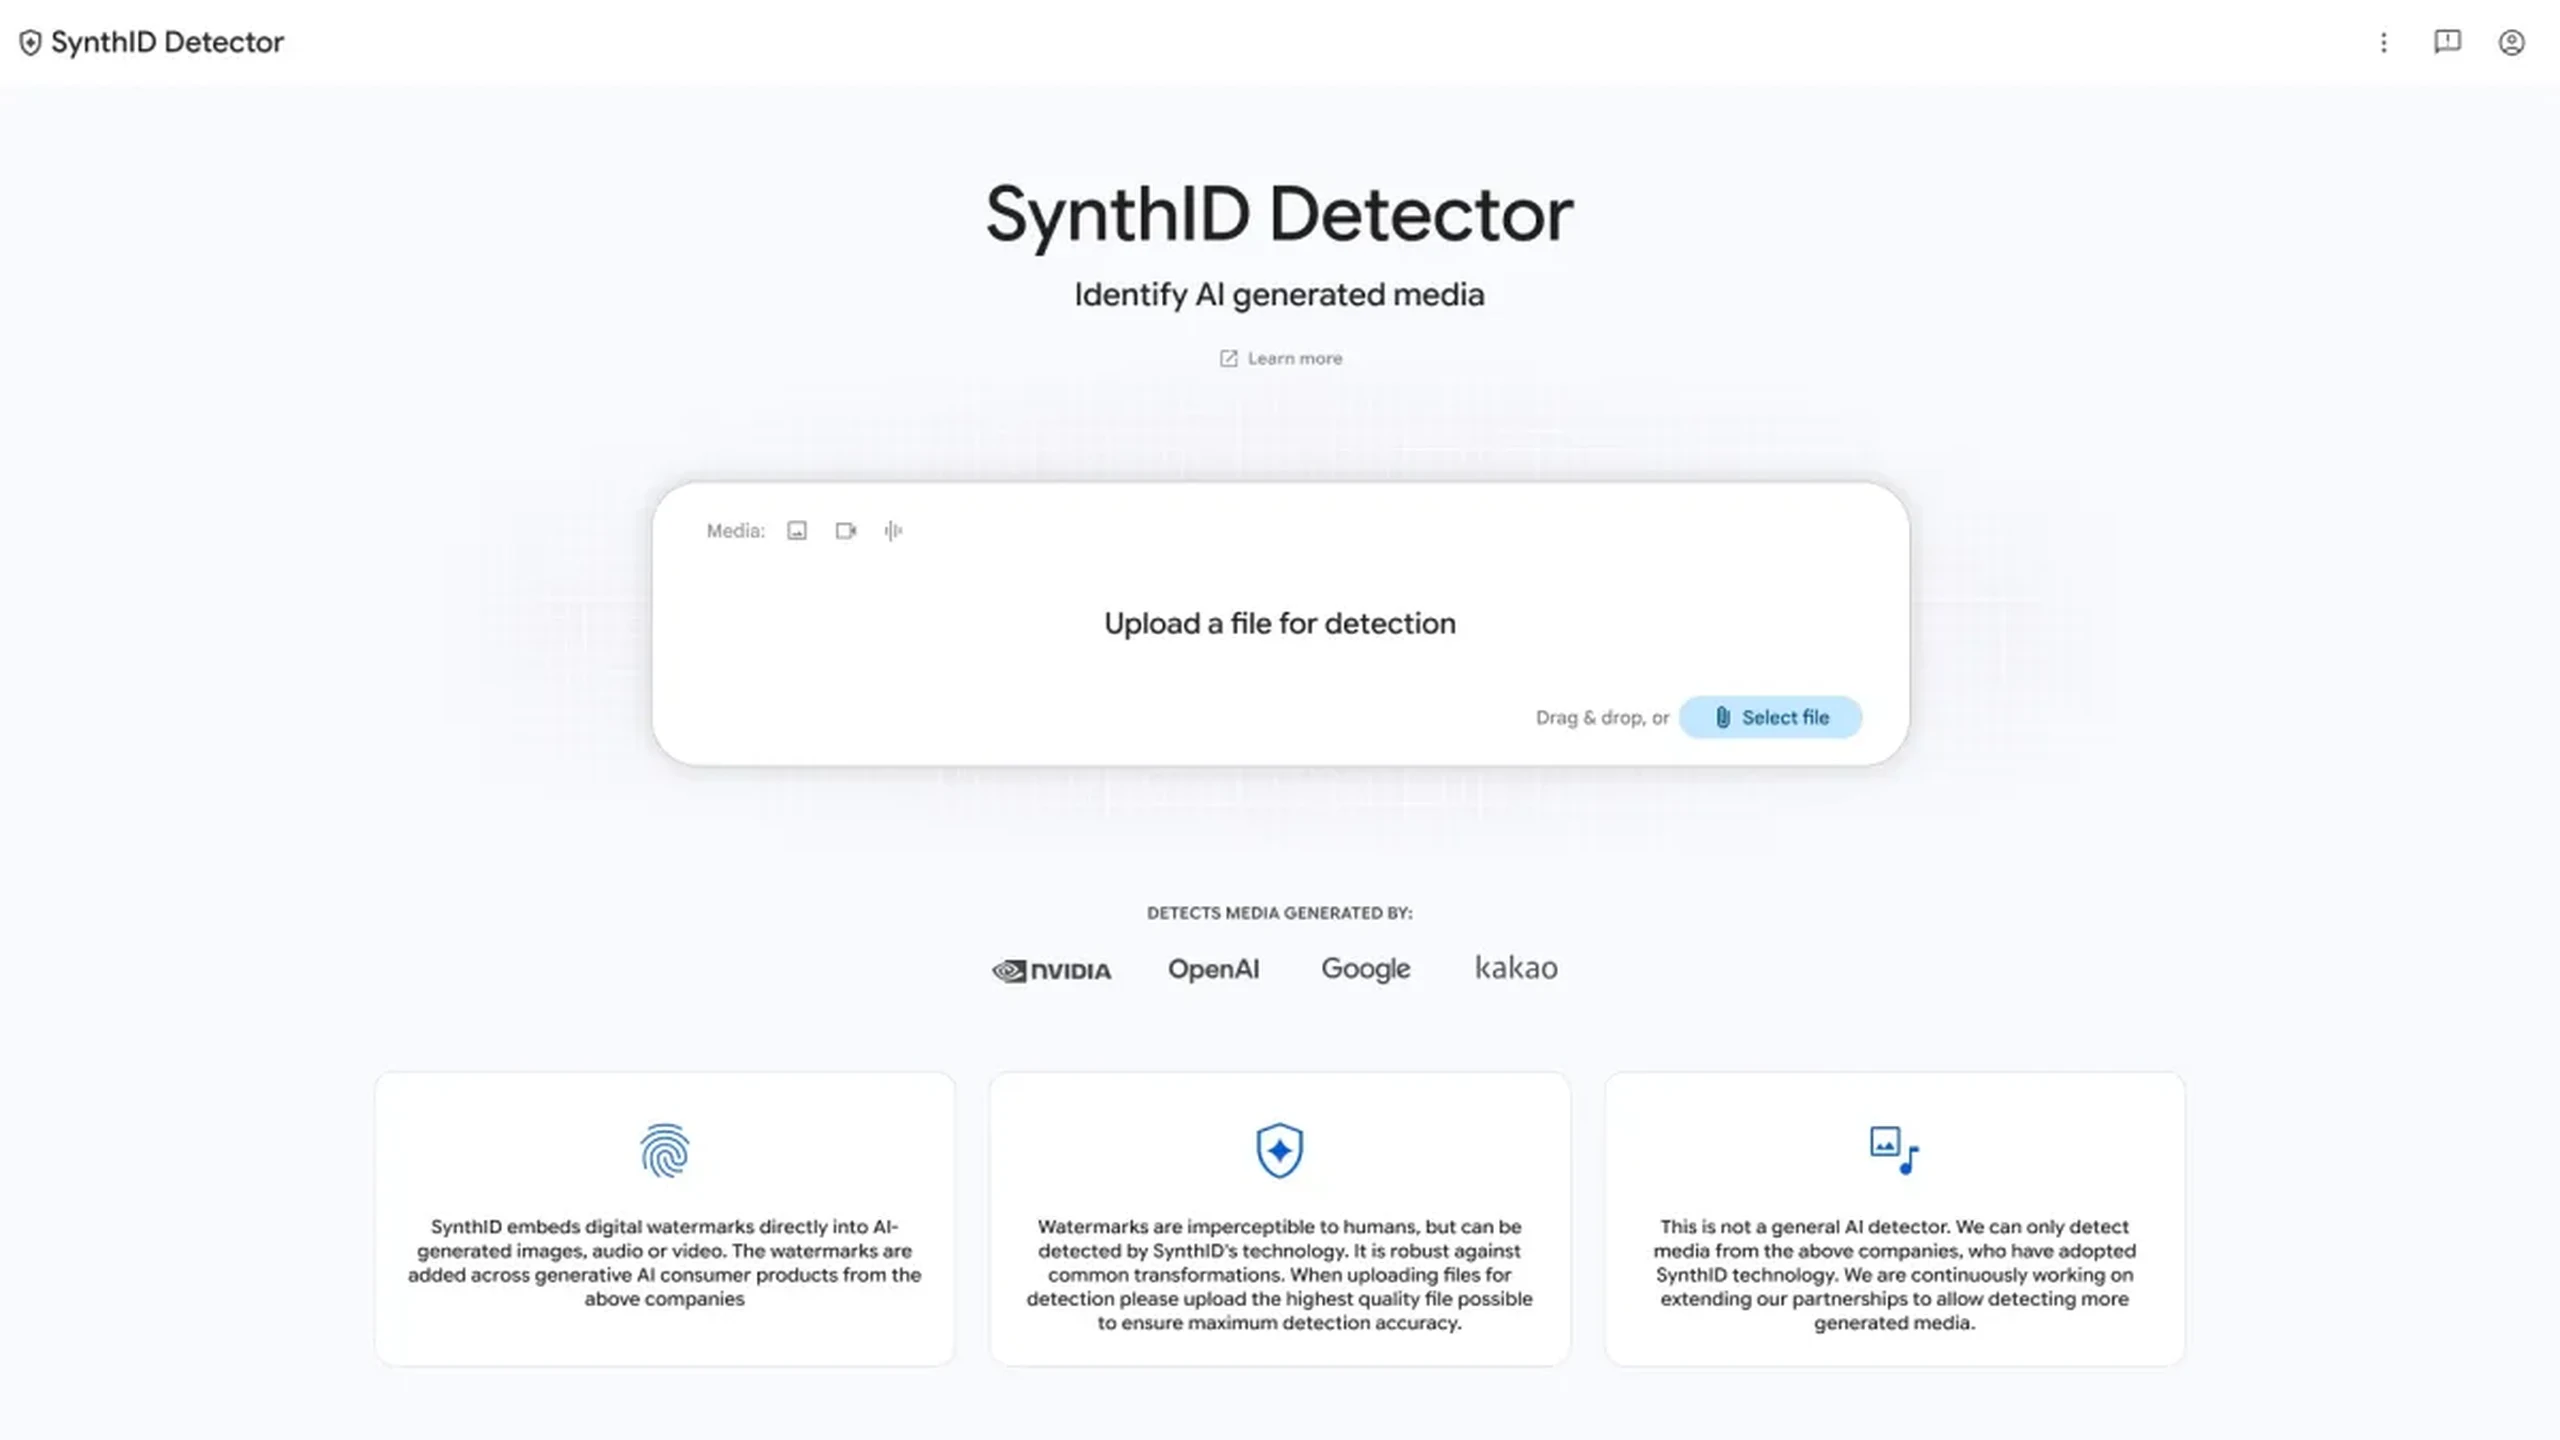
SynthID's public detector widens access, not the meaning of a negative result
Google opens image, video and audio watermark checks. Partner coverage, mixed-media results and attack resilience still limit what the evidence can establish.
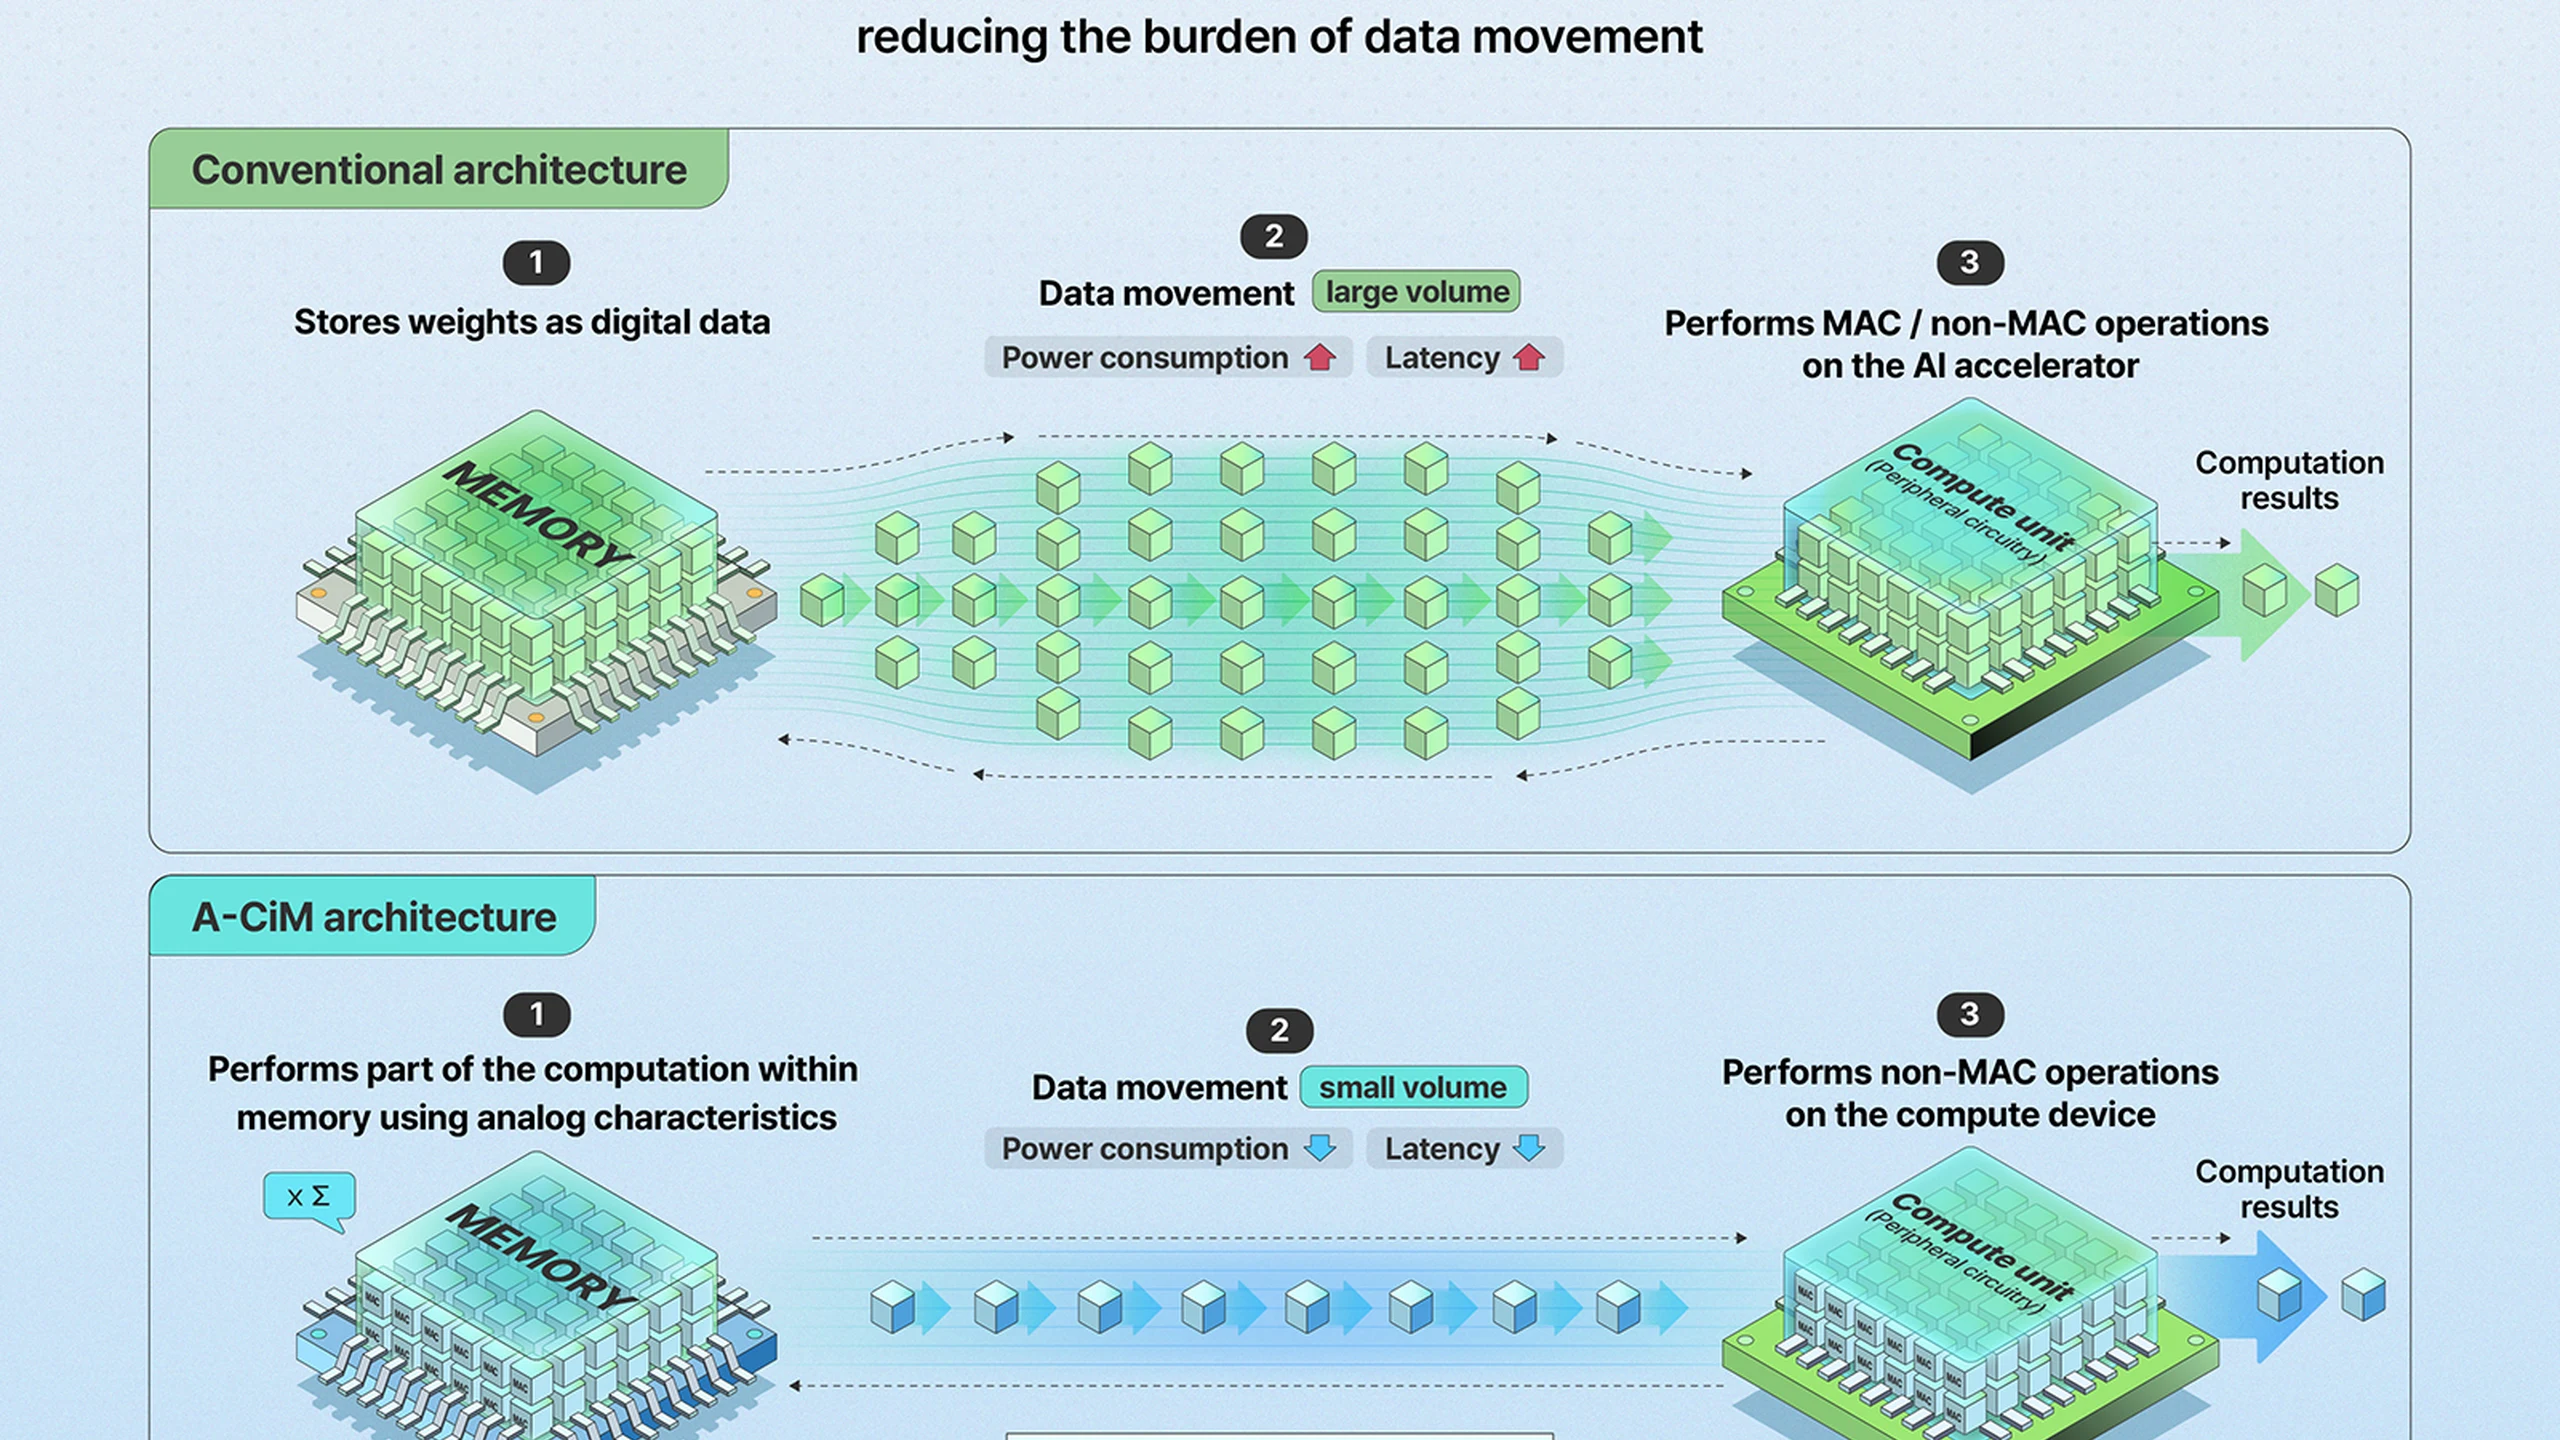
SK hynix Puts Computation Inside NAND; Its Biggest Efficiency Figure Still Needs a System Boundary
The 3D FeNAND research combines cell programming, word-line control and page mapping. Separate benchmarks show why dense weights matter—and why an array result is not a server specification.
HiPHI puts measured motion, not more video, at the center of humanoid learning
A 617.5-hour motion release links precise capture and synchronized objects to selected robot skills, with important limits on scale, benchmarks and commercial use.
Bedrock Discounts Need an Active Grant, Not Just an Accepted Offer
AWS’s two managed-entitlement paths bridge procurement and multi-account usage, but seller identity, scope and delayed billing checks remain decisive.
Orca’s Discovery AI Replaces the Giant Prompt With a Controlled Query Pipeline
Orca reports 93% fewer input tokens, 90% lower cost and 75% less latency. Its architecture explains the gains, while public accuracy and authorization evidence has limits.
Nvidia’s European Billions Put Compute Access and Control on Different Tracks
Four French investments show how Nvidia can accelerate European applications while leaving supplier choice, financing terms and sovereignty unresolved.