
The signal with receipts
Important AI developments, reported from primary sources and separated from product marketing. Facts are mapped to evidence; analysis is labeled as judgment.
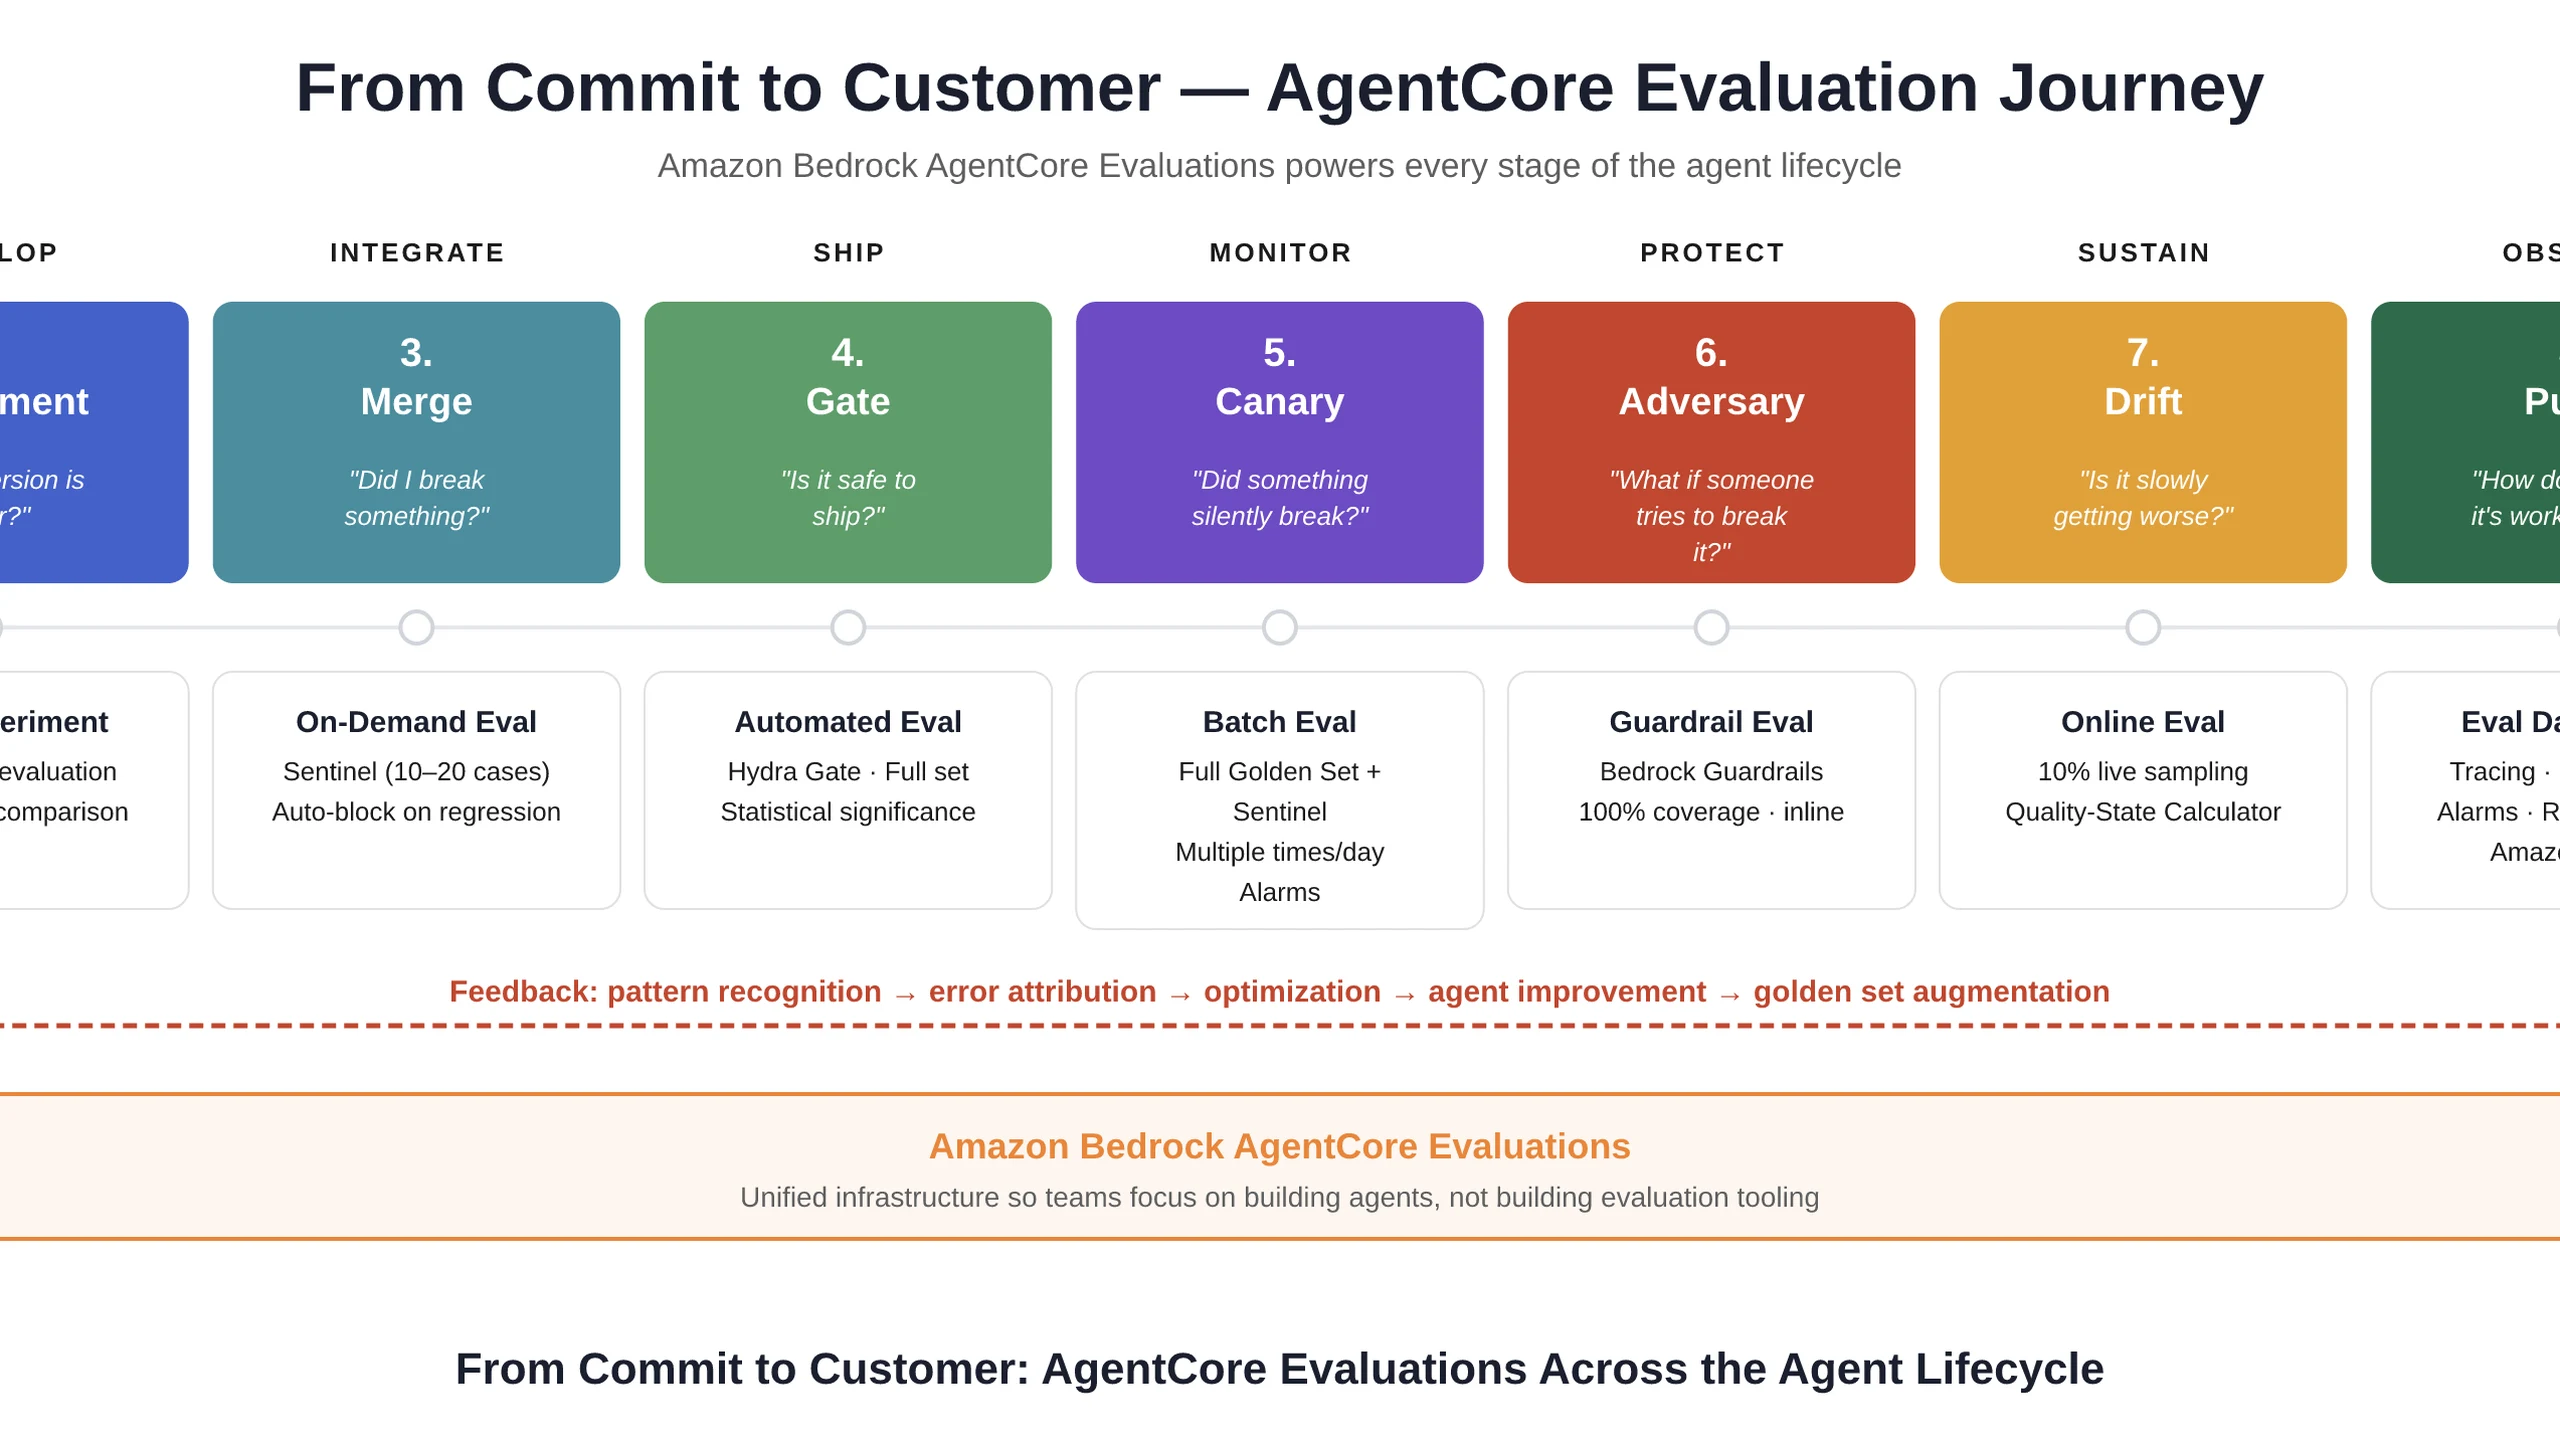
Amazon makes agent evaluation a production control
AWS describes a nine-stage AgentCore evaluation loop that joins CI gates, canaries, live scoring, drift checks, and feedback so an agent can be judged while it is serving users. The reported aim is to catch semantic failures—wrong answers or tool choices—even when latency and error rates look normal.
Amp extends AI agents beyond code with OpenAI models
Amp describes an agent workflow that reaches into planning, writing, design, voice interaction, and the coordination of specialist agents, not only code generation. Its setup assigns OpenAI models to demanding reasoning and real-time interaction while routing narrower tasks to subagents and connecting eligible ChatGPT subscriptions.
Gemini 4 Argon Rollout Goes Global, but Access Still Has Boundaries
Google has moved the Gemini 4 Argon rollout from a controlled preview to global availability within three weeks. Google AI Pro and Ultra subscribers can now access the model through the Gemini app. The change turns Argon from a closely watched research release into a product that paying users can test against real work.
Gemini 4 Argon Rollout Goes Global, but Access Still Has Boundaries
Google has moved the Gemini 4 Argon rollout from a controlled preview to global availability within three weeks. Google AI Pro and Ultra subscribers can now access the model through the Gemini app. The change turns Argon from a closely watched research release into a product that paying users can test against real work.
Apple TV adds room-scale Siri, but older boxes also get the assistant
Apple announced its fourth-generation Apple TV 4K on October 13, with availability planned for November 13. An A19 chip, AV1 decoding and three far-field microphones support conversational entertainment search and hands-free home control. Apple claims up to 50% faster CPU performance and twice the GPU performance; those are company figures, not independent tests. The new hardware can coordinate four compatible HomePods, while earlier models remain limited to two in that configuration.
AlphaProof Nexus: Peer Review Raises the Standard for AI Math
Google DeepMind’s AlphaProof Nexus work has reached peer review, with nine Erdős problems accepted as solved. The result matters less as a raw count than as evidence that generated proofs can move through formal scientific scrutiny.
Microsoft Decision-1 Turns Qwen Into a Fast Control Layer for AI Agents
Microsoft launched Microsoft Decision-1 on October 9, turning Alibaba’s Qwen3.5-9B into a specialized model for rapid, structured decisions. Instead of composing an answer, it selects among predefined options and assigns probabilities that software can act on immediately.
Asana Browser Agent Tests Cut Model Costs 76x With GPT-6.1 Sol
Asana reports browser-agent tests that cut model cost 76x and runtime 5x with GPT-6.1 Sol, making context design central to the result.
Agent Lightning v1.0 separates training from the agent harness
Microsoft Research describes a compact proxy layer that lets reinforcement-learning training observe an existing agent harness instead of rebuilding its tools and execution loop.