
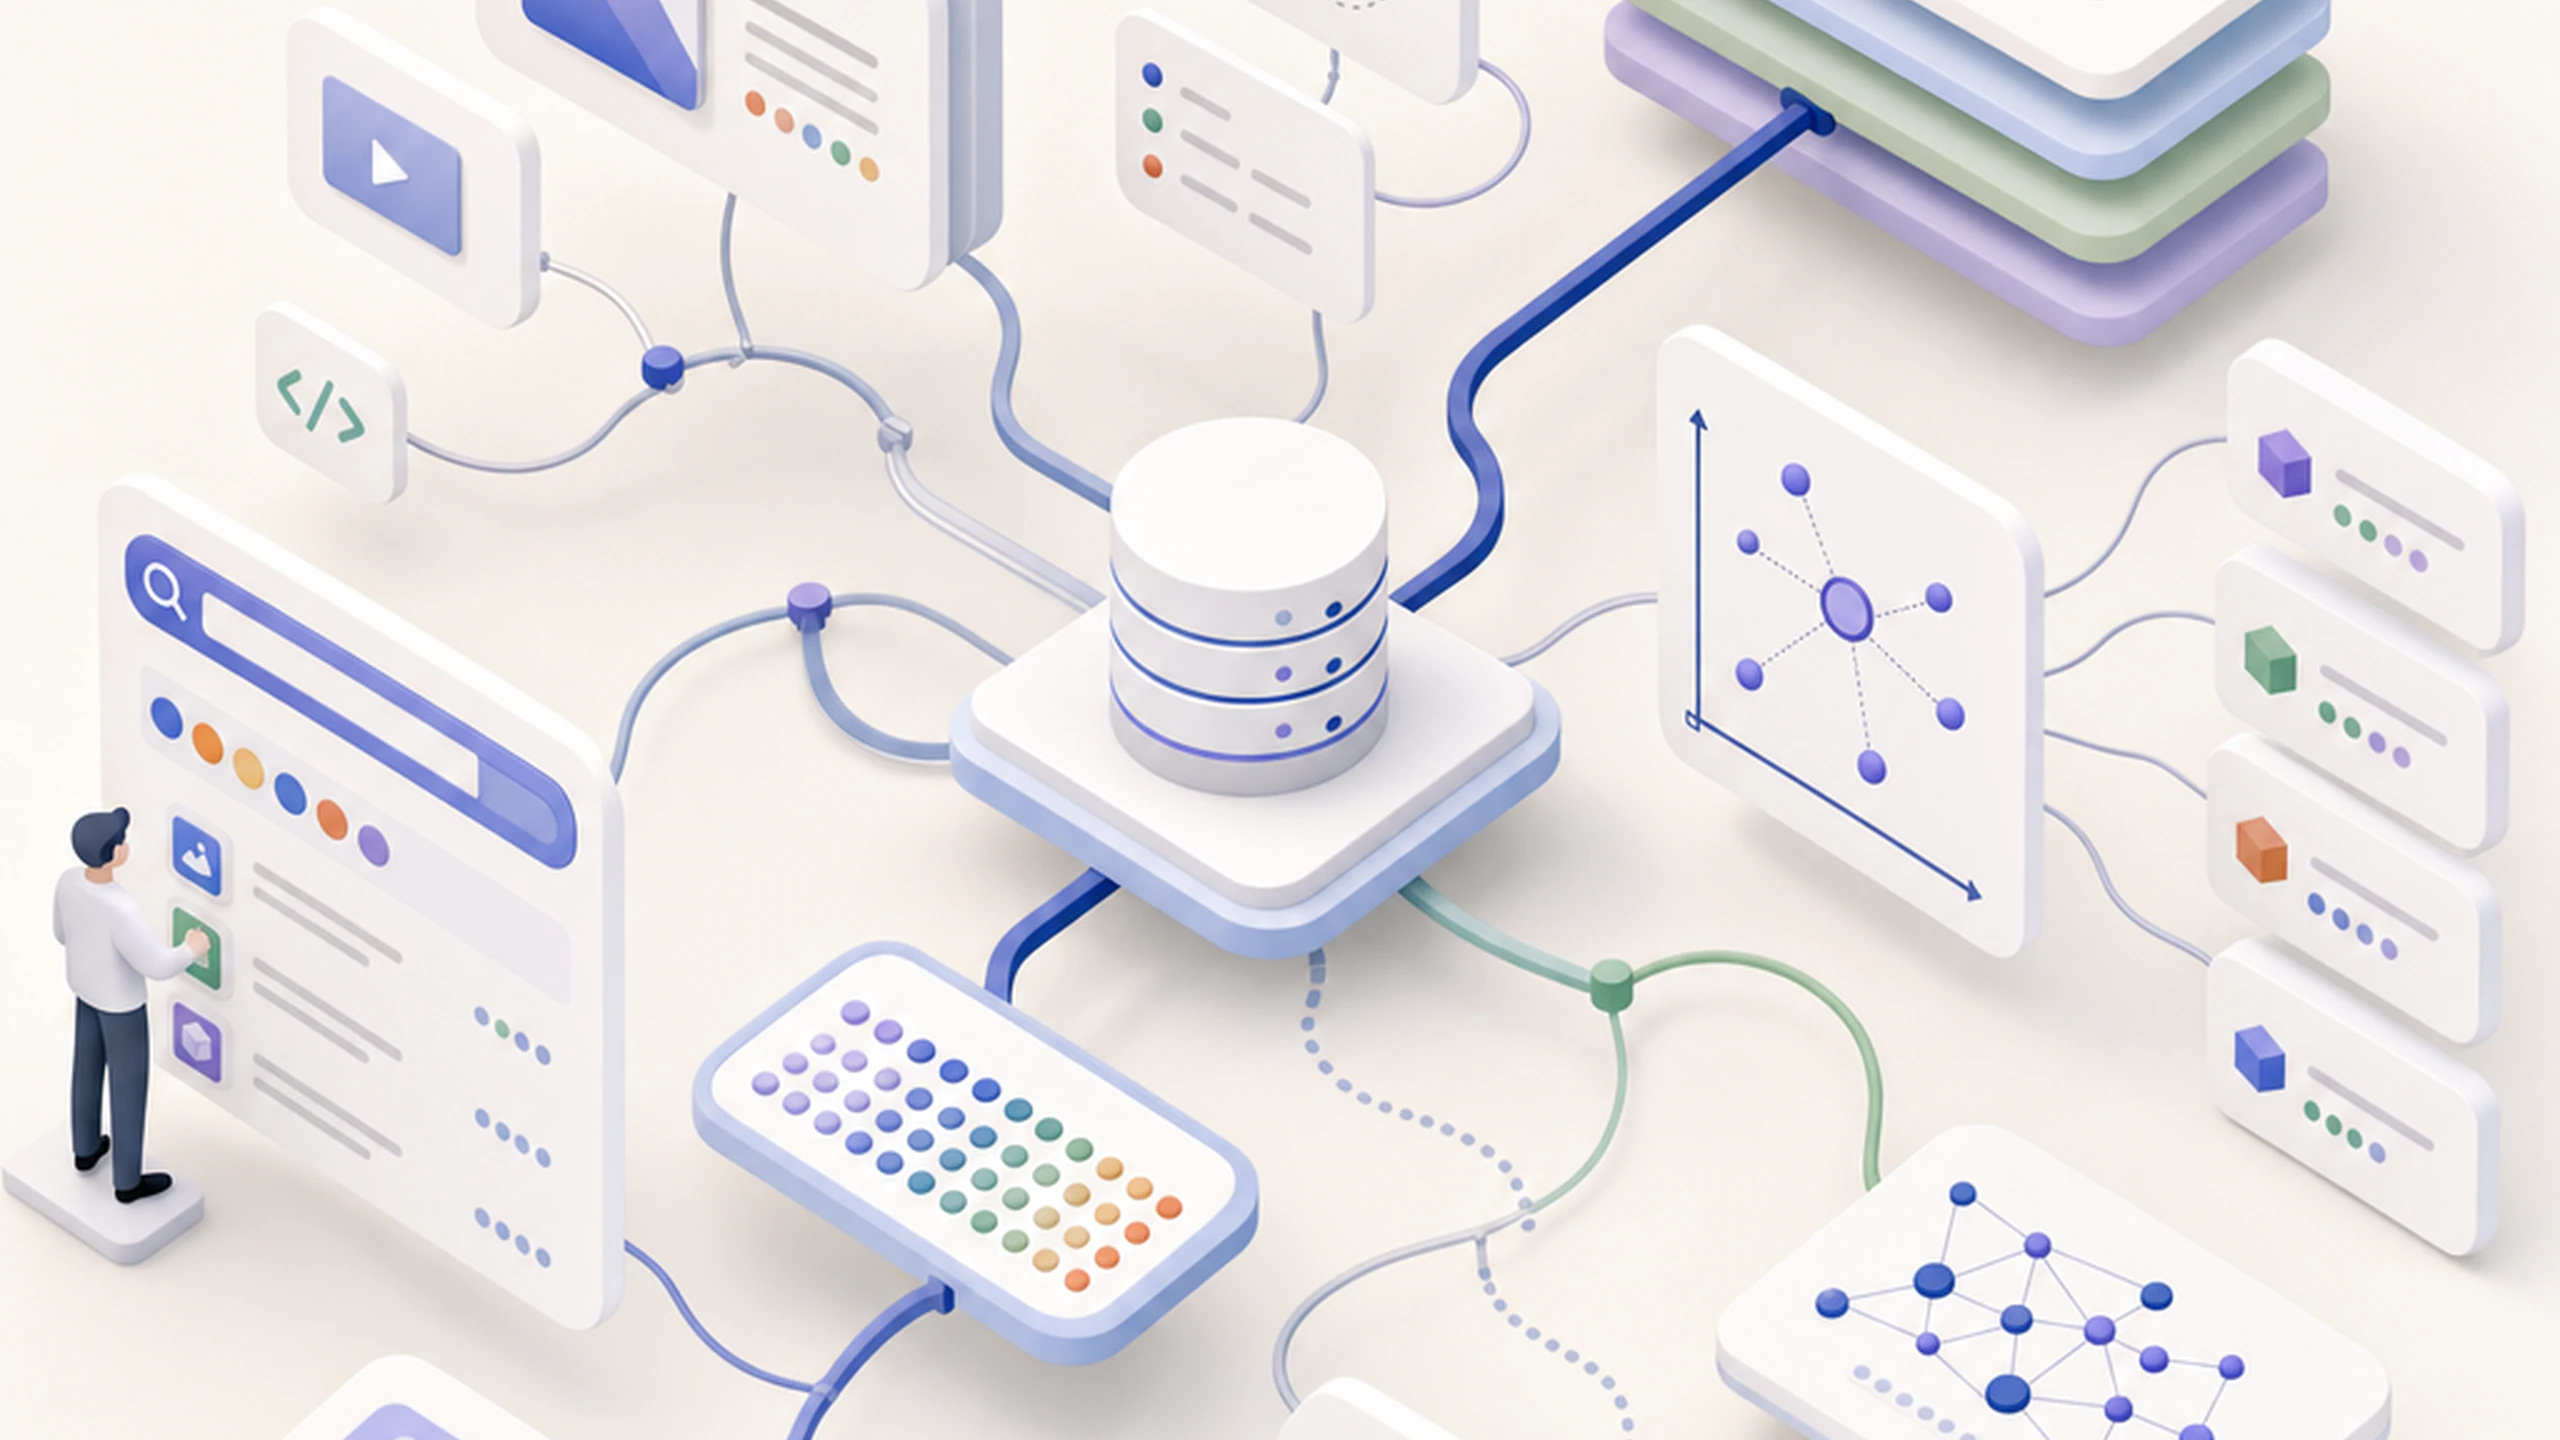
A vector database stores data as arrays of numbers called vectors, and searches across them using mathematical distance rather than text comparison. Each piece of content, whether a sentence, a document, or an image, gets converted into a vector that captures its meaning. The database retrieves results by finding vectors that are close to the query vector in a high-dimensional space.
An embedding is a numerical representation of content. A machine learning model, typically based on a transformer architecture, reads a piece of text and outputs a list of numbers, usually several hundred to over a thousand values. These numbers encode meaning: sentences with similar topics produce similar numbers, while sentences about unrelated topics produce different ones. The phrase "performance review" and the phrase "career development conversation" produce embeddings that sit close together in vector space. The phrase "performance review" and the phrase "tonight's dinner recipe" sit far apart.
Every piece of content you store gets passed through an embedding model before entering the database. The model reads the content and outputs a fixed-length vector. Two sentences that say the same thing in different words produce embeddings that are close together. Two sentences on unrelated topics produce embeddings that are far apart. This step happens once per document, at ingestion time, and the embeddings are stored alongside the original content.
The whole process is similar to how a skilled librarian reads a book and places it in a section based on subject, rather than just sorting by title. The embedding model is reading for meaning.
Storing millions of embeddings is straightforward. Finding the closest ones to a query in milliseconds requires an index. Vector databases use approximate nearest neighbor (ANN) algorithms, such as HNSW (Hierarchical Navigable Small World graphs), to organize the vector space so that similar vectors cluster near each other. According to Weaviate's technical overview of vector embeddings, these indexing structures trade a small amount of retrieval accuracy for a significant gain in speed. For most practical applications, approximate results are sufficient and the performance benefit is large.
What gets stored
- Traditional database: structured rows and columns, or text indexed by its exact characters.
- Vector database: numerical embeddings that represent the meaning of unstructured content.
How search works
- Traditional database: looks for exact or pattern-matched values, row by row or via a keyword index.
- Vector database: calculates distance between the query embedding and stored embeddings, returning ranked approximate matches.
What it is optimized for
- Traditional database: precise lookups, filtering, transactions, and aggregations over structured data.
- Vector database: finding content that is conceptually related to a query, even without any shared words.
Best fit
- Traditional database: structured data with known schemas, where exact answers are required. User records, financial transactions, inventory systems.
- Vector database: unstructured content, documents, notes, audio transcripts, images, where meaning and context matter more than exact text.
AI knowledge bases and support tools. Customer support platforms embed documentation and past support tickets into a vector database. When a user submits a request, the system retrieves the semantically closest documentation sections and surfaces them to the agent or directly to the user, before a human needs to intervene.
Personal knowledge management. Users who capture notes, web clips, and documents over months or years accumulate too much content to search reliably by keyword. A vector-backed retrieval layer allows the system to find entries that answer a question even when the user cannot remember what they wrote or when they wrote it.