
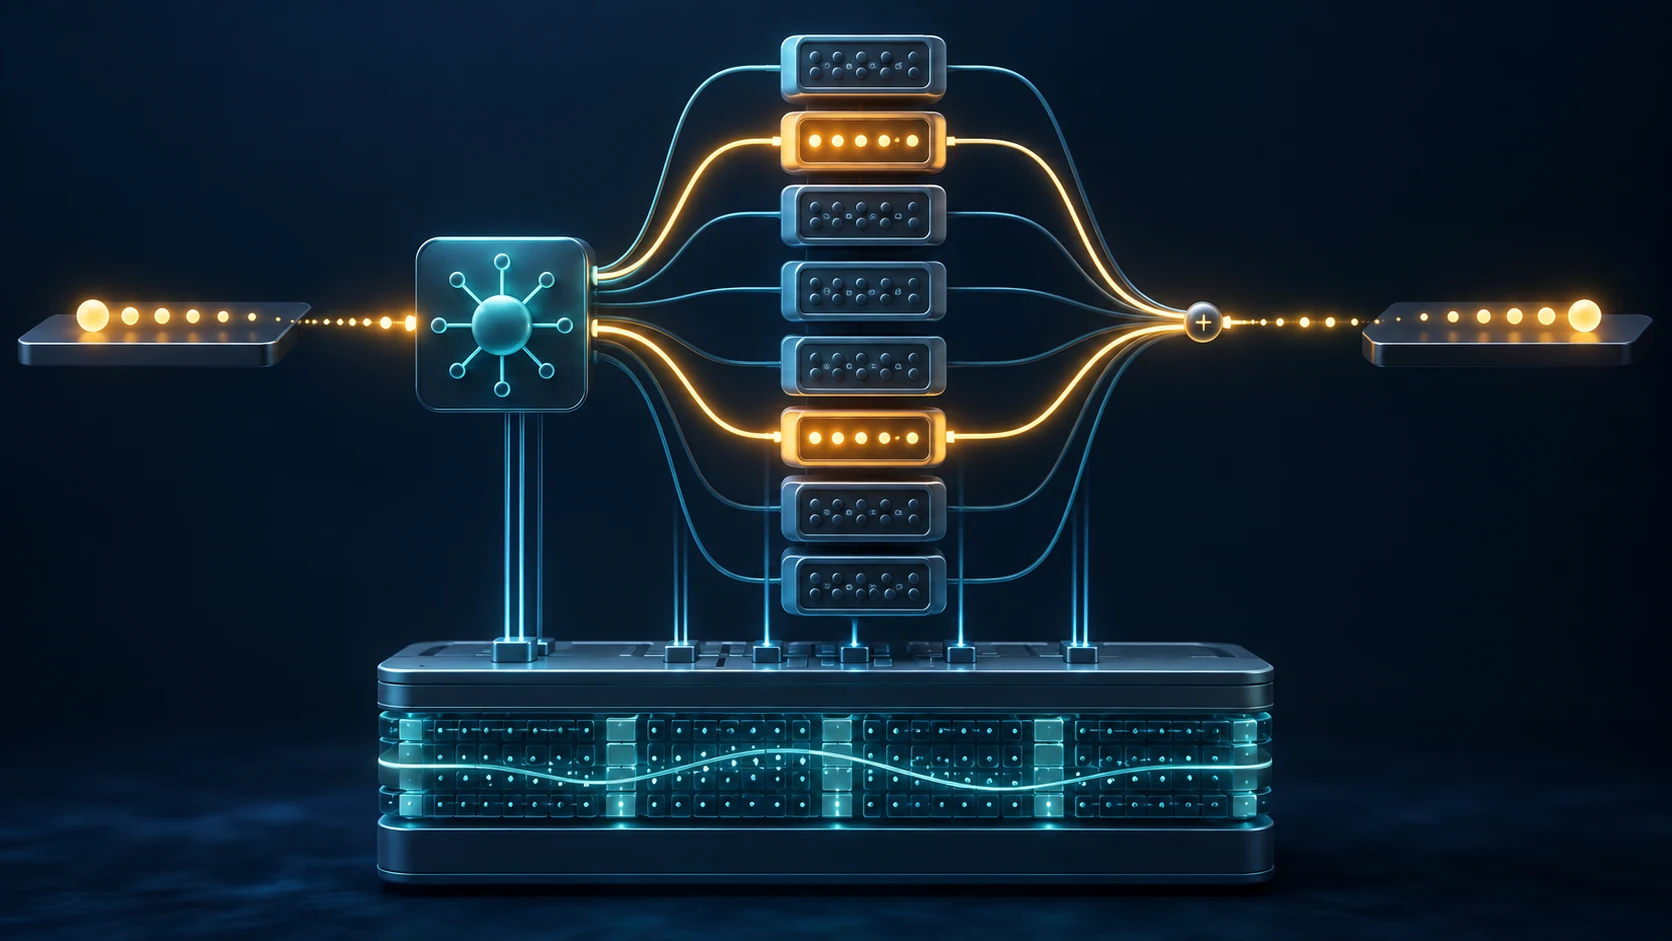
A mixture of experts (MoE) model uses a router to choose which expert networks process each token. In many transformer designs, the experts replace selected feed-forward layers while attention and other components remain shared. This makes it possible to increase the total number of parameters without using every parameter for every token. The design changes compute, memory and communication in different ways; a larger parameter count alone does not tell you what hardware a model needs.
How routing works. Each token reaches a router, which scores the available experts. The model selects a small number of experts, combines their outputs and continues through the shared transformer layers. Different tokens can take different paths. Researchers often use load-balancing techniques so that training does not send most tokens to only a few experts. An expert is a learned network, not necessarily a human-readable “code expert” or “language expert.”
Mixtral as a concrete example. Mistral AI says Mixtral 8x7B has eight experts in its feed-forward blocks and routes each token to two. It reports 46.7 billion total parameters and 12.9 billion active parameters per token. The name does not mean that eight independent 7B models are loaded and two complete models run for each token: some components are shared. The published Mixtral paper and Mistral's release notes describe performance for that model and its tested benchmarks; those results should not be assumed for every MoE.
Compute is not the same as memory. Sparse routing reduces the work done by inactive experts for a token. A conventional deployment still has to store the model's total weights somewhere, so the memory requirement can resemble a much larger dense model even when per-token computation resembles a smaller one. Quantization, CPU or disk offloading, and distributing experts across devices can change the deployment footprint, often with latency or engineering tradeoffs. Measure memory, throughput and latency on the intended hardware rather than estimating all three from active parameter count.
What to check before choosing an MoE model. Compare models on the same tasks, prompts, context lengths and quality measures. Record total and active parameters separately, then test peak memory, latency at the intended batch size and operating cost. Examine how the serving stack handles routing and expert placement. For fine-tuning, confirm that the chosen method supports the model's router and expert layers; the training setup may need load-balancing and careful monitoring.
Is GPT-4 an MoE model? OpenAI has not published enough architectural detail to verify that claim. Do not use GPT-4 as a confirmed MoE example. Mixtral and the research Switch Transformer are documented examples with published architecture descriptions.
Does MoE guarantee a better model? No. It offers a way to increase model capacity while controlling part of the per-token compute. Quality and cost still depend on training, routing, model design and deployment. Choose from measured results for the actual task.
Sources: Mistral AI's Mixtral release, Mixtral paper, Hugging Face's MoE deployment guide, Switch Transformer paper, OpenAI GPT-4 technical report.